> This is part 1 of 2 of the full documentation (pages 1–100 of 101).
> The content is paginated: fetch every part to see all of it.
> Next part: https://docs.binaexperts.com/llms-full.txt/1
> Page index: https://docs.binaexperts.com/llms.txt

# Introduction

BinaExperts is a comprehensive platform that supports the entire computer vision (CV) lifecycle, helping teams achieve successful project outcomes.

&#x20;

Welcome to [BinaExperts](https://binaexperts.com/en), your dedicated partner in mastering every aspect of the computer vision lifecycle. Our platform empowers data scientists, developers, researchers, and organizations with a full suite of solutions and tools designed for each stage of CV development—from data collection and preprocessing to model development, training, deployment, and monitoring.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2Fdk1NbglG9MDXEQwn0OMe%2Fimage.png?alt=media&amp;token=04690ee4-c253-438b-ae39-d2f1012d2e77" alt=""><figcaption><p><a href="https://binaexperts.com/en">Binaexperts</a> machine vision platform</p></figcaption></figure>

[BinaExperts](https://binaexperts.com/en) integrates seamlessly with popular CV frameworks and libraries, enabling your team to build on their existing expertise and workflows while accessing advanced features and capabilities. Our platform streamlines collaboration, accelerates iteration, and drives innovation, ensuring that your computer vision projects deliver impactful results.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FgDI5Vbj1v4CZaoOGaJaG%2Fimage.png?alt=media&amp;token=3b490a3f-fac2-4a38-a486-bb1ae02d5b1c" alt=""><figcaption><p>CV frameworks in <a href="https://binaexperts.com/en">BinaExperts</a></p></figcaption></figure>

Choose [BinaExperts](https://binaexperts.com/en) to stay ahead in today’s rapidly evolving landscape. Discover the features that set us apart and experience the power of a platform designed to exceed the demands of the ever-changing world of computer vision. Together, we can transform your CV projects into groundbreaking successes.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F7Gs5wSSnmPKkPMAHrhdX%2Fimage.png?alt=media&amp;token=723006b1-ffd0-4658-a8c0-71f76fdd3bd3" alt=""><figcaption><p>Features of <a href="https://binaexperts.com/en">Binaexperts </a>machine vision platform</p></figcaption></figure>


# Get Started

Quickstart with BinaExperts

[BinaExperts](https://binaexperts.com/en) provides everything you need to label, train, and deploy computer vision solutions. This guide will help you build a computer vision model for your specific use case.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FEkgHZvZLY48F14gjDpHh%2Fimage%20Get%20Started.jpg?alt=media&amp;token=864a942b-331a-43f8-ab7b-9609a846ec50" alt=""><figcaption><p><strong>Platform pipeline</strong> <a href="https://binaexperts.com/en"><strong>BinaExperts</strong></a></p></figcaption></figure>

## Getting Started with BinaExperts Platform

Quickstart Tutorial (6 Minutes)

&#x20;

**A.  Adding Data**

After reviewing and accepting the terms of service, you will be prompted to choose one of [three plans](https://binaexperts.com/en/pricing): the Public Plan, the Starter Plan, or the Custom Plan.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FyFdWElNCIdIh33tfUje4%2Fimage.png?alt=media&amp;token=e48e6ab6-5d93-4216-8d54-d33b91ac35e5" alt=""><figcaption><p> Public Plan, Starter Plan &#x26; Custom Plan in <a href="https://binaexperts.com/en/pricing">BinaExperts</a></p></figcaption></figure>

&#x20;

**B.  Invite Collaborators**

Next, you'll be asked to invite collaborators to your workspace. Collaborators can help annotate images or manage vision projects. Once collaborators are invited (if desired), you can create a project.

&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2Fq6UFPcztPajEMpVcruE4%2Fimage.png?alt=media&amp;token=b04abcad-f667-4d36-9d40-1ae47866ae70" alt=""><figcaption><p>Invite Collaborators in <a href="https://binaexperts.com/en">BinaExperts</a></p></figcaption></figure>

&#x20;

**C.  Selecting Types of Computer Vision Projects in BinaExperts**

For this example, we'll use a dataset suited for quality assurance in a manufacturing facility. You can use any images you prefer to train your model.

Leave the project type as "Object Detection" since our model will identify specific objects and their locations within an image.

Click Create Project to continue.

For this walkthrough, we’ll use the helmet dataset provided by BinaExperts. Download the “helmet” dataset.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FP9mdjtPJ8PQrL3ARwH0I%2Fimage.png?alt=media&amp;token=257ea95d-597d-4a8c-8096-5d26abf6b984" alt=""><figcaption><p>Selecting Types of Computer Vision Projects in <a href="https://binaexperts.com/en">BinaExperts</a></p></figcaption></figure>

## Uploading the Dataset

Once you've downloaded the dataset, unzip the file. Drag the helmet-dataset folder from your local machine to the highlighted upload area. This dataset is structured in COCO JSON format, one of the 5+ computer vision formats supported by BinaExperts.

To start, we recommend using 5-10 images that balance the classes you want to identify. For example, if you need to identify helmet, ensure there are at least 5-10 images featuring object.

When you upload the helmet-dataset folder, BinaExperts processes the images and annotations for you to view them overlaid.

You can use this guide to build a computer vision model for your unique use case.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FoOkeSWdp62oS7SUEvBO6%2Fimage.png?alt=media&amp;token=7c554984-8a99-4d28-825f-5241f3968205" alt=""><figcaption><p>uploading the helmet-dataset in BinaExperts</p></figcaption></figure>

## Checking and Correcting Annotations

BinaExperts will alert you to any annotation errors. For example, if an annotation improperly extends beyond the image frame, BinaExperts will intelligently crop the annotation to the image's edge and remove erroneous annotations outside the frame.

At this stage, your images haven't been uploaded yet. Ensure all images are correct and that annotations are parsed properly. You can delete any image by hovering over it and selecting the trash icon.

If any image is marked "Not Annotated," it can be annotated in the next section. Click **Save and Continue** to upload your data.

&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FjUR64qfrBjcgYOiyEOQR%2Fimage.png?alt=media&amp;token=b206b956-ba2e-4423-a079-3977f8c6f9ab" alt=""><figcaption><p>annotation in BinaExperts</p></figcaption></figure>

&#x20;

## Choosing a Dataset Split

Decide how to split your images among the Train, Test, and Validation sets.

&#x20;

**Train Set:** Used to train your model.

**Validation Set:** Used to validate model performance during training.

**Test Set:** Used to test model performance manually.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FUImN86NZMJnS3LTowQUh%2Fimage.png?alt=media&amp;token=0624d071-ae01-43b7-beb4-1694dd9398cd" alt=""><figcaption><p>Decide how to split your images among the Train, Test, and Validation sets in BinaExperts</p></figcaption></figure>

Choose the "Use existing values" option to use the pre-split dataset provided by [BinaExperts](https://binaexperts.com/en).

&#x20;

## Uploading Videos

You can upload videos in addition to images. Go to the Upload tab, drag a video or paste a YouTube URL. You'll be asked how many frames per second should be captured. For example, choosing " 1 frame/second" will capture an image every second of the video.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FvISc1Fr9oXaaBXzd5YAJ%2F6.gif?alt=media&amp;token=90301985-ad79-4c47-bab6-ea47e5a8bc3b" alt=""><figcaption><p>For example, choosing " 1 frame/second" will capture an image every second of the video</p></figcaption></figure>

## Annotating Images

Use BinaExperts Annotate to add annotations, such as bounding boxes, around unlabeled objects. These annotations teach your model by serving as an answer key. You can annotate more images to improve model learning. To draw a box, use your cursor to select the area on the image you want to annotate, and then assign a label to it.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FDx2qBKfhshXmuzqazyni%2Fanimation.gif?alt=media&amp;token=caf659cf-0d6e-4bc2-8271-e46e345ed4a0" alt=""><figcaption><p>add annotating in BinaExperts</p></figcaption></figure>

{% hint style="info" %}
Pro Tip: Use [BinaExperts](https://binaexperts.com/en) AutoLabel to utilize previous model versions for annotating future datasets. AutoLabel leverages an existing model to create annotations automatically, accelerating the process.
{% endhint %}

BinaExperts also supports polygon annotations, which are necessary for projects requiring precise object localization. To use Polygon, click the sparkles icon in the sidebar.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FZ1yPRw6AQCxWMWwTBSSC%2Fimage.png?alt=media&amp;token=e1a1833c-373b-43b4-8840-df9dc5064b24" alt=""><figcaption><p>BinaExperts supports polygon annotations</p></figcaption></figure>

&#x20;

## Adding Images to the Dataset

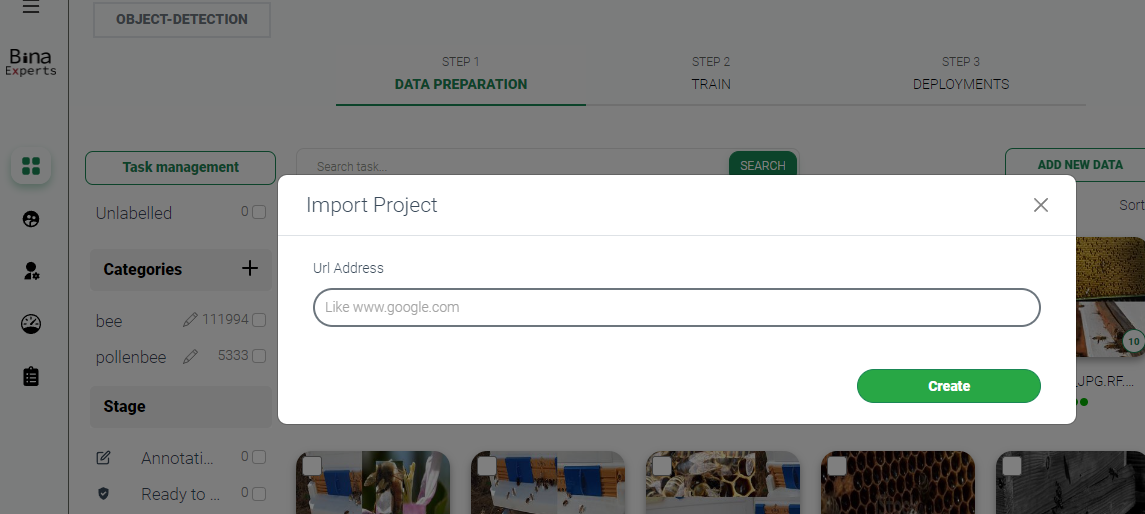
To add images or data to the dataset, click the Add New Data option.

&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FKxwZBNRMbrcM6X43JZfz%2Fimage.png?alt=media&amp;token=8d470fe5-2132-45fe-a286-719ae0af98a8" alt=""><figcaption><p>adding images to the datasets </p></figcaption></figure>

## Preprocessing and Augmentations

Once annotations are complete, generate a new dataset version. This snapshot includes images processed in a specific way, similar to version control for data.

&#x20;

You can apply preprocessing and augmentations, such as resizing, grayscaling, random flips, rotations, brightness adjustments, blurring, shearing, cropping, and more. Begin with one or two augmentations and adjust as needed. Generally, avoid augmentations in the first training job to assess the model's performance.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2Fn7qeBrJMZgTgQdllrmFF%2Fimage.png?alt=media&amp;token=d6f9b5f3-ec68-4020-ba33-9c35c99e6971" alt=""><figcaption><p> apply augmentations</p></figcaption></figure>

{% hint style="info" %}
Tip: Some augmentations may not suit your data. Consider the specific use case before applying them. For example, if the object appears only in one orientation (like on an assembly line), flipping may not be helpful.
{% endhint %}

Click Create to generate your dataset, and it will be ready for use in a few moments.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FNhuJ2JKA8sqLzfuW18hW%2Fimage.png?alt=media&amp;token=c0d71db7-12c4-47e2-8eba-2018b35abd3f" alt=""><figcaption><p>augmentations in BinaExperts</p></figcaption></figure>

## Training Your Model

To train a model on the BinaExperts platform:

&#x20;    I.        Click the Train button.

&#x20;   II.        Configure your model training job.

&#x20; III.        Choose a model type. For this guide, select 'Fast.'

&#x20; IV.        Select the checkpoint for training.

&#x20;  V.        Monitor training progress through real-time graphs.

&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FJMwIz8wgYY92t1sXLbL6%2Fimage.png?alt=media&amp;token=29b1be0f-6832-4087-a31a-ae4fec2e126f" alt=""><figcaption><p>train a model on the BinaExperts platform</p></figcaption></figure>

&#x20;

You'll receive an email with training results once training is complete.

&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FrkpPUyJM9MpDpii7jY1V%2Fimage.png?alt=media&amp;token=1b0b5360-afe8-486d-b154-ff2bd80ceb8b" alt=""><figcaption><p>training results once training is complete</p></figcaption></figure>

## Deploying a Computer Vision Model

Your trained model is optimized and ready for deployment. BinaExperts supports various deployment options, such as API integration or edge device deployment.

&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FckSdlD7kmVg0KAmLKtgX%2Fimage.png?alt=media&amp;token=87cc6ee7-e22b-4e31-8e43-d28ffbb9e208" alt=""><figcaption></figcaption></figure>

&#x20;

With BinaExperts Hosted API (Remote Server), the model runs in the cloud, eliminating the need to worry about device hardware capabilities.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FGsbU4345UlOrVv2Er0xN%2Fimage.png?alt=media&amp;token=cdf0daca-330a-46ae-9278-5994d7cbd363" alt=""><figcaption><p>Your trained model, hosted by BinaExperts, is optimized and ready for <a href="/deployment/deployment/deployment-model-triton">deployment</a> across various deployment options.</p></figcaption></figure>

You can also deploy models using other options suitable for your production applications. For details, refer to our deployment guide.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FQP41oktJ4g6HpluzYgmU%2FScreenshot%20(1015).png?alt=media&amp;token=8d5e8882-695c-4851-a23d-6f813f4e3374" alt=""><figcaption><p>View your training graphs for a detailed analysis of model performance.</p></figcaption></figure>

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FcVw2DTGka4NH3uJNcjvI%2F36.JPG?alt=media&amp;token=5f4c2dc3-0559-4423-b2d3-7c76dc80e3d9" alt=""><figcaption><p>Your trained model, hosted by BinaExperts, is optimized and ready for <a href="/deployment/deployment/deployment-model-triton">deployment</a> across various deployment options.</p></figcaption></figure>


# Create an Organization

Create an organization where projects are grouped together.

&#x20;All computer vision projects in [BinaExperts](https://binaexperts.com/en) belong to a workspace. When you sign up for a BinaExperts account, a workspace is automatically created for you.

&#x20;

Workspaces allow you to manage who has access to which projects and what features are available for the projects within the workspace.

&#x20;

## Create a New Organization

After logging in, to create a new organization, click on **ADD NEW ITEM**.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FlypNHL6tJCyDVZ5gye9I%2Fimage.png?alt=media&amp;token=bfe7072a-c0c7-4264-98cc-069bba5502bc" alt=""><figcaption><p>create a new organization in <a href="https://binaexperts.com/en">BinaExperts</a></p></figcaption></figure>

Within your organization, you can search for your projects, import and merge them, and define access levels for specific members.

&#x20;

Additionally, in the sidebar, you can view:

&#x20;

A.   The list of members

B.   Training resource consumption

C.   Profiles

D.   Organization logs related to model training

In your organization, you can search for your projects, import and merge them, as well as define access levels for desired members.


# Add Team Members

Add Team Members to Your BinaExperts Organization

Collaborate effectively on your projects by inviting team members to your [BinaExperts](https://binaexperts.com/en) Organization. Here’s how you can easily add them:

1. **Access Workspace Settings**: Navigate to the settings of the specific workspace where you want to add team members.
2. **Invite Members**: In the “Organization Members” section, enter the email address of the team member you wish to invite.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FmElaqnwzCnK6qcdhTor1%2Fimage.png?alt=media&amp;token=5b587734-7e15-4097-83c5-55f8b939eb08" alt=""><figcaption><p><strong>Invite Members in</strong> <a href="https://binaexperts.com/en"><strong>BinaExperts</strong></a></p></figcaption></figure>

3. **Send Invitation**: After entering the email address, send the invitation email directly from the platform.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F9MaluSJJQluK8GVVQVtj%2Fimage.png?alt=media&amp;token=67b33759-90c5-43bb-8fa6-cdc119f8ad5b" alt=""><figcaption><p><strong>Send Invitation in</strong> <a href="https://binaexperts.com/en"><strong>BinaExperts</strong></a></p></figcaption></figure>

4. **Complete Registration**: The invited team member will receive an email with a registration link. They can complete the process by following the instructions in the email.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FOafyUX8pUQez7Iw0dysX%2Fimage.png?alt=media&amp;token=64033b73-23b8-4ce5-b96c-fb1c071f6fce" alt=""><figcaption><p><strong>Complete Registration</strong></p></figcaption></figure>

By following these steps, you can seamlessly expand your team and enhance collaboration within your [BinaExperts](https://binaexperts.com/en) Organization.


# Role-Based Access Control

Role-Based Access Control in BinaExperts

With Role-Based Access Control (RBAC), you can manage permissions within your organization effectively. By clicking on **"Add New Group"** you can create groups and precisely define the access levels for each member across different cases.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2Fy8ZIlvGe02Ve73W0hTjq%2FRec%200011.gif?alt=media&amp;token=5c6e74b2-e2a7-411c-9b9e-88fa56b83b8c" alt=""><figcaption><p>Role-Based Access Control in <a href="https://binaexperts.com/en">BinaExperts</a></p></figcaption></figure>

For each user, you can assign any of the following permissions:

&#x20;

·         Bulk inference access

·         Cancel train access

·         Create dataset access

·         Create dataset version access

·         Create deployment access

·         Create group access

·         Create inference access

·         Create organization access

·         Create task access

·         Create training access

·         Delete dataset access

·         Delete dataset version access

·         Delete deployment access

·         Delete group access

·         Delete inference access

·         Delete organization access

·         Delete task access

·         Delete training access

·         Deployment manager: Create deployment access

·         Deployment manager: Download access

·         Deployment manager: Inference access

·         Deployment manager: Load, unload, reload deployment access

·         Download configuration access

·         Download model access

·         Download test images access

·         Download validation images access

·         Export dataset access

·         List organization images access

·         Organization user: Change activity status access

·         TensorBoard training access

·         Update dataset access

·         Update dataset version access

·         Update deployment access

·         Update group access

·         Update inference access

·         Update organization access

·         Update task access

·         Update training access

**Alternatively,  in** [**BinaExperts**](https://binaexperts.com/en) **you can grant all of these permissions to a user.**


# Creating a Project

Creating a Project in BinaExperts

A project serves as the central repository for your images and annotations within a workspace. Once images are annotated, you can generate a version (a snapshot of your images and annotations at that moment)augmented and processed according to your selected configuration.

A project includes:

·         **Name:** The title of your project.

·         **Type:** The nature of the project (e.g., Object Detection).

·        **Annotation Group:** The group responsible for annotating the images.

Steps to Create a Project:

A.   **Access the** [**BinaExperts**](https://binaexperts.com/en) **Dashboard:** Begin by logging into the [BinaExperts](https://binaexperts.com/en) dashboard.

B.   **Create a New Project:** Click on "Create New Project." You will be prompted to provide the following details:

·        **Dataset Type:** Choose the type of project. Here’s a brief overview of each type:

o   ***Object Detection:*** Identifies and locates objects within an image.

o   ***Multi-Label Classification:*** Assigns multiple relevant labels to an image from a predefined set of categories.

o   ***Instance Segmentation:*** Pinpoints the location of objects in an image down to the pixel level.

·        **Project Name:** Enter a meaningful name for your project.

·         **Project Tags and Description:** Provide tags and a description for better organization and understanding of the project’s purpose.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FtbFfbtJffevE3xODNX0M%2Fimage.png?alt=media&amp;token=f7ff9105-38ad-48a7-800e-b9b07eb38178" alt=""><figcaption><p><strong>Project Tags and Description in</strong> <a href="https://binaexperts.com/en"><strong>BinaExperts</strong></a></p></figcaption></figure>

&#x20;

C.  **Submit the Form:** After entering the required details, submit the form to create your project.

D. **Suggest New Project Types:** If you would like to see additional project types supported, you can indicate your interest by selecting the appropriate option from the project type dropdown menu.


# Uploading Data

Uploading Data in BinaExperts.

**Using the Web Interface (Best for ≤1000 Images)**

**Upload Data via the Web Interface**

To upload data, you need to have a project. If you haven’t created one yet, start by creating a project. During the project creation process, you will be prompted to upload images.

If you already have a project, simply click "Upload" in the project sidebar to add more images.

Supported Data Types

[**BinaExperts**](https://binaexperts.com/en) **supports the following data formats:**

***Images:*** JPG, PNG, WEBP, and BMP

***Videos:*** MOV and MP4

***Data formatted for classification, object detection, segmentation, and keypoint detection in any supported format.***

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F0WoP50taVu3nsSK5l2Rx%2Fimage.png?alt=media&amp;token=296395d5-cae1-4807-ae38-22f1878436e9" alt=""><figcaption><p><a href="https://binaexperts.com/en">BinaExperts</a> <strong>supports</strong> various <strong>data formats</strong></p></figcaption></figure>

&#x20;

**Accessing Public Datasets**

[BinaExperts Hub](https://binaexperts.com/en/hub) offers a repository of over 10,000 datasets covering tasks like object detection, classification, and segmentation. You can use the Hub to find datasets for training the initial version of a model or for fine-tuning an existing model.


# Uploading Video

Uploading Video in BinaExperts.

The highest **frame rate** you can select is 60 frames per second, which will generate 60 images for each second of video you upload. The lowest frame rate you can select is 1 frame per 60 seconds.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FOg0Le6tglWEhJrjj53qF%2F6.gif?alt=media&amp;token=88acd6f1-b1a0-4d84-b229-4d7af7df84e2" alt=""><figcaption><p>The highest <strong>frame rate</strong> you can select is 60 frames per second, which will generate 60 images for each second of video you upload.</p></figcaption></figure>

&#x20;

After sampling your video, the extracted frames will appear as if you had originally uploaded individual images to [BinaExperts](https://binaexperts.com/en).

You can also directly import a YouTube video by pasting the YouTube link on the Upload page, following a similar process.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FhOEDNzpBMHvo9398pO3E%2Fimage.png?alt=media&amp;token=45cfce73-44e5-416c-a369-6cc3e1808c41" alt=""><figcaption><p>You can embed a video from YouTube directly by entering its link on the upload page.</p></figcaption></figure>

&#x20;

**Supported Video Formats**

[BinaExperts](https://binaexperts.com/en) relies on your browser's built-in support for video files to parse them into frame images, which can then be used to train your models. This means you can use a variety of video formats, including MOV and MP4, depending on your browser.

&#x20;

Please note that certain formats, such as HEVC/H. 265 encoded MP4 files, are only supported by the Safari browser. If you are importing videos from devices like a GoPro or iPhone that record in H. 265, consider changing the settings to H. 264 for broader compatibility.

&#x20;

If you encounter issues loading your video file into [BinaExperts](https://binaexperts.com/en), please contact support at <help@BinaExperts.ir>.


# Manage Batches

An Introduction to Batches in BinaExperts.

## Batches in BinaExperts

Once you upload your data to [BinaExperts](https://binaexperts.com/en), the uploaded data becomes a batch. Batches are groups of images that you can easily track throughout the dataset process in BinaExperts. You can monitor this process on the Annotate page.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FQjW49qLQVg0NYhou1Lut%2F40.JPG?alt=media&amp;token=17506f61-f756-4358-b52f-381125ff6d1d" alt=""><figcaption><p>Manage Batches in <a href="https://binaexperts.com/en">BinaExperts</a></p></figcaption></figure>

## Managing Batches

·        Once images are uploaded, they appear in the "Unassigned" column.

&#x20;       o   You can assign the batch to someone for annotation, moving it to the "Annotating" column.

·        If you assign only part of the batch, the remaining images will be placed in a new batch in the "Unassigned" column.

·        After the annotation is completed, the batch is either sent to the "Review" column (for users with review permissions) or to the "Dataset" column.

·        In the "Review" column, batches are either approved or rejected. Approved batches move to the "Dataset" column, while rejected batches return to the "Annotating" column for further work.

&#x20;

## Deleting a Batch

{% hint style="danger" %}
Note: Deletions are permanent and cannot be undone. Please ensure you are certain before proceeding.
{% endhint %}

You can delete batches by marked the image next to the batch name and clicking "**Delete Batch**".

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2Fo71yIPnwEBzC0H6jyQNM%2FScreenshot%20(1018).png?alt=media&amp;token=2251e8e3-3cea-4363-9240-a3949c02f29d" alt=""><figcaption><p>Delete Batch in <a href="https://binaexperts.com/en">BinaExperts</a></p></figcaption></figure>

Batch deletion behaves differently depending on where the batch is in the annotation process:

**Unassigned Column:** If the batch is in the "Unassigned" column, both the batch and the images within it will be permanently deleted from the project.

**Annotating, QC, Dataset Columns:** If the batch is in one of these columns, it will be moved back to the "Unassigned" column, and all annotations associated with the images will be removed.

·        To fully remove a batch from these columns, you must click "**Delete Batch**" twice: first to move it back to the "Unassigned" column, and then again to delete it from the "Unassigned" column.

·        This process is required if you wish to relabel a batch. &#x20;


# Create a Dataset Version

Creating a dataset version allows you to prepare your data for training a model.

A dataset version is a point-in-time snapshot of your dataset. By keeping track of the exact images, preprocessing steps, and augmentations used in each model iteration, you maintain the ability to reproduce results. This ensures that you can scientifically test various models and frameworks while confidently attributing results to model changes, not to bugs or changes in the data pipeline.

{% hint style="info" %}
Once a version is created, it is frozen in time. This means that any subsequent changes to the project (such as adding or removing images, annotations, or other data) will not affect previously created versions.&#x20;
{% endhint %}

## How to Create a Dataset Version

To create a dataset version:

&#x20;    I.        Click "Versions" in the sidebar of your [BinaExperts](https://binaexperts.com/en) project.

&#x20;  II.        Click "Build New Version".

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FipnHpz2tSGtMmqbLf80W%2F43.JPG?alt=media&amp;token=69b9474c-5c2b-468c-92e6-83a868861cbe" alt=""><figcaption><p>create a dataset version in <a href="https://binaexperts.com/en">BinaExperts</a></p></figcaption></figure>

From this page, you can:

·        Set the train/test/validation split.

·        Specify preprocessing steps.

·        Define augmentations for your new dataset version.

After specifying the preprocessing steps and augmentations you want to apply, click "**Build Train-Ready Version**". This will generate a new dataset version. You can then use this dataset version to train a model in [BinaExperts](https://binaexperts.com/en) or export it for manual model training.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FH2ViGbVZ1u6eE6uua7lV%2F44.JPG?alt=media&amp;token=39c443d0-7200-4aa2-9014-1260191f6aea" alt=""><figcaption><p>train/test/validation split in <a href="https://binaexperts.com/en">BinaExperts</a></p></figcaption></figure>

## Adjusting Train/Validation/Test Splits

During the version creation process, you can readjust the balance of your training, validation, and test sets. To do this:

·        Go to "**Step 4: Train/Test Split**".

·        Click on the option to adjust the split settings.


# Preprocessing Images

Image preprocessing steps are essential to prepare data for models.

Preprocessing ensures your dataset is standardized, for example, by ensuring all images have consistent dimensions. This step is crucial to maintain dataset consistency before training a model.

Preprocessing is applied across all images in your Train, Validation, and Test sets (unlike augmentations, which apply only to the Train set).

The [BinaExperts](https://binaexperts.com/en) platform offers the following preprocessing options:

**·        Auto-Orient**

**·        Resize**

**·        Grayscale**

**·        Auto-Adjust Contrast**

**·        Isolate Objects**

**·        Static Crop**

**·        Tile**

**·        Modify Classes**

**·        Filter Null**

**·        Filter by Tag**

Each option is described in detail below.

## Auto-Orient

The Auto-Orient option removes the EXIF data from your images, ensuring they are displayed in the same orientation as they are stored on disk.

EXIF data defines the orientation of an image. Some applications (such as Preview on Mac) use this data to display an image in a particular orientation, even if its storage orientation differs. This discrepancy can cause issues with object detection models. For more details, refer to the Hacker News discussion on this issue.

[BinaExperts](https://binaexperts.com/en) recommends keeping this option enabled and reviewing how your images are processed during inference.

For more insights on whether you should auto-orient your images, check out our blog.

## Resize

The Resize option alters your images' dimensions, optionally scaling them to a specified size. Annotations are adjusted accordingly, except when using the **“fill”** option.

Currently, only downsizing is supported. Below are the available resizing methods:

**Stretch to:** Stretches the image to the desired dimensions, scaling annotations proportionally. The image will be square but distorted, with no loss of source image data.

**Fill (with center crop):** Crops the central portion of the source image to fit the desired dimensions. The aspect ratio is maintained, but some source image data will be lost.

**Fit within:** Resizes the image to fit within the desired dimensions while maintaining the original aspect ratio. Source image data is preserved, but the image may not be square.

**Fit (reflect edges):** Resizes the image to fit the desired dimensions while maintaining the original aspect ratio, with reflected padding to fill any remaining space. Annotations are reflected accordingly.

**Fit (black edges):** Similar to the previous option but with black padding instead of reflected content.

**Fit (white edges):** Similar to the previous option but with white padding instead of reflected content.

## Grayscale

This option converts an image with **RGB** channels to a single grayscale channel, potentially saving memory. The grayscale value for each pixel is calculated as a weighted sum of the **red**, **green**, and **blue** pixel values:

Y=0.2125R+0.7154G+0.0721BY = 0.2125R + 0.7154G + 0.0721BY=0.2125R+0.7154G+0.0721B

These weights are derived from the human perception of red, green, and blue, and are commonly used in display technology.

## Auto-Adjust Contrast

Auto-Adjust Contrast enhances images with low contrast. [**BinaExperts**](https://binaexperts.com/en) offers the following methods for contrast adjustment:

**Contrast Stretching:** Rescales pixel intensities between the 2nd and 98th percentiles.

**Histogram Equalization:** Redistributes the most frequent intensity values, resulting in a more uniform pixel distribution.

**Adaptive Equalization:** Applies Contrast Limited Adaptive Histogram Equalization (CLAHE), which enhances local contrast in image regions. This is useful for improving details in images with high variability in brightness.

## Advanced Preprocessing Features

> These features are available for [Public Workspaces, licensed Starter Plan, and Enterprise accounts](https://binaexperts.com/en/pricing). Users on Sandbox Workspaces needing access to these features should [contact sales](https://binaexperts.com/fa/contact-us).

## Isolate Objects

The Isolate Objects transformation crops and extracts each object bounding box into individual images. This is useful for converting object detection datasets into classification datasets.

For datasets where many classes are similar, it is common to use two models in sequence: the first for object detection and the second for classification. This transformation helps create the dataset for the second model.

## Tile

Tiling can be useful for detecting small objects, especially in scenarios like aerial imagery or microscopy. The default is 2x2 tiling, but this can be adjusted as needed.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FmZhCbBfLiG5tBUYQtrCR%2F19.JPG?alt=media&amp;token=aa331738-770c-407f-af18-ca72843b3413" alt=""><figcaption><p>Tilling in <a href="https://binaexperts.com/en">BinaExperts</a></p></figcaption></figure>

## Filter by Tag

The Filter by Tag option allows users to include or exclude images based on their assigned tags. This is helpful for training models on a specific subset of data or excluding unwanted images from the dataset.


# Creating Augmented Images

Creating augmented images is a critical step to enhance model performance by improving its ability to generalize to unseen data.

Image augmentation involves applying transformations to the existing images in your dataset. This process can help your model generalize better and perform more effectively on new, unseen images.

## Supported Augmentations in[ BinaExperts](https://binaexperts.com/en):

**·        Flip**

**·        90-degree rotation**

**·        Random rotation**

**·        Random crop**

**·        Random shear**

**·        Blur**

**·        Exposure adjustment**

**·        Random noise**

**·        Cutout (available in paid plans only)**

**·        Mosaic (available in paid plans only)**

## Recommendations for Starting a Project:

{% hint style="success" %}
We recommend beginning your project without any augmentations. This approach helps you evaluate the quality of your raw dataset. If your dataset's performance is suboptimal with augmentations, you will not have a clear baseline for comparison.

If your model does not perform well without augmentations, you should first investigate factors like class balance, data representation, and dataset size. Once your model performs satisfactorily on the raw dataset, you can add augmentations to further enhance its performance.
{% endhint %}

## Creating Augmented Images Before Training

Conducting augmentations offline (prior to training) offers several benefits:

1. &#x20; **Improved Model Reproducibility:** [BinaExperts](https://binaexperts.com/en) keeps a record of how each image was augmented, allowing you to trace back augmentation settings. For instance, if your model performs better on brighter images, you can identify the need for more low-light training data.

2. &#x20;**Reduced Training Time:** Augmentations are CPU-intensive operations. When augmentations are performed on-the-fly during training, your GPU may often wait for your CPU to generate augmented data for each epoch, slowing down the process.

3. &#x20;**Lower Training Costs:** As augmentations are CPU-bound, performing them offline can reduce the waiting time for your GPU, making your training process more efficient and cost-effective.

## Adding Augmentations

To add augmentations, navigate to the "Versions" tab in your project’s dashboard on [BinaExperts](https://binaexperts.com/en). Click on "Augmentations" to set up your desired augmentation parameters.

{% hint style="info" %}
You can specify how many times each image should be augmented. For instance, selecting "3" means that each image will be augmented twice based on your settings, resulting in three versions of each source image.
{% endhint %}

## How Augmentations Are Applied

Augmentations are chained together with random settings applied to each image. Duplicates generated during this process are filtered out.

For example, if you choose "flip horizontally" and "add random noise," an image may be randomly flipped and then have noise applied.

## Augmentation Options and Customization

Below are the available augmentations in [BinaExperts](https://binaexperts.com/en) and their customizable parameters:

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FQEGYersX1M17eNEdsc8S%2FRec%200006%20(1).gif?alt=media&amp;token=64b3ce95-1222-4229-b45a-8892bcde1981" alt=""><figcaption><p>available augmentations in <a href="https://binaexperts.com/en">BinaExperts</a> and their customizable parameters</p></figcaption></figure>

1. **Flip:** Randomly flip images vertically or horizontally with correctly mirrored annotations.

·        **Horizontal:** Flips the image left-to-right.

·        **Vertical:** Flips the image top-to-bottom.

2. **90-Degree Rotations:** Rotate images by 90 or 180 degrees.

·        **Clockwise:** Rotates 90 degrees clockwise.

·        **Counter Clockwise:** Rotates 90 degrees counter-clockwise.

·       **Upside Down:** Rotates 180 degrees.

3. **Random Rotation:** Rotate images randomly up to a specified degree. Note that annotations may be cropped if they are partially out of frame.
4. **Random Shear:** Distorts images horizontally or vertically.

·        **Horizontal:** Maximum shear along the x-axis.

·       **Vertical:** Maximum shear along the y-axis.

5. **Blur:** Applies Gaussian blur to the image.

·        **Pixels:** Determines the intensity of blur (maximum of 25 pixels).

6. **Random Noise:** Adds salt-and-pepper noise to the image.

·        **Percent:** The percentage of pixels affected (up to 25%).

7\. **Color Adjustments:**

·       **Hue, Value, Saturation (HVS):** Modifies the color appearance of images.

·       **Contrast:** Alters the difference between light and dark areas.

8. **Weather Effects:**

·       **Snow:** Simulates snow-like conditions.

·        **Fog:** Adds foggy or misty effects.

·        **Rain:** Simulates raindrop effects.

·      **Sun:** Introduces sunlight effects, altering brightness and warmth.

These augmentation options allow you to generate diverse variations in your dataset, enhancing model robustness and improving generalization to real-world scenarios.


# Add Tags to Images

Enhance your dataset organization with image tagging.

[BinaExperts](https://binaexperts.com/en) offers an image tagging feature that enables you to assign tags to images during upload. These tags can be used for batch labeling, ensuring greater accuracy when selecting images for labeling tasks. Additionally, image tags serve as a filter in the [BinaExperts](https://binaexperts.com/en) dataset search, helping you efficiently manage and locate specific images within your dataset.

&#x20;

## Filter Images by Tag

On the [BinaExperts](https://binaexperts.com/en) dashboard's Assign page, you can filter images based on their assigned tags.

&#x20;

You can also create dataset versions using a subset of images by applying the Filter by Tag preprocessing step. This feature allows you to exclude or include images with specific tags in your training process, providing flexibility in customizing your training datasets.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F8DoMesurbQisdrSN9RY0%2FScreenshot%20(1019).png?alt=media&amp;token=d610ddc7-42c2-4092-b240-5db414041122" alt=""><figcaption><p>On the <a href="https://binaexperts.com/en">BinaExperts</a> dashboard's Assign page, you can filter images based on their assigned tags.</p></figcaption></figure>


# Manage Categories

Lock, remap, or delete classes in your project

On the Classes page, you can view, edit, and manage your annotation classes. Any modifications you make will affect all images within your project, unlike some preprocessing steps, which only affect a specific version. Therefore, it’s important to be certain before making changes, as these actions will apply universally to all images.

## Accessing the Classes Page

To access the Classes page, simply click on Classes in the sidebar.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2Fc56uKLwtWUx4VHnUKEBZ%2FMockUp_1.jpg?alt=media&amp;token=7a5f0dc7-9078-412f-8aee-33585cf701ca" alt=""><figcaption><p>To access the Classes page, simply click on Classes in the sidebar.</p></figcaption></figure>

## Remapping Classes

Click the Modify Classes button to access the available class remapping options. From this menu, you can:

&#x20;

·        Rename a class

·        Delete a class (by clicking Delete)

{% hint style="info" %}
**Warning:** These actions are irreversible and can have a significant impact on your project. Ensure you are confident in your decision before proceeding.
{% endhint %}

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F6lVSNxS5IdahwMRzFYmI%2F47.JPG?alt=media&amp;token=df2bf389-de7e-4980-b069-d9bb1a78b040" alt=""><figcaption><p>Click the Modify Classes button to access the available class remapping options.</p></figcaption></figure>


# Export Versions

Export data from BIAN for training.

You can export data from BinaExpert at any time. You can export data using the BinaExpert web interface or our Python package.

To export data, first generate a dataset version in the BinaExpert dashboard. You can do so on the "Versions" page associated with your project.

**When a version of a dataset is created, a complete freeze of categories, images, and all configurations that existed at that moment remains intact, even if you delete all the images or change the configurations. In other words, your version always represents the latest update of your dataset.**

After you have generated a dataset, click "Export" next to your dataset version:

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FNOlT1S9teIyqdSungiFc%2FScreenshot%20(1021).png?alt=media&amp;token=889c42ad-8cb7-4763-8678-c96564567eaa" alt=""><figcaption></figcaption></figure>

You can download your data in a wide variety of formats. You can see a full list of supported export formats in the "Export" tab of our formats directory.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FTTNbO5XLL3KWPfK2t6BU%2F52.JPG?alt=media&amp;token=e6fc4452-1cf8-438c-b55c-c070c281c49a" alt=""><figcaption></figcaption></figure>

### Class Name Sanitization

To prevent issues from arising during training, we sanitize class names both at upload/import and export. At export, we perform the following:

* Class names are converted to ASCII
  * Where possible, characters are anglicized (ex:  `ü` to `u`)
  * Otherwise, they are replaced with a dash (`-`)


# Health Check

Assess and improve the quality of your dataset.

{% hint style="info" %}
Prefer to learn with video? We have a video tutorial that shows [how to use the dataset health check to improve model quality](https://youtu.be/aUFz6P4dtk4).
{% endhint %}

Health Check shows a range of statistics about the dataset associated with a project. You can see the following pieces of information:

* Number of images in your dataset;
* Number of annotations;
* Average image size;
* Median image ratio;
* Number of missing annotations;
* Number of null annotations;
* Image dimensions across your dataset;
* Object count histogram, and;
* A heatmap of annotation locations.

Using health check, you can derive a range of insights about your dataset. For example, if you have no null annotations, you may want to consider adding a few depending on the project on which you are working; if there are images with missing annotations, you can dig deeper to add the requisite annotations.

See more on the difference between null and missing annotations.

### Class Balance

The health check feature also shows class balance across your annotations. Class Balance shows how many of each object there are and easily visualizes class balance/imbalance. Imbalanced data can yield unfavorable results, especially when measuring models with accuracy.

Here is an example of the class balance feature in use:

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FXWfLEEaa3spPTsnm3AXx%2F53.JPG?alt=media&amp;token=9ffbee6d-bac3-46ac-8f94-65e61df83af5" alt=""><figcaption></figcaption></figure>


# Merge Projects and Datasets

Combine projects and datasets that exist within the same organization.

You can combine projects and datasets together to make a single project in which you can train a model.

If you have Project A and Project B and merge them to create Project C, Project C will be composed of the unique images joined from Projects A and B. Projects A and B will also still exist in the Workspace, not be eliminated.

## **How to Merge Projects**

To merge projects:

1. Hover your mouse on the three dots on the right side of one of the datasets you wish to include the merged dataset. Click the highlighted button (three horizontal dots), and select "Merge Datasets."
2. Select the datasets you wish to merge by clicking the checkboxes on the right side of each dataset.
3. Click "Merge Datasets" in the upper-right corner.
4. Name your new dataset and new annotation group click "Merge Datasets."

The merged dataset will contain the images (and any associated annotations) *present at the time of merging*.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F4UYubUdh0yBkK1irf8NK%2FRec%200012.gif?alt=media&amp;token=74d12c32-a413-4361-a605-0fc1878cb260" alt=""><figcaption></figcaption></figure>

In addition to the merged dataset, you retain the original datasets. In the above example, there are three datasets: the two originals and the newly merged dataset.

The best part is, because the merged dataset consists of copies of other photos, you aren't charged for extra images!


# Delete an Image

Delete an image from a BinaExpert project.

To delete an image from a BinaExperts project:

1. Click on the image you want to delete on the Dataset tab associated with your project.
2. Click the three dots in the top left corner of the page.
3. Click delete icon".
4. Click "Confirm" in the confirmation pop up.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FDnSTdX6RFSBqGhwePMsh%2F54.JPG?alt=media&amp;token=6765aba2-4c6b-4fcf-90ef-a2ff38f54bb2" alt=""><figcaption></figcaption></figure>


# Delete a Project

Learn how to delete a project from your account in BINA

{% hint style="danger" %}
Keep in mind that deletions are permanent and irreversible.  Please make sure you are confident deleting the project.
{% endhint %}

1. Click the three dots beside a project listing on the dashboard or the sidebar in your project
2. Click "Delete Project"
3. Follow the prompts given and confirm the deletion.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FtV0XYiZIXNuFxnacj7yg%2FScreenshot%20(1022).png?alt=media&amp;token=5ddc508c-c006-4abe-8e4b-ce11c3dfa229" alt=""><figcaption></figcaption></figure>


# Annotation Tools

Annotate images for use in your computer vision projects.

BinaExpert Annotate provides a fast, robust interface through which you can annotate images.

You can annotate images using bounding boxes and polygons.

### Annotation Methods

You can annotate images by:

* Drawing bounding boxes and polygons manually
* Using AutoLabel, a tool that uses model checkpoints (i.e. a previous version of your model) to recommend annotations
* Using Smart Polygon, a feature that creates polygon annotations with a few clicks.
* Using Label Assist with SAM, which uses the Segment Anything Model to create more precise polygon annotations with a few clicks.

### Bounding Boxes vs. Polygons

With the option between drawing bounding boxes and polygons, you may wonder: what is the difference between these two annotation types?

Bounding boxes -- boxes drawn around an object of interest in an image -- are easier to draw than polygons, thus taking up less annotation time. Polygons, on the other hand, are more precise, and may lead to a slight increase in performance.

For segmentation tasks, you need to annotate images with polygons, as you are training your model to segment specific items from an image with precision.

This section of the BinaExpert documentation shows how to annotate images using each of the above methods.

{% hint style="success" %}
BinaExpert *is working on*&#x20;
{% endhint %}


# Use BinaExperts Annotate

An overview of the Labeling Interface for BinaExpert Annotation Tool, including shortcut keys.

You can access the labeling interface by selecting an image from the Assign or Dataset pages on the BinaExpert dashboard.

On the right-hand side of the labeling interface, you will find the toolbar. The toolbar has many features you can use for annotating images.

In this document, we talk through how to use the following features:

* Drag and select
* Bounding box annotation tool
* Polgyon annotation tool
* Smart polygon
* Label assist
* Zoom tool

### Drag and Select

Represented by a hand icon, this feature allows you to select, edit, and drag individual annotations.

* **Single-click** an existing bounding box to select it. Once selected, you can change a bounding box's size with the circular white handles that appear on its corners and on each side. Or use the class editor to change the box's label.
* **Drag a box** to move it.
* **press scroll wheel to move background**.
* **Click the background** to deselect all boxes.

### **Bounding Box Annotation Tool**

The bounding box annotation tool (represented by a rectangular box icon) allows you to draw new bounding-box annotations. In this mode, you will see crosshairs that will help you determine where to start drawing.

Click and drag across an image to create a new annotation, then use the Class Selector to choose its label.

### Polygon Annotation Tool

The polygon annotation tool allows you to draw new polygonal annotations. In this mode, you will see crosshairs that will help you determine where to start drawing.

Click on the image around objects of interest to create an enclosed polygon annotation, then use the Class Selector to choose its label.

### Smart Polygon

**Smart Polygon** allows you to draw new Smart Polygon annotations.

In this mode, you will see a green dot when you are selecting a new area of interest (new label); a red dot when selecting areas to remove from the area of interest (parts of the object or image that you don't want to label/enclose with the polygon); and options to adjust the polygon by Convex Hull, Smooth, and Complex settings.

Smart Polygon is particularly useful for (Instance and Semantic) Segmentation projects, however, you may see performance boosts in Object Detection models when labeling with Smart Polygons on BINA.

### **Undo, Redo, and Repeat Annotations**

While in Bounding Box (B), Polygon (P), or Smart Polygon (S) mode:

* **Undo** reverts the previous action.
* **Redo** reverses a previously undone action.
* **Repeat Previous** reapplies label(s) on an image in the same location(s) as the last annotated image&#x20;
*


# Train

In the training section, you can view general information about the model, including the number of training and test data

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FhhBEUyTYL9cuueZLDMZw%2F1.png?alt=media&amp;token=a0cf3563-46f5-4520-b4d9-8d9e88b770e9" alt=""><figcaption></figcaption></figure>

The "Train" section of the website consists of three main subsections: "PROJECT SPEC," "Train Model," and "Train Result."

1. **PROJECT SPEC**: In this section, the details and specifications of the project for training machine learning models are outlined. This includes goals, requirements, constraints, and other details related to the training process. This document serves as a general guide for the training team and other team members involved in the training process.
2. **Train Model**: This section describes the process of training machine learning models using the dataset prepared earlier. It includes selecting and configuring training algorithms, conducting training, and the steps involved in evaluating and optimizing the models.
3. **Train Result**: In this section, the results and progress obtained during the training process of machine learning models are reported. This includes evaluation metrics, training results, charts, and any other type of output generated during the model training process.

In the "PROJECT SPEC" section, you can explore information regarding the dataset, details, data augmentation, sample images, and the "dataset healthcheck" option.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FgxuPQZx0IbYZmCIb7uMN%2F2.jpg?alt=media&amp;token=2e98913a-cc55-4ae9-bce0-161a7e9b7188" alt=""><figcaption></figcaption></figure>

Overall, the "Train" section is used for training machine learning datasets and provides details about the process of training models.

In the "TRAIN MODEL" section, you can utilize the framework, model, and other details for training your model.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FVp8WPozYbw5SKSAsxGkz%2F3.jpg?alt=media&amp;token=2a45b8f4-05c2-42d1-afed-d36663dcbd95" alt=""><figcaption></figcaption></figure>

You can use the following filters as needed and depending on your goals:

* Deployable on GPU
* Deployment on cloud
* High accuracy
* Fast results
* Deployable on CPU
* Optimization

Certainly, here's an explanation for each of these items:

1. **Deployable on GPU**: This refers to the capability of a model or application to be deployed and run on Graphics Processing Units (GPUs). GPUs are specialized hardware designed for parallel processing and are often used for accelerating deep learning inference tasks due to their high computational power.
2. **Deployment on Cloud**: This indicates the ability to deploy a model or application on cloud computing platforms such as Amazon Web Services (AWS), Microsoft Azure, or Google Cloud Platform (GCP). Deploying on the cloud offers scalability, flexibility, and accessibility advantages, allowing users to access resources remotely without the need for on-premises infrastructure.
3. **High Accuracy**: High accuracy suggests that the model or system achieves a high level of correctness or precision in its predictions or outcomes. In the context of machine learning models, accuracy is typically measured by comparing the model's predictions to ground truth labels and evaluating metrics such as precision, recall, F1-score, or classification accuracy.
4. **Fast Results**: This implies that the model or system can produce outputs or predictions quickly, with minimal latency or delay. Fast results are crucial in real-time or time-sensitive applications where rapid decision-making is required, such as autonomous driving, real-time object detection, or video processing.
5. **Deployable on CPU**: Similar to "Deployable on GPU," this refers to the ability of a model or application to be deployed and run on Central Processing Units (CPUs). CPUs are general-purpose processors commonly found in most computing devices and are suitable for running a wide range of software applications, including machine learning models that do not require the computational power of GPUs.
6. **Optimization**: Optimization involves the process of improving the performance, efficiency, or resource utilization of a system or model. In the context of machine learning, optimization may include techniques such as model compression, quantization, pruning, or algorithmic improvements to reduce memory footprint, inference latency, or energy consumption while maintaining or improving accuracy.

In the "TRAIN DETAILS" section, you can view the status of the models you have requested for training. As depicted in the image below, the models submitted for training have three statuses:

1. Queue
2. Done
3. Failed

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F6hNJjjbYOUbtrdm5IAx9%2F4.png?alt=media&amp;token=8433fbd5-708d-4d3d-9fd4-45c602080aeb" alt=""><figcaption></figcaption></figure>

As depicted in the image, in box 1, you can observe filters for searching trained models. In box 2, you can see the status of the models. In box 3, you can find metrics of the trained model such as MAP and recall. If the model fails to pass the health check, the progress status or the reason for failure is specified, similar to what you see in box 4.

Additionally, in box 5, you can view details and logs, archive the model, or access the console.

By clicking on the trained model, you can:

* View details including:
  * Epochs
  * Batches
  * Max Size
  * Patience
  * Momentum
  * Learning Rate
* Test the trained model and visualize its tensorboard.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FQH2nB1aDqcAjxuDKq4ei%2F5.jpg?alt=media&amp;token=08e96598-bb73-40af-99b5-edc1c318c956" alt=""><figcaption></figcaption></figure>

In the "Model Train Result" section, you can easily view the model outputs on test and validation datasets.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FmiU1HCsalLAOvJQYbka3%2F6.jpg?alt=media&amp;token=0293c4c9-a624-40e6-9980-aef1c9896f74" alt=""><figcaption></figcaption></figure>


# Framework

PyTorch and TensorFlow are two widely used frameworks in the field of deep learning.

**PyTorch**, a product of Facebook’s AI Research lab (FAIR), has attracted many researchers and developers with features such as high compatibility with Python, ease of use, and providing advanced capabilities for building neural networks.

**TensorFlow**, developed by the Google Brain team, is one of the most popular frameworks in the field of machine learning. This framework, with features such as support for distributed computations, a variety of tools for visualization, and the ability to use different hardware such as GPUs and TPUs, has maintained its place among users.

The **NVIDIA TAO Toolkit** is an open-source software that simplifies and accelerates the creation of customized and enterprise-ready AI models for computer vision applications. [It uses transfer learning, vision transformers, AutoML, and cloud-native technology to deliver high accuracy and performance on any platform](https://developer.nvidia.com/tao-toolkit)[1](https://developer.nvidia.com/tao-toolkit).

The **Triton Inference Server** (formerly known as TensorRT Inference Server or Triton) is a server software that standardizes the deployment and execution of AI models across every workload. [The server supports trained AI models from many frameworks, including TensorFlow, TensorRT, PyTorch, and ONNX](https://www.nvidia.com/en-us/ai-data-science/products/triton-inference-server/)[2](https://www.nvidia.com/en-us/ai-data-science/products/triton-inference-server/).


# Tensorflow

TensorFlow is a powerful and widely-used deep learning framework with various advantages and some limitations. Below, I'll outline the advantages and disadvantages of using TensorFlow, including its components such as MAP (Mean Average Precision) and others:

**Advantages of TensorFlow:**

1. **Flexibility**: TensorFlow offers flexibility in building and customizing deep learning models. It provides a high-level API (such as Keras) for quick prototyping and low-level APIs for fine-grained control over model architecture and training process.
2. **Scalability**: TensorFlow is designed for scalability, enabling training and deployment of models on different hardware platforms, including CPUs, GPUs, and TPUs. It supports distributed training across multiple devices and servers, allowing for efficient use of computing resources.
3. **Rich Ecosystem**: TensorFlow has a rich ecosystem with a wide range of tools and libraries for various tasks in deep learning, including computer vision, natural language processing, reinforcement learning, and more. This includes pre-trained models, data preprocessing utilities, visualization tools, and deployment options.
4. **Performance**: TensorFlow is optimized for performance, with efficient implementations of core operations and support for hardware acceleration. It leverages CUDA and cuDNN for GPU acceleration and XLA for optimizing computations.
5. **Community Support**: TensorFlow has a large and active community of developers and researchers who contribute to its development, share knowledge and best practices, and provide support through forums, documentation, and tutorials.

**Disadvantages of TensorFlow:**

1. **Complexity**: TensorFlow can be complex and challenging to learn, especially for beginners. Its extensive documentation and steep learning curve may require additional time and effort to become proficient in using the framework effectively.
2. **Verbose Syntax**: TensorFlow's low-level API can lead to verbose and boilerplate code, especially for defining complex neural network architectures and training loops. This can make code harder to read and maintain.
3. **Debugging and Visualization**: Debugging TensorFlow code and visualizing model behavior can be challenging due to its static computation graph nature. It may require additional tools and techniques for effective debugging and visualization.
4. **Performance Tuning**: While TensorFlow offers performance optimizations, achieving optimal performance may require expertise in system configuration, model optimization, and hardware selection. Tuning hyperparameters and optimizing model architecture can also be time-consuming.
5. **Competition and Alternatives**: TensorFlow faces competition from other deep learning frameworks such as PyTorch, which may offer different trade-offs in terms of ease of use, flexibility, and performance. Choosing the right framework depends on the specific requirements and constraints of the project.

**Components of TensorFlow:**

1. **MAP (Mean Average Precision)**: MAP is a commonly used metric for evaluating object detection models. It measures the average precision across different classes and averages them to obtain a single performance score.
2. **TensorFlow Serving**: TensorFlow Serving is a flexible, high-performance serving system for deploying machine learning models in production environments. It allows for scalable and efficient serving of TensorFlow models over gRPC or RESTful APIs.
3. **TensorBoard**: TensorBoard is a visualization tool for TensorFlow that allows users to visualize and inspect various aspects of their deep learning models, including training and evaluation metrics, model graphs, and embeddings.
4. **TensorFlow Lite**: TensorFlow Lite is a lightweight version of TensorFlow designed for mobile and embedded devices. It enables inference of TensorFlow models on edge devices with limited computational resources, such as smartphones, IoT devices, and microcontrollers.
5. **TensorFlow Extended (TFX)**: TensorFlow Extended is an end-to-end platform for deploying production-ready machine learning pipelines. It provides tools and libraries for data validation, preprocessing, training, serving, and monitoring of machine learning models at scale.

Overall, TensorFlow offers a powerful and versatile platform for building, training, and deploying deep learning models, but it also comes with its own set of complexities and challenges that users need to be aware of and address accordingly.

TensorFlow is a popular deep learning framework developed by Google. Follow these steps to deploy your TensorFlow-based models:

1. **Model Optimization**: Before deployment, optimize your TensorFlow models for inference by quantizing, pruning, or converting them to TensorFlow Lite format for efficient execution on production devices.
2. **TensorFlow Serving**: Utilize TensorFlow Serving, a flexible, high-performance serving system for machine learning models, to deploy your TensorFlow models in a scalable and production-ready manner. Configure the server to handle requests efficiently and monitor its performance.


# PyTorch

Here are the advantages and disadvantages of using the PyTorch deep learning framework, including its components such as MAP (Mean Average Precision) and others:

**Advantages of PyTorch:**

1. **Ease of Use**: PyTorch is known for its simplicity and ease of use, especially for researchers and beginners in deep learning. Its dynamic computation graph allows for intuitive model building and debugging, with Pythonic syntax and an imperative programming style.
2. **Flexible and Expressive**: PyTorch offers flexibility and expressiveness in model design and experimentation. It provides a high-level API (such as torch.nn) for building complex neural network architectures and a low-level API (such as torch.autograd) for fine-grained control over gradients and computations.
3. **Dynamic Computation Graph**: PyTorch's dynamic computation graph enables dynamic graph construction during runtime, allowing for more flexibility in model architectures and efficient use of memory. This makes it easier to debug and modify models on-the-fly.
4. **Strong Community Support**: PyTorch has a strong and growing community of developers, researchers, and practitioners who contribute to its development, share knowledge, and provide support through forums, documentation, and tutorials. The community-driven development model fosters innovation and collaboration.
5. **Integration with Python Ecosystem**: PyTorch seamlessly integrates with the Python ecosystem, making it easy to leverage existing libraries and tools for data processing, visualization, and deployment. It also supports interoperability with NumPy arrays, allowing for easy data manipulation.

**Disadvantages of PyTorch:**

1. **Deployment Complexity**: Deploying PyTorch models in production environments can be more complex compared to other frameworks like TensorFlow. While PyTorch offers tools like TorchScript and TorchServe for model deployment, setting up production pipelines may require additional effort and expertise.
2. **Performance Optimization**: Achieving optimal performance with PyTorch models may require manual optimization and tuning of hyperparameters, model architecture, and hardware configurations. This can be time-consuming and challenging, especially for large-scale applications.
3. **Limited Industry Adoption**: Despite its growing popularity, PyTorch has seen relatively limited adoption in some industries and domains compared to other frameworks like TensorFlow. This may result in fewer resources, libraries, and community support tailored to specific use cases.
4. **Static Graph Support**: While PyTorch primarily uses dynamic computation graphs, it also supports static computation graphs through the TorchScript module. However, static graph support may not be as mature or efficient as in other frameworks for some applications.
5. **Learning Curve for Traditional ML Practitioners**: Traditional machine learning practitioners accustomed to static computation graphs may find PyTorch's dynamic approach unfamiliar, leading to a learning curve when transitioning to the framework.

**Components of PyTorch:**

1. **MAP (Mean Average Precision)**: MAP is a commonly used metric for evaluating object detection models. It measures the average precision across different classes and averages them to obtain a single performance score.
2. **TorchVision**: TorchVision is a computer vision library built on top of PyTorch, providing tools and utilities for image processing, dataset loading, and model evaluation. It includes pre-trained models, data augmentation techniques, and evaluation metrics for benchmarking.
3. **TorchText**: TorchText is a natural language processing library for PyTorch, offering data processing utilities, dataset loaders, and text preprocessing pipelines. It facilitates the development of deep learning models for tasks such as text classification, language modeling, and sequence generation.
4. **TorchAudio**: TorchAudio is an audio processing library for PyTorch, offering tools for loading and preprocessing audio data, as well as building deep learning models for speech recognition, sound classification, and audio generation.
5. **TorchServe**: TorchServe is a model serving framework for PyTorch, designed for deploying and managing PyTorch models in production environments. It provides features such as model versioning, multi-model serving, and monitoring capabilities for operationalizing deep learning models at scale.

Overall, PyTorch offers a powerful and flexible platform for deep learning research and development, with strengths in ease of use, flexibility, and integration with the Python ecosystem. While it may have some limitations and challenges, PyTorch continues to evolve and gain momentum in the deep learning community.


# NVIDIA TAO

**NVIDIA TAO (Transfer Learning Toolkit)**

NVIDIA TAO, part of the Transfer Learning Toolkit (TLT), provides tools and workflows to fine-tune pre-trained deep learning models on custom data. Follow these steps to deploy models trained with TAO:

1. **Model Training**: Train your deep learning models using TAO on NVIDIA GPUs, leveraging pre-trained models and transfer learning techniques for tasks such as object detection, segmentation, or classification.
2. **Inference Optimization**: Optimize your trained models for deployment on NVIDIA hardware using TensorRT, NVIDIA's high-performance deep learning inference library. Convert your models to TensorRT format and utilize optimizations such as INT8 quantization and layer fusion for accelerated inference.


# TFLite

**TensorFlow Lite (TFLite)**

TensorFlow Lite is a lightweight solution for deploying machine learning models on mobile and embedded devices. Follow these steps to deploy TensorFlow Lite models:

1. **Model Conversion**: Convert your TensorFlow models to TensorFlow Lite format using tools provided by TensorFlow. Ensure compatibility with your target platform and optimize the model for inference speed and memory footprint.
2. **Integration with Mobile Apps**: Integrate the TensorFlow Lite model into your mobile or embedded application. Utilize TensorFlow Lite interpreter APIs to perform inference on-device, providing real-time predictions without relying on network connectivity.


# Models


# YOLO

YOLO, which stands for "You Only Look Once," is a popular real-time object detection algorithm that identifies specific objects in images or videos. Unlike traditional object detection algorithms that rely on multiple stages or regions of interest, YOLO applies a single neural network to the entire image in a single pass. This enables YOLO to achieve real-time inference speeds, making it suitable for applications such as surveillance, autonomous vehicles, and video analysis.

The key features of YOLO include:

1. **Single Pass Detection**: YOLO divides the input image into a grid and predicts bounding boxes and class probabilities directly from the grid cells. This allows YOLO to detect multiple objects in a single pass through the neural network, resulting in fast inference speeds.
2. **Unified Framework**: YOLO is a unified framework that performs both object localization and classification simultaneously. Instead of separating these tasks into different stages, YOLO predicts bounding boxes and class probabilities directly from the input image, leading to efficient and accurate object detection.
3. **Anchor Boxes**: YOLO uses anchor boxes to improve the accuracy of object localization. Anchor boxes are predefined shapes that represent different aspect ratios and scales of objects. By predicting offsets relative to these anchor boxes, YOLO can accurately localize objects of various sizes and shapes.
4. **Feature Pyramid**: YOLO utilizes a feature pyramid network to capture multi-scale features from the input image. This enables YOLO to detect objects at different scales and resolutions, improving its performance on objects of various sizes.
5. **Versatility**: YOLO is a versatile algorithm that can be applied to various tasks, including general object detection, pedestrian detection, vehicle detection, and more. Its real-time capabilities make it suitable for a wide range of applications in computer vision.

Overall, YOLO is a powerful and efficient object detection algorithm that offers real-time performance and high accuracy, making it widely used in both research and industry for a variety of computer vision tasks.


# CenterNet

CenterNet is an object detection architecture that focuses on identifying object centers and simultaneously estimating their bounding boxes and object categories. Unlike traditional object detection methods that use anchor-based or anchor-free approaches, CenterNet directly predicts object centers and regresses their corresponding bounding boxes.

Key components of CenterNet include:

1. **Object Center Estimation**: CenterNet predicts the center point of each object in the image. This is achieved by regressing the coordinates of the object's center directly from the network's output.
2. **Bounding Box Regression**: Once the object centers are detected, CenterNet regresses the bounding boxes around these centers. It predicts the width, height, and orientation (if applicable) of each bounding box relative to the detected centers.
3. **Object Category Classification**: In addition to predicting object centers and bounding boxes, CenterNet also performs object category classification. It assigns a probability score to each detected object, indicating the likelihood of it belonging to a particular category.
4. **Backbone Network**: CenterNet typically uses a convolutional neural network (CNN) as its backbone for feature extraction. Common choices for the backbone network include ResNet, Hourglass, or MobileNet.
5. **Loss Function**: CenterNet utilizes a combination of regression and classification loss functions to train the network. The regression loss penalizes the discrepancies between predicted and ground truth bounding boxes, while the classification loss penalizes misclassifications of object categories.

CenterNet offers several advantages, including simplicity, efficiency, and strong performance in object detection tasks. By directly predicting object centers, it avoids the need for anchor generation or post-processing steps such as non-maximum suppression (NMS), leading to faster inference speeds and improved accuracy. CenterNet has been successfully applied to various applications, including pedestrian detection, vehicle detection, and general object detection in both images and videos.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FzSe1OMUhE67k9F1BnBKR%2FScreenshot%20(1009).png?alt=media&amp;token=3508fbbc-e659-4314-b730-a73882d831f8" alt=""><figcaption></figcaption></figure>

1. **Hourglass Backbone**: The Hourglass network is a convolutional neural network architecture that is designed to capture multi-scale features efficiently. It consists of repeated encoding and decoding stages, where the network progressively reduces spatial resolution and then upsamples it back to the original size. This enables the network to capture fine-grained details while maintaining spatial information.

By combining CenterNet with an Hourglass backbone, the TensorFlow CenterNet with Hourglass model can effectively capture multi-scale features and accurately localize objects in images. The Hourglass backbone enhances the capability of the network to capture intricate patterns and details, leading to improved performance in object detection tasks.

This model is particularly suitable for applications where high accuracy is required, such as fine-grained object recognition, medical image analysis, and satellite imagery analysis. The combination of CenterNet with an Hourglass backbone offers a good balance between accuracy and efficiency, making it suitable for a wide range of computer vision tasks.

2. **ResNet101 Backbone**: ResNet101 is a deep convolutional neural network architecture that belongs to the ResNet family. It consists of 101 layers and is known for its effectiveness in training very deep neural networks. ResNet101 incorporates residual connections, or skip connections, which enable the network to learn residual mappings, making it easier to train deeper networks without vanishing gradients or degradation in performance.

By using ResNet101 as the backbone network for feature extraction in the TensorFlow CenterNet model, the model can leverage the rich and expressive features learned by ResNet101 to improve the accuracy of object detection. ResNet101 is capable of capturing intricate patterns and details in the input images, which can be beneficial for detecting objects with varying scales, orientations, and appearances.

The combination of CenterNet with a ResNet101 backbone is particularly suitable for demanding object detection tasks where high accuracy is required. It provides a good balance between accuracy and computational efficiency, making it suitable for deployment in real-world applications such as autonomous driving, surveillance, and robotics.


# EfficientNet

EfficientNet is a family of convolutional neural network architectures that have been designed to achieve state-of-the-art performance with significantly fewer parameters and computations compared to previous models. The EfficientNet models are developed based on a compound scaling method that uniformly scales the network's depth, width, and resolution to find an optimal balance between model size and accuracy.

Key features of EfficientNet include:

1. **Compound Scaling**: EfficientNet uses a compound scaling method to scale up the network's depth, width, and resolution simultaneously. This allows the model to achieve better performance by efficiently utilizing computational resources.
2. **Efficient Building Blocks**: EfficientNet employs efficient building blocks such as depthwise separable convolutions, inverted residual blocks, and squeeze-and-excitation blocks to reduce computational complexity while maintaining high accuracy.
3. **Model Size vs. Performance Trade-off**: EfficientNet provides a spectrum of models ranging from smaller and more efficient versions (e.g., EfficientNet-B0) to larger and more powerful versions (e.g., EfficientNet-B7). Users can choose the appropriate model size based on their specific requirements for accuracy and computational resources.
4. **Transfer Learning**: EfficientNet models are pre-trained on large-scale datasets such as ImageNet, which allows for effective transfer learning to downstream tasks with limited amounts of labeled data.
5. **Application Flexibility**: EfficientNet can be applied to a wide range of computer vision tasks, including image classification, object detection, segmentation, and more. Its versatility and efficiency make it suitable for both research and practical applications.

Overall, EfficientNet has become a popular choice for various computer vision tasks due to its impressive performance, efficiency, and scalability. It has achieved state-of-the-art results on benchmark datasets while requiring fewer parameters and computations compared to other models.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FZoCy9fN9CGTAGP1qde7U%2FScreenshot%20(1008).png?alt=media&amp;token=d78b3fee-ed29-4e3f-a237-c2846b9e5836" alt=""><figcaption></figcaption></figure>

1. **EfficientNet-B0**: This is the smallest and most efficient variant of the EfficientNet family. It has fewer parameters and computations compared to larger models but still delivers competitive performance. EfficientNet-B0 is suitable for scenarios where computational resources are limited.
2. **EfficientNet-B1 to B6**: These models progressively increase in size and complexity, with more parameters and computations compared to EfficientNet-B0. As the model index increases from B1 to B6, the network's depth, width, and resolution are scaled up according to the compound scaling method, resulting in improved performance.
3. **EfficientNet-B7**: This is the largest and most powerful variant of the EfficientNet family. It has the highest number of parameters and computations, making it suitable for applications where high accuracy is required, and computational resources are less constrained. EfficientNet-B7 achieves state-of-the-art performance on various benchmark datasets.

EfficientNet models are pre-trained on large-scale datasets such as ImageNet and can be fine-tuned or used as feature extractors for downstream tasks such as image classification, object detection, semantic segmentation, and more. They offer a good balance between model size, computational efficiency, and accuracy, making them widely adopted in both research and industry for a variety of computer vision applications.

Users can choose the appropriate EfficientNet model variant based on their specific requirements for accuracy, computational resources, and application domain.


# Faster R-CNN

Faster R-CNN is a widely used object detection algorithm that builds upon the region proposal network (RPN) and the convolutional neural network (CNN) framework. It is known for its accuracy and efficiency in detecting objects within images.

Here's a breakdown of Faster R-CNN:

1. **Region Proposal Network (RPN)**: Faster R-CNN introduces the RPN, which is a fully convolutional network that proposes candidate object bounding boxes (regions of interest or RoIs) within an image. The RPN operates on feature maps extracted from the input image using a backbone CNN (e.g., ResNet), and it predicts bounding box coordinates and objectness scores for potential object locations.
2. **Feature Extraction Backbone**: Faster R-CNN typically uses a pre-trained CNN (e.g., ResNet, VGG) as its backbone for feature extraction. The backbone CNN processes the input image and extracts high-level feature representations that are used by both the RPN and the subsequent object detection network.
3. **Region of Interest Pooling**: Once candidate object bounding boxes are proposed by the RPN, Faster R-CNN performs region of interest (RoI) pooling or RoI align operations to extract fixed-size feature maps for each RoI from the backbone feature maps. These RoI features are then fed into a fully connected layer for subsequent classification and bounding box regression.
4. **Classification and Regression Heads**: Faster R-CNN utilizes separate heads for object classification and bounding box regression. The classification head predicts the probability of each RoI belonging to a particular object class, while the regression head refines the bounding box coordinates of each RoI.
5. **Loss Function**: Faster R-CNN is trained using a multi-task loss function, which includes classification loss (e.g., cross-entropy loss) and regression loss (e.g., smooth L1 loss). The model is trained end-to-end using backpropagation to jointly optimize both tasks.

Faster R-CNN achieves state-of-the-art performance in object detection tasks, balancing accuracy and speed effectively. It has been widely adopted in various applications such as autonomous driving, surveillance, and image analysis, where precise localization and classification of objects are essential.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FHO31PhEa9doGvao76TIN%2FScreenshot%20(1007).png?alt=media&amp;token=84dc96b9-9466-4ff6-9269-57c51f3750c5" alt=""><figcaption></figcaption></figure>

1. **Inception Backbone**: Inception is a family of convolutional neural network architectures known for their efficiency and effectiveness in image recognition tasks. The Inception backbone used in TensorFlow Faster R-CNN typically refers to variants of the Inception architecture (e.g., Inception-v2, Inception-v3) that are pretrained on large-scale datasets such as ImageNet.

By combining the Faster R-CNN framework with an Inception backbone, the TensorFlow Faster R-CNN with Inception model achieves a balance between accuracy and efficiency. It leverages the strengths of the Inception architecture for feature extraction, enabling accurate object detection while maintaining computational efficiency. This makes it suitable for various applications such as autonomous driving, surveillance, and image analysis.

2. **resnet101 backbone**: By combining the Faster R-CNN framework with a ResNet101 backbone, the TensorFlow Faster R-CNN with ResNet101 model achieves state-of-the-art performance in object detection tasks. It leverages the rich features learned by ResNet101 to accurately detect and classify objects within images, making it suitable for various applications such as autonomous driving, surveillance, and image analysis.


# Single Shot Multibox Detector (SSD)

Single Shot Multibox Detector (SSD) is a widely used object detection algorithm in computer vision. It is known for its simplicity, efficiency, and effectiveness in real-time object detection tasks.

SSD operates by predicting object bounding boxes and class probabilities directly from feature maps at multiple scales within a single pass through the network. This is achieved by using a set of convolutional filters to detect objects at different levels of granularity.

Key features of SSD include:

1. **Single Pass Prediction**: SSD performs object detection in a single pass through the network, which makes it highly efficient and suitable for real-time applications.
2. **Multi-scale Feature Fusion**: SSD utilizes feature maps from multiple layers of the neural network to detect objects at different scales. This allows it to handle objects of various sizes and aspect ratios effectively.
3. **Anchor Boxes**: SSD predicts bounding boxes using anchor boxes of different sizes and aspect ratios at each feature map location. This enables accurate localization of objects with varying shapes and sizes.
4. **Unified Framework**: SSD simultaneously performs object localization and classification tasks, eliminating the need for separate detection and classification stages.

Overall, SSD is a versatile and effective object detection algorithm that has been widely adopted in various applications, including autonomous driving, surveillance, and robotics. Its simplicity and efficiency make it a popular choice for real-time object detection tasks.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FgAWpWwbkqsV5B5Mv64Ei%2FScreenshot%20(999).png?alt=media&amp;token=0e53bc16-724e-4302-a875-3f20e8e41389" alt=""><figcaption></figcaption></figure>

1. **MobileNet**: MobileNet is a lightweight convolutional neural network architecture designed for mobile and embedded vision applications. It uses depthwise separable convolutions to reduce computational complexity while maintaining high accuracy. MobileNet is known for its efficiency and has been widely adopted in various computer vision tasks, including object detection.

By combining SSD with the MobileNet backbone, the TensorFlow SSD model with a MobileNet backbone achieves a ***balance between speed and accuracy***, making it suitable for real-time object detection on resource-constrained devices such as mobile phones, drones, or embedded systems.

This model is particularly useful in scenarios where real-time processing is required, such as surveillance, autonomous vehicles, and augmented reality applications. Additionally, its efficiency makes it well-suited for deployment on edge devices with limited computational resources.

2. **ResNet152**: ResNet152 is a deep convolutional neural network architecture that belongs to the ResNet family. It is characterized by its depth, featuring 152 layers, and its use of residual connections to enable the training of very deep neural networks. ResNet152 has shown impressive performance in various computer vision tasks, including image classification, object detection, and semantic segmentation. By incorporating ResNet152 as the backbone network for feature extraction in the TensorFlow SSD model, the model can leverage the rich and expressive features learned by ResNet152 to improve the accuracy of object detection. ResNet152 is capable of capturing intricate patterns and details in the input images, which can be beneficial for detecting objects with varying scales, orientations, and appearances.

The combination of SSD with a ResNet152 backbone is particularly suitable for demanding object detection tasks where high accuracy is required, such as fine-grained object recognition, medical image analysis, and satellite imagery analysis. However, it is important to note that using a deeper backbone network like ResNet152 may increase the computational complexity and memory requirements of the model, potentially impacting inference speed and deployment feasibility.

3. **MobileNet**: MobileNet is a lightweight convolutional neural network architecture designed for mobile and embedded vision applications. It uses depthwise separable convolutions to reduce computational complexity while maintaining high accuracy. MobileNet is known for its efficiency and has been widely adopted in various computer vision tasks, including object detection.

**Feature Pyramid Network (FPN)**: FPN is a feature extraction architecture designed to capture multi-scale features from input images. It achieves this by building a feature pyramid with different levels of resolution and semantic information. FPN enhances the capability of the backbone network to detect objects at different scales and improves the overall performance of the object detection model.

By combining SSD with a MobileNet backbone and FPN, the TensorFlow SSD model with MobileNetFPN achieves a balance between speed, efficiency, and accuracy. It leverages the lightweight and efficient nature of MobileNet for feature extraction while benefiting from the multi-scale feature representation provided by FPN.

This model is particularly suitable for real-time object detection tasks on resource-constrained devices such as mobile phones, drones, or embedded systems. It offers a good trade-off between model size, inference speed, and detection accuracy, making it suitable for a wide range of applications in computer vision.


# DETR

**Introduction**

DETR (Detection Transformer) is an innovative object detection model developed by the FAIR (Facebook AI Research) team. This model utilizes transformer architecture, which is specifically designed for sequence processing. In this post, we will explore the features and applications of the DETR model.

**Features of the DETR Model**

1. **Network Architecture**: DETR combines transformers with convolutional networks. In this model, images are first processed by a convolutional network to extract basic features. These features are then fed into the transformer, which is responsible for object detection and localization.
2. **Simplicity and Integration**: Unlike traditional methods that used multiple complex stages for object detection, DETR offers an integrated and simple approach that reduces the need for complex preprocessing and postprocessing steps.
3. **High Accuracy**: Using transformers in the DETR model enables it to capture long-range dependencies between pixels in an image, thus improving object detection accuracy.
4. **End-to-End Learning Support**: A key feature of DETR is its end-to-end learning capability, allowing the model to directly map input images to final outputs without the need for complex and manual tuning.
5. **Support from Detectron2**: The Detectron2 library provides the necessary tools to use and train the DETR model, enabling users to customize and optimize the model for their specific datasets.

**Applications of the DETR Model**

1. **Object Detection in Images and Videos**: DETR can be effectively used for object detection in images and videos. This application is highly useful in fields like surveillance, security, autonomous vehicles, and augmented reality.
2. **Medical Image Analysis**: In the medical field, DETR can be used to detect anomalies and diseases in medical images such as radiology and MRI scans, assisting doctors in making faster and more accurate diagnoses.
3. **Identification and Classification of Living Organisms**: In biology and environmental science, the DETR model can be used to identify and classify different species of animals and plants in natural images, aiding researchers in studying biodiversity and environmental conservation.
4. **E-commerce**: In online stores, DETR can be used to detect and classify products in images, enhancing user experience and enabling faster and more accurate product searches.

**Conclusion**

As an innovative model in object detection, DETR has found widespread applications across various domains due to its high accuracy and efficiency. With the powerful Detectron2 library, users can easily leverage this model and customize it for their specific needs.

We hope this post has provided you with a good understanding of the features and applications of the DETR model. If you have any questions or need further information, please feel free to share them in the comments section.


# DETECTRON2 FASTER RCNN

In this post, we will introduce the computer vision model [**Detectron2 Faster R-CNN**](https://blog.binaexperts.com/models-ai-in-binaexperts-detectron2-faster-rcnn/). This model is one of the most advanced and widely used object detection models, developed by Facebook AI Research (FAIR). We will provide a detailed overview of its features, applications, and usage.

**What is Detectron2?**

**Detectron2** is an open-source platform for object detection, image segmentation, and keypoint detection. Developed by the Facebook AI Research team, it is an improved version of the previous Detectron platform. Detectron2 is built on the PyTorch deep learning framework and is highly regarded for its performance and accuracy among researchers and developers.

**Key Features of Detectron2**

1. **Support for Advanced Models**: Detectron2 supports multiple models, such as Faster R-CNN, Mask R-CNN, RetinaNet, and more.
2. **Ease of Use**: Its modular design and well-structured architecture make it easy to use and configure.
3. **Extensibility**: Developers can easily implement their models and algorithms within this platform.
4. **High Efficiency**: Optimized to leverage GPU computing power, Detectron2 accelerates model training and inference.

**What is Faster R-CNN?**

**Faster R-CNN** stands for "Region-based Convolutional Neural Networks" and is one of the most advanced architectures for object detection. Specifically designed to improve the speed and accuracy of object detection, this model comprises two main components:

1. **Region Proposal Network (RPN)**:
   * Responsible for generating proposed regions that may contain objects.
   * Uses a convolutional neural network to extract these regions from the input image and suggests potential object locations.
2. **Detection Network**:
   * Utilizes a convolutional neural network to extract features and accurately detect objects within the proposed regions.
   * Each proposed region is examined in detail to identify the type of object present and its precise location in the image.

**Key Features of Detectron2 Faster R-CNN**

1. **High Accuracy**: The Faster R-CNN model offers very high accuracy in object detection, even in complex and crowded scenes.
2. **Flexibility**: The model is easily adjustable and adaptable to various data types and applications. Developers can customize parameters and settings to meet specific needs.
3. **Optimized Speed**: While traditional R-CNN models were slow, Faster R-CNN significantly improves detection speed using RPN.
4. **Open-Source**: Detectron2 is open-source, allowing researchers and developers to use and enhance it. This feature has led to its rapid advancement and improvement.

**Applications of Detectron2 Faster R-CNN**

1. **Autonomous Vehicles**:
   * Detecting pedestrians, vehicles, traffic signs, and road obstacles for autonomous driving systems.
2. **Medical Imaging**:
   * Identifying medical anomalies in radiology, MRI, and CT scan images. This model can assist doctors in faster and more accurate diagnoses.
3. **Surveillance and Security**:
   * Detecting individuals and objects in CCTV footage for surveillance and security purposes. Useful in public spaces, airports, and sensitive buildings.
4. **E-commerce**:
   * Automatically tagging products in video and photography for improved user experience and quicker, more accurate searches on e-commerce platforms.
5. **Smart Agriculture**:
   * Detecting and counting plants, identifying pests and diseases in crops to improve farm management and productivity.
6. **Robotics**:
   * Used in autonomous robots to recognize and interact with objects in various environments.

**Relevant Images**

To choose suitable images for this post, consider using visuals that illustrate different stages of working with the Faster R-CNN model. These images can include:

* **Input and Output Images**: Showcasing the images that the model takes as input and the resulting output, such as images with detected objects and proposed regions.
* **Data Flow Diagrams**: Diagrams illustrating the architecture of the Faster R-CNN model and how data is processed.
* **Screenshots of Detectron2 Working Environment**: Images from the working environment and tools used in the Detectron2 platform.
* **Practical Application Examples**: Visuals demonstrating practical applications of the model in various industries, such as autonomous vehicles, medical imaging, and surveillance.

**Conclusion**

The **Detectron2 Faster R-CNN** model is one of the most powerful tools available for object detection, offering high accuracy, flexibility, and optimized speed. This model can be an essential tool in developing intelligent systems and analyzing visual data across various industries.

We hope this post has been helpful to you. Share your thoughts and [questions in the comments section](https://blog.binaexperts.com/). If you are interested in learning more about object detection models and their applications, don’t miss our other articles and content on the[ **Bina Experts**](https://binaexperts.com/) website.


# RETINANET

**Introduction**

RetinaNet is an advanced object detection model developed by researchers at Facebook AI Research (FAIR). It is notable for using the Focal Loss method to improve object detection accuracy in the face of class imbalance. In this post, we will explore the features and applications of the RetinaNet model.

**Features of the RetinaNet Model**

1. **Network Architecture**: RetinaNet utilizes a deep convolutional neural network that includes a Backbone network for feature extraction and two sub-networks for object classification and localization. This model is trained end-to-end.
2. **Focal Loss**: A key feature of RetinaNet is the use of the Focal Loss function. This loss function is designed to address class imbalance by focusing more on hard-to-detect objects, thus helping the model achieve higher accuracy on rare and challenging data.
3. **High Accuracy**: Due to the use of Focal Loss and an advanced architecture, RetinaNet has achieved very high accuracy in object detection, even in complex and challenging images.
4. **High Efficiency and Speed**: RetinaNet is designed to offer both high accuracy and efficiency, making it suitable for real-time applications.
5. **Support from Detectron2**: The Detectron2 library provides the necessary tools to use and train the RetinaNet model. This library allows users to customize and optimize the model for their specific datasets.

**Applications of the RetinaNet Model**

1. **Object Detection in Images and Videos**: RetinaNet can be effectively used for object detection in images and videos. This application is highly useful in fields like surveillance, security, autonomous vehicles, and augmented reality.
2. **Medical Image Analysis**: In the medical field, RetinaNet can be used to detect anomalies and diseases in medical images such as radiology and MRI scans, assisting doctors in making faster and more accurate diagnoses.
3. **Identification and Classification of Living Organisms**: In biology and environmental science, the RetinaNet model can be used to identify and classify different species of animals and plants in natural images, aiding researchers in studying biodiversity and environmental conservation.
4. **E-commerce**: In online stores, RetinaNet can be used to detect and classify products in images, enhancing user experience and enabling faster and more accurate product searches.

**Conclusion**

As an advanced model in object detection, RetinaNet has found widespread applications across various domains due to its high accuracy and efficiency. With the powerful Detectron2 library, users can easily leverage this model and customize it for their specific needs.

We hope this post has provided you with a good understanding of the features and applications of the RetinaNet model. If you have any questions or need further information, please feel free to share them in the comments section.


# dataset healthcheck

Performing a "dataset healthcheck" is a common practice in cases where machine learning models are trained on specific datasets. This command is used to evaluate and ensure the health of the dataset, checking for any issues or deficiencies in the data. Typically, at this stage, we want to ensure that our data is suitable for training models in terms of quality, balance, and usability.

Operations involved in a "dataset healthcheck" may include:

1. **Data Quality Check**: A thorough examination of the data to ensure the absence of outliers, inappropriate data, duplicates, or any other quality issues.
2. **Class Balance Check**: If models are used for classification tasks, ensuring a proper balance between different classes in the data is important to prevent issues such as overfitting or underfitting.
3. **Training and Testing Data Evaluation**: A detailed assessment of training and testing data to ensure they meet the requirements of the models and training principles.
4. **Systemic Defects Identification**: Identifying any issues or defects in the data collection, preprocessing, or data preparation processes that may systematically affect the data.

By performing such operations, we ensure that our data is ready and suitable for use in the model training process and that any potential issues that may negatively impact the performance of the models are fully identified and addressed.

**annotation heatmap**

Generating a heatmap of overlapping annotations in a dataset health check involves visualizing the regions where annotations overlap across multiple annotations or annotators. This visualization can help identify areas of agreement or disagreement between annotations and assess the quality and consistency of the annotations.

Here's a general approach to generate a heatmap of overlapping annotations:

1. **Data Preparation**: Gather the annotations or labels for the dataset, along with any additional metadata such as image filenames or annotation IDs.
2. **Compute Overlapping Regions**: For each image or sample in the dataset, compute the overlapping regions between annotations. This typically involves comparing the bounding boxes, polygons, or segmentation masks of annotations and identifying regions where they intersect or overlap.
3. **Aggregate Overlaps**: Aggregate the overlapping regions across multiple annotations or annotators. Depending on the specific use case, you may want to compute statistics such as the frequency of overlap or the proportion of annotations that agree on a particular region.
4. **Generate Heatmap**: Use a heatmap visualization technique to represent the aggregated overlaps. This could involve creating a grid or image where each pixel represents a region of the dataset, and the intensity of the pixel color indicates the degree of overlap or agreement between annotations in that region.
5. **Visualization**: Visualize the heatmap to identify patterns of overlap or agreement across the dataset. You can use color gradients to represent the intensity of overlap, with brighter colors indicating higher levels of agreement or overlap.
6. **Interpretation and Analysis**: Interpret the heatmap to assess the quality and consistency of the annotations. Look for areas of high agreement or disagreement and investigate further as needed. This analysis can help identify potential areas for improvement in the annotation process or highlight challenging regions in the dataset.

Tools and libraries such as OpenCV, Matplotlib, or Seaborn in Python can be helpful for implementing this workflow and generating the heatmap visualization. Additionally, integrating interactive visualization techniques can enhance the exploration and analysis of overlapping annotations in the dataset.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FC31oIxjOpPjHmcRZ00mN%2F07.gif?alt=media&amp;token=26b93098-33a3-4051-975c-ce44728139a1" alt=""><figcaption></figcaption></figure>


# Distribution of annotations based on their size relative

To create a chart showing the distribution of annotations based on their size relative to their image, along with additional information about the average size of images containing annotations of each size category compared to the average dataset image size, you can follow these steps:

1. **Calculate Annotation Size**: Determine the size of each annotation relative to its corresponding image. This could be measured in terms of area, bounding box dimensions, or any other relevant metric.
2. **Group Annotations by Size Category**: Group the annotations into size categories based on their relative size compared to the image. For example, you could categorize annotations as small, medium, or large based on predefined thresholds.
3. **Calculate Average Image Size**: Calculate the average size of images containing annotations for each size category. This can be done by averaging the dimensions (e.g., width and height) of images with annotations in each size category.
4. **Visualize Distribution**: Create a chart (e.g., a bar chart) to visualize the distribution of annotations across size categories. Each bar represents a size category, and the height of the bar corresponds to the percentage of annotations in that category relative to the total number of annotations.
5. **Add Additional Information**: Overlay additional information on the chart to provide context. For example, you can add blue bars to represent the average size of images containing annotations in each size category compared to the average dataset image size. Additionally, you can include cyan bars to show the percentage of images containing annotations in each size category.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F7owwH2nzL3fITGOAWQwd%2FRec%200006%20(2).gif?alt=media&amp;token=920cd4bf-baca-4a3f-835c-32a486c8034b" alt=""><figcaption></figcaption></figure>

Here's an example of how you might implement this visualization using Python and Matplotlib:

```python
import matplotlib.pyplot as plt
import numpy as np

# Sample data (replace with your actual data)
size_categories = ['Small', 'Medium', 'Large']
annotation_counts = [100, 200, 150]  # Number of annotations in each size category
avg_image_sizes = [0.5, 0.7, 0.9]  # Average image size relative to dataset size
image_percentage = [30, 50, 20]  # Percentage of images containing annotations in each size category

# Create figure and axis objects
fig, ax = plt.subplots()

# Plot annotation distribution
ax.bar(size_categories, annotation_counts, color='skyblue', label='Annotation Count')

# Plot average image size
ax.bar(size_categories, avg_image_sizes, color='blue', alpha=0.5, label='Avg. Image Size')

# Plot image percentage
ax.bar(size_categories, image_percentage, color='cyan', alpha=0.5, label='Image Percentage')

# Add labels and legend
ax.set_xlabel('Size Category')
ax.set_ylabel('Count / Size')
ax.set_title('Annotation Size Distribution')
ax.legend()

# Show plot
plt.show()
```

In this example, `size_categories` represent the different size categories, `annotation_counts` represent the number of annotations in each category, `avg_image_sizes` represent the average size of images containing annotations in each category relative to the dataset size, and `image_percentage` represent the percentage of images containing annotations in each category. You should replace these sample values with your actual data.


# Distribution of annotations based on their size relative

To create a simple overview chart of the distribution of annotations based on their size relative to their image, you can use a histogram or a bar chart to visualize the distribution of annotation sizes. Here's how you can do it:

1. **Calculate Annotation Sizes**: Determine the size of each annotation relative to its corresponding image. This could be measured in terms of area, bounding box dimensions, or any other relevant metric.
2. **Plot Histogram or Bar Chart**: Create a histogram or a bar chart to visualize the distribution of annotation sizes. Each bar represents a range of annotation sizes, and the height of the bar corresponds to the number of annotations falling within that range.
3. **Add Labels and Titles**: Label the axes and provide a title for the chart to make it clear what the chart represents.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F4LCVLt9824HJC9jnjQIQ%2FRec%200007.gif?alt=media&amp;token=f18d6704-1a6c-465e-a70e-f51332638e1f" alt=""><figcaption></figcaption></figure>


# TensorBoard

TensorBoard provides the visualization and tooling needed for machine learning experimentation:

* Tracking and visualizing metrics such as loss and accuracy
* Visualizing the model graph (ops and layers)
* Viewing histograms of weights, biases, or other tensors as they change over time
* Projecting embeddings to a lower dimensional space
* Displaying images, text, and audio data
* Profiling TensorFlow programs
* And much more

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F49RsDbLewdz2wZpk9WiF%2Ftensorboard.gif?alt=media&amp;token=c6363370-dd54-4248-8725-f821ff862c16" alt=""><figcaption></figcaption></figure>

you can start tensorboard on this [link](https://www.tensorflow.org/tensorboard/get_started)


# Hyperparameters

### Batches

In neural network training, the term "batches" refers to the number of data samples that are simultaneously fed into the neural network and processed in one step of the training process. The batch size is an important parameter in neural network training and can directly impact the quality and speed of training. Some effects of batch size include:

1. **Accelerated Training**: Using a larger batch size can lead to faster training because the network receives more information in each step of training and performs weight updates based on it.
2. **Optimal Utilization of Computational Resources**: Using a larger batch size can lead to more efficient utilization of computational resources such as GPU processors and memory. Since the network works with more data in each training step, it can make more efficient use of computational resources.
3. **Training Stability**: Using a larger batch size can contribute to training stability. By increasing the diversity of input data seen by the network in each step, the likelihood of overfitting is reduced.

In general, the choice of batch size should be made based on the specific requirements of the problem, available computational resources, and training objectives.

An epoch in neural network training refers to one complete pass through the entire training dataset. During each epoch, the training algorithm iterates over the entire dataset, feeding the data into the neural network in batches, performing forward and backward propagation, and updating the model parameters (weights and biases) based on the calculated gradients.

The number of epochs is an important hyperparameter in training neural networks and determines how many times the training algorithm will iterate over the entire dataset. Increasing the number of epochs allows the model to see the training data multiple times, which can lead to better convergence and improved performance. However, using too many epochs can also increase the risk of overfitting, where the model memorizes the training data instead of learning generalizable patterns.

The choice of the number of epochs depends on various factors, including the complexity of the dataset, the size of the dataset, the architecture of the neural network, and the desired level of model performance. It is common practice to monitor the model's performance on a separate validation dataset during training and stop training when the performance stops improving or starts deteriorating, a technique known as early stopping. This helps prevent overfitting and ensures that the model generalizes well to unseen data.

The GPU type refers to the specific model or architecture of the Graphics Processing Unit (GPU) being used in a computing system. GPUs are specialized processors designed to handle parallel computations, making them well-suited for deep learning tasks such as training and inference of neural networks.

There are various GPU models available from different manufacturers such as NVIDIA, AMD, and Intel. Some common GPU models from NVIDIA include:

1. NVIDIA GeForce RTX series: These GPUs are designed primarily for gaming but also offer excellent performance for deep learning tasks.
2. NVIDIA GeForce GTX series: These GPUs are older than the RTX series but still provide good performance for deep learning workloads.
3. NVIDIA Quadro series: These GPUs are optimized for professional applications such as computer-aided design (CAD) and video editing but can also be used for deep learning.
4. NVIDIA Tesla series: These GPUs are designed specifically for high-performance computing (HPC) and data center applications, including deep learning training and inference.

The choice of GPU type depends on factors such as budget, performance requirements, and availability. For deep learning tasks, NVIDIA GPUs are the most commonly used due to their excellent performance and support for deep learning frameworks such as TensorFlow and PyTorch. However, AMD and Intel also offer GPUs that can be used for deep learning, albeit with varying levels of performance and compatibility with deep learning frameworks.


# Advanced Hyperparameter

The choice between the Adam and SGD (Stochastic Gradient Descent) optimizers depends on various factors such as the nature of the problem, the dataset, and the architecture of the neural network. Here's a comparison between the two optimizers:

1. **Adam (Adaptive Moment Estimation)**:
   * Adam is an adaptive learning rate optimization algorithm that combines the advantages of both AdaGrad and RMSProp.
   * It maintains separate learning rates for each parameter and adapts the learning rates based on the first and second moments of the gradients.
   * Adam is well-suited for a wide range of deep learning tasks and is known for its fast convergence and robustness to noisy gradients.
   * It requires less manual tuning of hyperparameters compared to SGD, making it easier to use for many tasks.
2. **SGD (Stochastic Gradient Descent)**:
   * SGD is a classic optimization algorithm that updates the model parameters based on the gradients of the loss function with respect to the parameters.
   * It uses a fixed learning rate for all parameters and does not adapt the learning rate during training.
   * SGD can be sensitive to the choice of learning rate and may require manual tuning to achieve good performance.
   * It is computationally efficient and memory-efficient, especially for large-scale datasets, and can sometimes achieve better generalization than Adam.

In summary, Adam is often the default choice for deep learning tasks due to its robustness and ease of use. However, SGD can still be effective, especially when fine-tuned carefully, and it may be preferred in some scenarios where computational efficiency or generalization is a priority. Ultimately, the best optimizer depends on the specific requirements and constraints of the task at hand, and it is recommended to experiment with both optimizers to determine which one works best for a particular problem.


# YAML

A hyperparameter file in YAML format is a configuration file that contains the hyperparameters and settings used to train a neural network model. YAML (YAML Ain't Markup Language) is a human-readable data serialization language that is commonly used for configuration files due to its simplicity and readability.

Here's an example of what a hyperparameter file in YAML format might look like:

```yaml
model:
  type: "resnet"
  num_layers: 18
  num_classes: 10

optimizer:
  type: "adam"
  learning_rate: 0.001
  weight_decay: 0.0001

training:
  batch_size: 32
  num_epochs: 100
  early_stopping:
    patience: 5
    min_delta: 0.001

data:
  train_data_path: "/path/to/train_data"
  val_data_path: "/path/to/val_data"
```

In this example:

* Under the `model` section, hyperparameters related to the neural network architecture are specified, such as the type of model (e.g., ResNet), the number of layers, and the number of output classes.
* Under the `optimizer` section, hyperparameters related to the optimizer used for training are specified, such as the type of optimizer (e.g., Adam), the learning rate, and weight decay.
* Under the `training` section, hyperparameters related to the training process are specified, such as the batch size, number of epochs, and early stopping criteria.
* Under the `data` section, paths to the training and validation datasets are specified.

Using a YAML file to store hyperparameters allows for easy modification and experimentation with different settings without having to modify the source code of the training script. Additionally, it provides a clear and organized way to document the hyperparameters used for training a model.


# Image Size

The maximum size for the input images during training depends on several factors including the architecture of the neural network, the available computational resources, and the characteristics of the dataset. There isn't a fixed maximum size that applies universally to all scenarios, but rather it's a decision that needs to be made based on the specific requirements and constraints of your project.

Here are some considerations to help determine the maximum size for train input images:

1. **Neural Network Architecture**: Different architectures may have different constraints on the input image size. Some architectures, like fully convolutional networks, may be more flexible with input sizes, while others, like those based on pre-trained models, may have fixed input size requirements.
2. **Computational Resources**: Larger input images require more memory and processing power, so the maximum size may be limited by the available computational resources, such as GPU memory.
3. **Dataset Characteristics**: The characteristics of the dataset, such as the variability in object sizes and aspect ratios, may influence the choice of input image size. It's important to choose a size that captures sufficient detail for the objects of interest in the dataset.
4. **Training Objectives**: The training objectives and performance requirements may also influence the choice of input image size. For example, if high-resolution details are important for accurate detection or segmentation, a larger input size may be necessary.
5. **Data Augmentation**: Data augmentation techniques such as random cropping and resizing can help mitigate the effects of using smaller input sizes during training. However, it's important to ensure that the augmentation does not introduce unrealistic distortions or artifacts.

In practice, it's common to experiment with different input sizes during training to find the optimal balance between model performance and computational efficiency. Starting with a moderate size and gradually increasing it while monitoring the training progress and performance on a validation set is a good approach to determine the maximum size for train input images.


# Validation input image size

The validation input image size should ideally match the input size used during training to ensure consistency and comparability in the evaluation process. This means that the validation images should be resized or cropped to the same dimensions as the training images before being fed into the model for evaluation.

Maintaining consistency in input image sizes between training and validation is important because:

1. **Model Compatibility**: Neural network models are typically designed to accept input images of a specific size. Using different sizes during training and validation may result in incompatible input dimensions, leading to errors or unexpected behavior.
2. **Evaluation Consistency**: Evaluating the model's performance on validation data that differs in size from the training data may not provide an accurate representation of its true performance. Consistent input sizes ensure that the model is evaluated under the same conditions as during training.
3. **Fair Comparison**: Consistent input sizes enable fair comparisons between different models or configurations. If different models are trained with different input sizes, their performance cannot be directly compared without accounting for this difference.

To ensure consistency, it's recommended to preprocess the validation images to match the input size used during training. This may involve resizing, cropping, or padding the images as necessary. Additionally, it's important to document the preprocessing steps and input sizes used during both training and validation to ensure transparency and reproducibility in the evaluation process.


# Patience

The term "patience" in the context of machine learning typically refers to the number of epochs to wait before terminating training if no improvement in the validation metric is observed. It is used in conjunction with techniques such as early stopping to prevent overfitting and improve the generalization of the model.

The value of "patience" is a hyperparameter that specifies the maximum number of epochs to continue training without improvement in the validation metric. The min and max values provided (0 and 100000, respectively) indicate the range within which the "patience" hyperparameter can be specified.

Here's what it means:

* A "patience" value of 0 means that the training will stop immediately if no improvement is observed after the first epoch.
* A "patience" value of 100000 means that the training will continue for a maximum of 100000 epochs even if no improvement is observed.

In practice, the value of "patience" is typically chosen based on experimentation and validation performance. It should strike a balance between allowing sufficient time for the model to learn meaningful patterns in the data and avoiding overfitting by stopping training when performance on the validation set starts to degrade.

A common approach is to start with a relatively small value for "patience" and gradually increase it if necessary. Values between 5 and 20 are often used as a starting point, but the optimal value may vary depending on the dataset, model architecture, and training objectives.


# Rectangular training

"Rectangular training" refers to a training strategy where input images are resized or cropped to have a fixed aspect ratio before being fed into the neural network for training. In rectangular training, the aspect ratio of the input images is typically different from the aspect ratio of the original images in the dataset.

Here's how rectangular training works:

1. **Resize or Crop**: In rectangular training, input images are resized or cropped to have a fixed aspect ratio, often chosen based on practical considerations or architectural constraints of the neural network model. This may involve padding or cropping the input images to fit the desired aspect ratio.
2. **Normalization**: After resizing or cropping, the input images are typically normalized to ensure consistency in pixel values across different images. This normalization step helps improve the stability and convergence of the training process.
3. **Training**: The resized or cropped images are then fed into the neural network for training. During training, the network learns to extract features and make predictions based on the rectangular input images.

Rectangular training can offer several benefits, including:

* **Improved Generalization**: By training the model on input images with a fixed aspect ratio, rectangular training can help improve the generalization performance of the model, especially when the aspect ratio of the original images in the dataset varies widely.
* **Simplified Implementation**: Rectangular training can simplify the implementation of the neural network model by ensuring that all input images have a consistent aspect ratio. This can make it easier to design and train the model architecture.
* **Efficient Memory Usage**: Resizing or cropping input images to a fixed aspect ratio can help optimize memory usage during training, especially when working with limited computational resources such as GPU memory.

Overall, rectangular training is a useful technique for training neural network models on datasets with variable aspect ratios, and it can help improve the performance and efficiency of the training process.


# Autoanchor

Disabling autoanchor check typically refers to turning off or bypassing the automatic anchor box generation process during object detection training. Anchor boxes are a crucial component in many object detection algorithms, such as YOLO (You Only Look Once), as they provide prior knowledge about the shape and size of objects in the image, which helps in predicting accurate bounding boxes.

However, in some cases, such as when you have a highly customized dataset or when the default anchor boxes do not suit your specific use case, you may want to disable the autoanchor check and manually provide anchor box configurations.

Here's how you might disable the autoanchor check in different object detection frameworks:

1. **YOLOv5**: In YOLOv5, you can disable the autoanchor check by setting the `autoanchor` parameter to `False` in the model configuration YAML file. For example:

   ```yaml
   model:
     ...
     autoanchor: False
     ...
   ```
2. **YOLOv4**: YOLOv4 does not have a built-in option to disable autoanchor, but you can manually configure anchor boxes by providing a custom anchor configuration file. You would need to specify the anchor box sizes manually in the configuration file.
3. **Detectron2**: In Detectron2, you can specify custom anchor sizes and aspect ratios in the model configuration YAML file under the `MODEL.ANCHOR_GENERATOR.SIZES` and `MODEL.ANCHOR_GENERATOR.ASPECT_RATIOS` parameters. By manually specifying anchor sizes and aspect ratios, you effectively disable the autoanchor check.
4. **Custom Implementations**: If you're using a custom implementation of an object detection algorithm, you would need to modify the code responsible for generating anchor boxes to disable the autoanchor check. This might involve commenting out or removing the relevant code that automatically generates anchor boxes.

Keep in mind that disabling the autoanchor check requires you to provide custom anchor box configurations manually, which may require some experimentation and tuning to achieve optimal results for your specific dataset and use case.


# Weighted image

Weighted image selection for training is a technique used to address class imbalance in the dataset during training. In scenarios where certain classes are underrepresented compared to others, training a neural network model without addressing this class imbalance can lead to biased predictions and poor performance, especially for minority classes.

Here's how you can use weighted image selection for training:

1. **Calculate Class Weights**: First, calculate the class weights based on the frequency of each class in the dataset. Class weights are typically calculated as the inverse of the class frequencies or using more sophisticated techniques like inverse class frequency scaling.
2. **Assign Weights to Images**: Assign weights to individual images in the dataset based on the class weights. Images belonging to minority classes are assigned higher weights to give them more influence during training, while images belonging to majority classes are assigned lower weights.
3. **Weighted Sampling**: During training, use weighted sampling to select images for each minibatch. Weighted sampling ensures that images with higher weights (belonging to minority classes) are sampled more frequently compared to images with lower weights (belonging to majority classes).
4. **Training**: Train the neural network model using the weighted image selection strategy. During each training iteration, images are sampled according to their weights, and the model is updated based on the loss computed using the sampled images.

Implementing weighted image selection for training may require customizing the data loading pipeline or using libraries that support weighted sampling, such as PyTorch's `WeightedRandomSampler`.

Here's an example of how you might implement weighted image selection using PyTorch:

```python
import torch
from torch.utils.data import DataLoader, WeightedRandomSampler

# Assuming class_weights is a dictionary containing class frequencies or weights
class_weights = {0: 0.1, 1: 0.9}  # Example class weights

# Assuming dataset is your custom dataset
dataset = CustomDataset(...)

# Calculate weights for each image based on their class labels
weights = [class_weights[label] for _, label in dataset]

# Create a WeightedRandomSampler to sample images based on their weights
sampler = WeightedRandomSampler(weights, len(weights))

# Create a DataLoader with the weighted sampler
dataloader = DataLoader(dataset, batch_size=batch_size, sampler=sampler)

# Use the dataloader for training
for inputs, labels in dataloader:
    ...
```

By using weighted image selection for training, you can mitigate the effects of class imbalance and improve the performance of your neural network model, especially for datasets with imbalanced class distributions.


# multi scale

Using varying image sizes, also known as multi-scale training, is a technique often employed in object detection tasks to improve the robustness and generalization of the trained model. Multi-scale training involves training the model on images of different sizes, allowing it to learn to detect objects at various scales.

Here's how you can implement multi-scale training with varying image sizes:

1. **Define Image Size Range**: Determine the range of image sizes you want to use for training. This range typically involves scaling the original image size up and down by a certain percentage.
2. **Randomly Select Image Size**: For each training iteration or mini-batch, randomly select an image size from the defined range. This randomness helps introduce variability and prevents the model from overfitting to a specific scale.
3. **Resize Images**: Resize the training images to the selected size before feeding them into the model for training. This ensures that the model receives training samples of different scales in each iteration.
4. **Training**: Train the model using the resized images. The model should learn to detect objects at various scales, leading to improved generalization and robustness.

Here's an example of how you might implement multi-scale training in Python using the PyTorch framework:

```python
import random
import torch
from torchvision import transforms

# Define the range of image sizes (e.g., +/- 50% of the original size)
min_scale = 0.5
max_scale = 1.5

# Custom dataset and DataLoader setup
# Assuming dataset is your custom dataset

# Define a function to randomly select an image size from the defined range
def random_resize(image, min_scale, max_scale):
    target_scale = random.uniform(min_scale, max_scale)
    new_width = int(image.width * target_scale)
    new_height = int(image.height * target_scale)
    return transforms.Resize((new_height, new_width))(image)

# Define a transformation to resize images to the randomly selected size
transform = transforms.Compose([
    transforms.ToPILImage(),
    transforms.Lambda(lambda img: random_resize(img, min_scale, max_scale)),
    transforms.ToTensor(),
    # Add other transformations as needed (e.g., normalization)
])

# Apply the transformation to the dataset
# Assuming dataset is a PyTorch Dataset object
dataset = dataset.transform(transform)

# DataLoader setup
# Assuming batch_size, num_workers, etc., are defined elsewhere
dataloader = torch.utils.data.DataLoader(dataset, batch_size=batch_size, num_workers=num_workers, shuffle=True)
```

In this example, each image in the dataset is randomly resized to a scale within the defined range (50% smaller to 50% larger than the original size) before being fed into the model for training. This process helps the model learn to detect objects at various scales, leading to improved performance and robustness.


# learning rate

The learning rate is a hyperparameter that controls the step size during the optimization process of training a neural network. It determines how much the model parameters are adjusted in each iteration of the optimization algorithm, such as stochastic gradient descent (SGD) or its variants.

Choosing an appropriate learning rate is crucial for successful training. A learning rate that is too high can cause the optimization algorithm to overshoot the minimum of the loss function, leading to unstable training or divergence. On the other hand, a learning rate that is too low can result in slow convergence and may get stuck in local minima.

Here are some common strategies for setting the learning rate:

1. **Manual Tuning**: Start with a moderate learning rate and manually adjust it based on the training performance. Monitor the training and validation loss curves and adjust the learning rate accordingly. This approach requires experimentation and domain knowledge.
2. **Learning Rate Schedulers**: Use learning rate schedulers to automatically adjust the learning rate during training. Common learning rate schedules include step decay, exponential decay, and cosine annealing. Learning rate schedulers gradually decrease the learning rate over time to fine-tune the model as training progresses.
3. **Grid Search or Random Search**: Perform a grid search or random search over a range of learning rates to find the optimal value. This approach involves training multiple models with different learning rates and selecting the one with the best performance on a validation set.
4. **Adaptive Learning Rate Methods**: Use adaptive learning rate methods such as Adam, RMSProp, or Adagrad, which automatically adjust the learning rate based on the gradients observed during training. These methods can be effective in many scenarios and often require less manual tuning compared to traditional SGD.
5. **Learning Rate Warmup**: Start training with a lower learning rate and gradually increase it during the initial phase of training. Learning rate warmup helps stabilize training and prevent divergence, especially when using large learning rates.

The optimal learning rate depends on factors such as the dataset, model architecture, and optimization algorithm. It often requires experimentation and fine-tuning to find the best value for a specific task. Regular monitoring of the training progress and validation performance is essential for selecting an appropriate learning rate strategy.


# Momentum

The momentum of an optimizer is a hyperparameter that controls the contribution of the previous update to the current update during the training process of a neural network. It is particularly used in optimization algorithms like stochastic gradient descent (SGD) with momentum, RMSprop, and Adam.

In the context of SGD with momentum, which is one of the most common optimization algorithms used for training neural networks, the momentum parameter enhances the search for the optimum by helping the optimizer to continue moving in the same direction as the previous updates. This helps to overcome local minima and accelerate convergence to the global minimum.

Here's how momentum works in SGD:

1. **Update Rule**: In addition to the gradient of the current minibatch, the optimizer also considers a fraction of the previous update direction, scaled by the momentum parameter.
2. **Acceleration**: When the gradients consistently point in the same direction over multiple iterations, momentum accelerates the learning process by amplifying the size of the updates. This allows the optimizer to traverse flat regions of the loss landscape more quickly.
3. **Damping Oscillations**: Momentum also helps dampen oscillations in the optimization process by smoothing out the update trajectory. This can lead to more stable training and faster convergence.

The momentum parameter is typically set to a value between 0 and 1, where 0 corresponds to no momentum (i.e., standard SGD) and 1 corresponds to full momentum (i.e., the optimizer only considers the previous update direction). A common choice for the momentum parameter is around 0.9, but the optimal value may vary depending on the dataset and architecture.

Here's an example of how you might set the momentum parameter in PyTorch:

```python
import torch.optim as optim

# Define your model and other training parameters
...

# Set the momentum parameter when defining the optimizer
optimizer = optim.SGD(model.parameters(), lr=0.001, momentum=0.9)
```

In this example, the momentum parameter is set to 0.9, which is a commonly used value in practice. However, you may need to experiment with different values to find the one that works best for your specific task and dataset.


# Deployment

In the development section, you can search for your model based on its ID or the filters:

like framework, model and history ,  ...&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FNjCf22RkJN9yRWsdH751%2FScreenshot%20(1023).png?alt=media&amp;token=ca6f24a0-7872-42f2-8760-191f06de5b71" alt=""><figcaption></figcaption></figure>

In the deployment phase, there are two versions available for development:

1. Legacy Deployment:

Legacy Deployment offers traditional deployment methods for AI models. Users can deploy their trained models using this approach. The deployment process involves packaging the model along with its dependencies and deploying it on the desired infrastructure.

#### 2. Deployment Model (Triton-based):

Deployment Model utilizes Triton, an advanced model serving platform developed by NVIDIA. Triton provides high-performance inference with support for various hardware accelerators. It offers features such as dynamic batching, concurrent model execution, and multi-model serving.

#### Features:

* **Model Training**: Train your AI models using custom datasets and algorithms.
* **Legacy Deployment**: Deploy trained models using traditional methods.
* **Triton-based Deployment**: Deploy models on Triton for optimized performance.
* **Scalability**: Scale deployments based on demand and resource availability.
* **Monitoring**: Monitor model performance, resource utilization, and server health.
* **API Integration**: Integrate the service with your applications via RESTful APIs.

In box number 2, you can access your trained models by specifying filters.

In box number 3 and 4 You can view the information and specifications of the model.

In box number 5 You can obtain output and inference from the desired model.

By pressing "MORE," you can start development and obtain the API address or download the model.


# Legacy

Legacy deployment refers to the traditional and older method of deploying artificial intelligence models for use in production environments. This approach is typically used when pre-trained models need to be deployed and utilized in production systems. Below are the details regarding development and deployment using the legacy approach:

1. **Development**:
   * During the development phase, the AI model is trained and optimized using training data.
   * This phase involves selecting and training the appropriate model architecture, tuning parameters, applying training techniques, and evaluating model performance.
2. **Preparation for Deployment**:
   * After training the model, it needs to be converted to an executable format and prepared for deployment.
   * This involves converting the model to standard formats such as TensorFlow SavedModel or ONNX and requires advanced configuration for execution in different environments.
3. **Deployment**:
   * In this stage, the prepared model is deployed on servers or local systems.
   * It includes installing and configuring the necessary systems for execution, transferring the model to the production environment, and running the model to respond to input requests.
4. **Maintenance and Monitoring**:
   * After deployment, the model needs to be maintained and its performance monitored.
   * This includes monitoring the model's performance, tracking resource consumption, troubleshooting, and necessary updates for improving performance.

In summary, in legacy deployment, pre-trained models are executed on servers or local systems to function as part of production systems and provide services.


# Deployment model (Triton)

Triton is an advanced model serving platform developed by NVIDIA. It offers a highly optimized and scalable solution for deploying deep learning models in production environments. Here's some information about Triton:

1. **Scalability**: Triton is designed to handle large-scale deployments and can scale to serve thousands of models concurrently. It efficiently utilizes resources to handle varying workloads and can be deployed across multiple nodes for increased capacity.
2. **High Performance**: Triton leverages NVIDIA GPUs to deliver high-performance inference, enabling fast and efficient processing of inference requests. It supports GPU acceleration, allowing deep learning models to take full advantage of GPU computing power for inference tasks.
3. **Model Optimization**: Triton includes features for optimizing model inference, such as dynamic batching and concurrent model execution. Dynamic batching optimizes inference by dynamically batching together multiple inference requests, reducing overhead and improving throughput. Concurrent model execution allows multiple models to run simultaneously on the same GPU, maximizing GPU utilization.
4. **Model Management**: Triton provides capabilities for managing and versioning models, making it easy to deploy and update models in production environments. It supports model versioning, allowing multiple versions of the same model to coexist and be served concurrently. Additionally, Triton supports model health monitoring and automatic model rollback in case of failures.
5. **Flexible Deployment Options**: Triton offers flexibility in deployment options, supporting deployment on-premises, in the cloud, or at the edge. It can be integrated with existing infrastructure and deployed in Kubernetes clusters for containerized deployments. Triton also provides APIs for seamless integration with other services and frameworks.

Overall, Triton simplifies the deployment and management of deep learning models in production environments, providing high performance, scalability, and flexibility for serving AI applications.


# Introducing the BinaExperts SDK

A Powerful Computer Vision Toolkit

We’re excited to announce the release of the **BinaExperts SDK**! This comprehensive and flexible toolkit is designed to simplify processes in computer vision projects, offering features like **data format conversion** and **data processing** with ease and efficiency.

The SDK is perfect for machine vision tasks, supporting popular formats like **COCO**, **YOLOv5**, and **BinaExperts**, making data management and conversion seamless and efficient.

## Key Features

🔹 **Data Format Conversion:**\
Easily convert datasets between COCO, YOLOv5, and BinaExperts formats, simplifying complex workflows.

🔹 **Modular and Extensible Design:**\
A future-ready architecture designed to grow with additional formats and features in upcoming versions.

🔹 **In-Memory Processing:**\
Perform real-time conversions without intermediate files, ideal for serverless environments and rapid processing needs.

#### **How to Get Started**

**Step 1:** Install the SDK with a single command:

```bash
bashCopy codepip install binaexperts
```

**Step 2:** Convert datasets effortlessly:

* **From files:** Read and transform datasets directly from files.
* **In-memory:** Perform fast, real-time data transformations without creating temporary files.

For detailed instructions and code examples, check out the [full documentation](https://pypi.org/project/binaexperts/).

#### **What’s Next for the BinaExperts SDK?**

💡 **Advanced Features:** More robust data conversion tools and support for additional formats.\
💡 **New Capabilities:** Training and inference functionalities to streamline the development of computer vision models.

**Ready to Get Started?**\
Elevate your computer vision projects with the BinaExperts SDK, making them faster, simpler, and more efficient.\
[Explore the Documentation](https://pypi.org/project/binaexperts/) and unlock the potential of advanced computer vision tools!


# ابزارهای نشانه گذاری

ابزارهای حاشیه‌نویسی تصاویر را برای استفاده در پروژه‌های بینایی کامپیوتری خود حاشیه‌نویسی کنید. BinaExperts Annotate یک رابط کاربری سریع و قوی فراهم می‌کند که از طریق آن می‌توانید تصاویر را حاشیه‌نویسی کنید. می‌توانید تصاویر را با استفاده از جعبه‌های مرزی (bounding boxes) و چندضلعی‌ها (polygons) حاشیه‌نویسی کنید.

روش‌های حاشیه‌نویسی می‌توانید تصاویر را به روش‌های زیر حاشیه‌نویسی کنید:

* رسم دستی جعبه‌های مرزی و چندضلعی‌ها
* استفاده از AutoLabel، ابزاری که از نقاط بازبینی مدل (یعنی نسخه‌های قبلی مدل شما) برای پیشنهاد حاشیه‌نویسی‌ها استفاده می‌کند
* استفاده از Smart Polygon، ویژگی‌ای که با چند کلیک چندضلعی‌ها را ایجاد می‌کند.
* استفاده از Label Assist با SAM، که از مدل "Segment Anything" برای ایجاد حاشیه‌نویسی‌های دقیق‌تر چندضلعی با چند کلیک استفاده می‌کند.

تصویر بارگذاری شود

جعبه‌های مرزی در مقابل چندضلعی‌ها با داشتن گزینه‌ای بین رسم جعبه‌های مرزی و چندضلعی‌ها، ممکن است این سؤال پیش بیاید: تفاوت بین این دو نوع حاشیه‌نویسی چیست؟ جعبه‌های مرزی -- جعبه‌هایی که دور یک شیء مورد نظر در تصویر رسم می‌شوند -- آسان‌تر از چندضلعی‌ها هستند، بنابراین زمان حاشیه‌نویسی کمتری می‌گیرند. از طرفی، چندضلعی‌ها دقیق‌تر هستند و ممکن است منجر به افزایش جزئی در عملکرد شوند. برای وظایف بخش‌بندی (segmentation)، نیاز است تصاویر را با چندضلعی‌ها حاشیه‌نویسی کنید، زیرا شما مدل خود را برای بخش‌بندی دقیق آیتم‌های خاص از تصویر آموزش می‌دهید. این بخش از مستندات BinaExpert نحوه حاشیه‌نویسی تصاویر با استفاده از هر یک از روش‌های فوق را نشان می‌دهد.


# استفاده از نشانه گذاری بینااکسپرتز

#### استفاده از ابزار حاشیه‌نویسی BinaExpert

**مروری بر رابط کاربری برچسب‌گذاری ابزار حاشیه‌نویسی BinaExpert، شامل کلیدهای میانبر:**

* **Drag and Select (کشیدن و انتخاب)**
* **Bounding Box Annotation Tool (ابزار حاشیه‌نویسی جعبه مرزی)**
* **Polygon Annotation Tool (ابزار حاشیه‌نویسی چندضلعی)**
* **Smart Polygon (چندضلعی هوشمند)**
* **Label Assist (کمک برچسب)**
* **Zoom Tool (ابزار بزرگنمایی)**

#### کشیدن و انتخاب

نماد این ویژگی یک آیکون دست است که به شما اجازه می‌دهد حاشیه‌نویسی‌های فردی را انتخاب، ویرایش و بکشید.

* با کلیک تک‌تک روی یک جعبه مرزی موجود، آن را انتخاب کنید. پس از انتخاب، می‌توانید اندازه جعبه مرزی را با دسته‌های سفید گرد که در گوشه‌ها و هر طرف ظاهر می‌شوند تغییر دهید. یا از ویرایشگر کلاس برای تغییر برچسب جعبه استفاده کنید.
* با کشیدن جعبه، آن را جابجا کنید.
* با فشردن چرخ اسکرول، پس‌زمینه را جابجا کنید.
* برای عدم انتخاب همه جعبه‌ها، روی پس‌زمینه کلیک کنید.

#### ابزار حاشیه‌نویسی جعبه مرزی

ابزار حاشیه‌نویسی جعبه مرزی (که با نماد یک جعبه مستطیلی نشان داده شده) به شما اجازه می‌دهد تا حاشیه‌نویسی‌های جدیدی از نوع جعبه مرزی رسم کنید. در این حالت، شما نشانه‌هایی خواهید دید که به شما کمک می‌کنند تا محل شروع رسم را تعیین کنید.

* با کلیک و کشیدن بر روی تصویر، یک حاشیه‌نویسی جدید ایجاد کنید، سپس از انتخاب‌کننده کلاس برای انتخاب برچسب آن استفاده کنید.

#### ابزار حاشیه‌نویسی چندضلعی

ابزار حاشیه‌نویسی چندضلعی به شما اجازه می‌دهد تا حاشیه‌نویسی‌های چندضلعی جدیدی رسم کنید. در این حالت، شما نشانه‌هایی خواهید دید که به شما کمک می‌کنند تا محل شروع رسم را تعیین کنید.

* بر روی تصویر و اطراف اشیاء مورد نظر کلیک کنید تا یک حاشیه‌نویسی چندضلعی محصور ایجاد کنید، سپس از انتخاب‌کننده کلاس برای انتخاب برچسب آن استفاده کنید.

#### چندضلعی هوشمند

چندضلعی هوشمند به شما اجازه می‌دهد تا حاشیه‌نویسی‌های چندضلعی هوشمند جدیدی رسم کنید.

* در این حالت، شما یک نقطه سبز خواهید دید وقتی که در حال انتخاب یک ناحیه جدید از علاقه‌مندی (برچسب جدید) هستید؛ یک نقطه قرمز وقتی که نواحی را برای حذف از ناحیه علاقه‌مندی انتخاب می‌کنید (قسمت‌هایی از شیء یا تصویر که نمی‌خواهید برچسب‌گذاری کنید یا با چندضلعی محصور کنید)؛ و گزینه‌هایی برای تنظیم چندضلعی با تنظیمات Convex Hull، Smooth و Complex دارید.
* چندضلعی هوشمند به خصوص برای پروژه‌های بخش‌بندی (Instance و Semantic) مفید است، با این حال ممکن است شاهد افزایش عملکرد در مدل‌های تشخیص اشیاء هنگام برچسب‌گذاری با چندضلعی‌های هوشمند روی بینااکسپرتز باشید.

#### بازگشت، دوباره انجام دادن، و تکرار حاشیه‌نویسی‌ها

در حالت‌های Bounding Box (B)، Polygon (P)، یا Smart Polygon (S):

* بازگشت (Undo) عمل قبلی را برمی‌گرداند.
* دوباره انجام دادن (Redo) عمل لغو شده قبلی را معکوس می‌کند.
* تکرار قبلی (Repeat Previous) برچسب‌ها را در مکان(های) مشابه تصویر آخرین حاشیه‌نویسی شده اعمال می‌کند.


# آموزش مدل


# آموزش

در بخش آموزش، شما می‌توانید اطلاعات کلی درباره مدل مشاهده کنید، از جمله تعداد داده‌های آموزشی و آزمایشی.

تصویر بارگذاری شود

#### بخش آموزش وبسایت

بخش "آموزش" وبسایت شامل سه زیر بخش اصلی است: "مشخصات پروژه" (PROJECT SPEC)، "آموزش مدل" (Train Model)، و "نتیجه آموزش" (Train Result).

**مشخصات پروژه (PROJECT SPEC)**

در این بخش، جزئیات و مشخصات پروژه برای آموزش مدل‌های یادگیری ماشین توضیح داده می‌شود. این شامل اهداف، نیازمندی‌ها، محدودیت‌ها و سایر جزئیات مربوط به فرآیند آموزش است. این مستند به عنوان یک راهنمای عمومی برای تیم آموزش و سایر اعضای تیم درگیر در فرآیند آموزش خدمت می‌کند.

**آموزش مدل (Train Model)**

این بخش فرآیند آموزش مدل‌های یادگیری ماشین با استفاده از دیتاست آماده شده قبلی را توضیح می‌دهد. این شامل انتخاب و پیکربندی الگوریتم‌های آموزش، اجرای آموزش و مراحل ارزیابی و بهینه‌سازی مدل‌ها می‌شود.

**نتیجه آموزش (Train Result)**

در این بخش، نتایج و پیشرفت‌های حاصل شده در طول فرآیند آموزش مدل‌های یادگیری ماشین گزارش می‌شود. این شامل معیارهای ارزیابی، نتایج آموزش، نمودارها و هر نوع خروجی دیگری است که در طول فرآیند آموزش مدل تولید شده است.

#### بخش PROJECT SPEC

در بخش "مشخصات پروژه" می‌توانید اطلاعات زیر را بررسی کنید:

* جزئیات مربوط به دیتاست
* اطلاعات افزایش داده
* تصاویر نمونه
* گزینه "بررسی سلامت دیتاست"

تصویر بارگذاری شود

به طور کلی، بخش "آموزش" (Train) برای آموزش دیتاست‌های یادگیری ماشین استفاده می‌شود و جزئیات مربوط به فرآیند آموزش مدل‌ها را فراهم می‌کند. در بخش "آموزش مدل" (Train Model)، شما می‌توانید از فریم‌ورک، مدل و سایر جزئیات برای آموزش مدل خود استفاده کنید.

تصویر بارگذاری شود

#### توضیحات آیتم‌ها:

* **قابل اجرا بر روی GPU (Deployable on GPU)**: این به توانایی یک مدل یا برنامه برای اجرا و پیاده‌سازی بر روی واحدهای پردازش گرافیکی (GPUs) اشاره دارد. GPU‌ها سخت‌افزارهای تخصصی هستند که برای پردازش موازی طراحی شده‌اند و معمولاً برای تسریع وظایف استنتاج یادگیری عمیق به دلیل قدرت محاسباتی بالای خود استفاده می‌شوند.
* **پیاده‌سازی در ابر (Deployment on Cloud)**: این به توانایی پیاده‌سازی یک مدل یا برنامه در پلتفرم‌های رایانش ابری مانند Amazon Web Services (AWS)، Microsoft Azure، یا Google Cloud Platform (GCP) اشاره دارد. پیاده‌سازی در ابر مزایای مقیاس‌پذیری، انعطاف‌پذیری و دسترسی را فراهم می‌کند و به کاربران امکان می‌دهد بدون نیاز به زیرساخت محلی، به منابع از راه دور دسترسی پیدا کنند.
* **دقت بالا (High Accuracy)**: دقت بالا به معنای دستیابی مدل یا سیستم به سطح بالایی از صحت یا دقت در پیش‌بینی‌ها یا نتایج خود است. در زمینه مدل‌های یادگیری ماشین، دقت معمولاً با مقایسه پیش‌بینی‌های مدل با برچسب‌های واقعیت زمینی و ارزیابی معیارهایی مانند دقت، بازیابی، امتیاز F1، یا دقت طبقه‌بندی اندازه‌گیری می‌شود.
* **نتایج سریع (Fast Results)**: این به معنای توانایی مدل یا سیستم در تولید خروجی‌ها یا پیش‌بینی‌ها به سرعت و با حداقل تأخیر یا تأمل است. نتایج سریع در برنامه‌های بلادرنگ یا حساس به زمان که نیاز به تصمیم‌گیری سریع دارند، مانند رانندگی خودکار، تشخیص شیء بلادرنگ، یا پردازش ویدئو، بسیار حیاتی هستند.
* **قابل اجرا بر روی CPU (Deployable on CPU)**: مشابه "قابل اجرا بر روی GPU"، این به توانایی مدل یا برنامه برای اجرا و پیاده‌سازی بر روی واحدهای پردازش مرکزی (CPUs) اشاره دارد. CPU‌ها پردازنده‌های همه منظوره‌ای هستند که در بیشتر دستگاه‌های محاسباتی یافت می‌شوند و برای اجرای طیف گسترده‌ای از برنامه‌های نرم‌افزاری مناسب هستند، از جمله مدل‌های یادگیری ماشین که نیاز به قدرت محاسباتی GPU ندارند.
* **بهینه‌سازی (Optimization)**: بهینه‌سازی شامل فرآیند بهبود عملکرد، کارایی یا استفاده از منابع سیستم یا مدل است. در زمینه یادگیری ماشین، بهینه‌سازی ممکن است شامل تکنیک‌هایی مانند فشرده‌سازی مدل، کمّی‌سازی، هرس کردن، یا بهبودهای الگوریتمی برای کاهش فضای حافظه، تأخیر استنتاج، یا مصرف انرژی باشد و در عین حال دقت را حفظ یا بهبود بخشد.

#### بخش جزئیات آموزش (TRAIN DETAILS)

در بخش "جزئیات آموزش" (TRAIN DETAILS)، شما می‌توانید وضعیت مدل‌هایی را که برای آموزش درخواست کرده‌اید مشاهده کنید. همانطور که در تصویر زیر نشان داده شده است، مدل‌های ارسال شده برای آموزش دارای سه وضعیت هستند:

* **در صف (Queue)**
* **انجام شده (Done)**
* **ناموفق (Failed)**

**تصویر بارگذاری شود**

#### توضیحات بخش جزئیات آموزش (TRAIN DETAILS)

همانطور که در تصویر نشان داده شده است:

* **باکس 1**: می‌توانید فیلترهایی برای جستجوی مدل‌های آموزش‌دیده مشاهده کنید.
* **باکس 2**: می‌توانید وضعیت مدل‌ها را ببینید.
* **باکس 3**: می‌توانید معیارهای مدل آموزش‌دیده مانند MAP و یادآوری (Recall) را پیدا کنید. اگر مدل موفق به گذراندن بررسی سلامت نشود، وضعیت پیشرفت یا دلیل شکست در این بخش مشخص می‌شود، مشابه آنچه که در باکس 4 مشاهده می‌کنید.
* **باکس 5**: می‌توانید جزئیات و لاگ‌ها را مشاهده کنید، مدل را آرشیو کنید، یا به کنسول دسترسی پیدا کنید.

#### امکانات با کلیک بر روی مدل آموزش‌دیده:

با کلیک بر روی مدل آموزش‌دیده، می‌توانید جزئیات زیر را مشاهده کنید:

* **Epochs**: تعداد دوره‌های آموزشی
* **Batches**: تعداد دسته‌های آموزشی
* **Max Size**: حداکثر اندازه
* **Patience**: تعداد دوره‌های بدون بهبود قبل از توقف زودهنگام
* **Momentum**: میزان حرکت
* **Learning Rate**: نرخ یادگیری

همچنین می‌توانید مدل آموزش‌دیده را تست کنید و بصری‌سازی آن را با استفاده از TensorBoard مشاهده کنید.\
\
تصویر بارگذاری شود

در بخش “نتایج آموزش مدل”، شما به راحتی می‌توانید خروجی‌های مدل را بر روی مجموعه‌های آزمون و اعتبارسنجی مشاهده کنید.

تصویر بارگذاری شود


# چارچوب ها

PyTorch و TensorFlow دو فریمورک پرکاربرد در حوزه یادگیری عمیق هستند.

**PyTorch**، محصولی از Facebook’s AI Research lab (FAIR)، با قابلیت‌هایی مانند سازگاری بالا با پایتون، سادگی استفاده و فراهم کردن امکانات پیشرفته برای ساخت شبکه‌های عصبی، مورد توجه بسیاری از محققان و توسعه‌دهندگان قرار گرفته است.

**TensorFlow**، که توسط تیم Google Brain توسعه یافته، یکی از محبوب‌ترین فریمورک‌ها در حوزه یادگیری ماشین است. این فریمورک با قابلیت‌هایی مانند پشتیبانی از محاسبات توزیع‌شده، ابزارهای متنوع برای مصورسازی و امکان استفاده از سخت‌افزارهای مختلف مانند GPU و TPU، جای خود را در بین کاربران حفظ کرده است.

**NVIDIA TAO Toolkit** یک ابزار کد باز است که فرآیند ایجاد مدل‌های هوش مصنوعی سفارشی و آماده برای کسب و کار را ساده و سریع می‌کند. [این ابزار از یادگیری انتقالی، تبدیل‌کننده‌های دید، AutoML و فناوری مبتنی بر ابر برای ارائه دقت و عملکرد بالا در هر پلتفرمی استفاده می‌کند](https://developer.nvidia.com/tao-toolkit)[1](https://developer.nvidia.com/tao-toolkit).

**Triton Inference Server** یک نرم‌افزار سرور است که استانداردسازی اجرای مدل‌های هوش مصنوعی را در هر بار فراهم می‌کند. [این سرور از مدل‌های آموزش داده شده از بسیاری از چارچوب‌ها، از جمله TensorFlow، TensorRT، PyTorch و ONNX پشتیبانی می‌کند](https://www.nvidia.com/en-us/ai-data-science/products/triton-inference-server/)


# تنسورفلو

TensorFlow یک فریمورک یادگیری عمیق قدرتمند و پرکاربرد است که مزایای متعددی دارد ولی همچنین برخی محدودیت‌ها نیز دارد. در زیر، من مزایا و معایب استفاده از TensorFlow را شرح می‌دهم، از جمله اجزای آن مانند MAP (Mean Average Precision) و دیگران:

مزایا:

* **انعطاف‌پذیری**: TensorFlow امکان ساخت و سفارشی‌سازی مدل‌های یادگیری عمیق را فراهم می‌کند. این فریمورک APIهای سطح بالا (مانند Keras) برای نمونه‌سازی سریع و APIهای سطح پایین برای کنترل دقیق بر معماری مدل و فرآیند آموزش ارائه می‌دهد.
* **مقیاس‌پذیری**: TensorFlow برای مقیاس‌پذیری طراحی شده است، امکان آموزش و اجرای مدل‌ها را بر روی پلتفرم‌های سخت‌افزاری مختلف، از جمله CPUها، GPUها و TPUها فراهم می‌کند. این فریمورک از آموزش توزیع‌شده بر روی چندین دستگاه و سرور پشتیبانی می‌کند، امکان استفاده کارآمد از منابع محاسباتی را فراهم می‌کند.
* **اکوسیستم غنی**: TensorFlow دارای یک اکوسیستم غنی با محدوده وسیعی از ابزارها و کتابخانه‌ها برای وظایف مختلف در یادگیری عمیق است، از جمله بینایی کامپیوتری، پردازش زبان طبیعی، یادگیری تقویتی و بیشتر. این شامل مدل‌های از پیش آموخته شده، ابزارهای پیش‌پردازش داده، ابزارهای تصویرسازی و گزینه‌های استقرار است.
* **کارایی**: TensorFlow برای کارایی بهینه‌سازی شده است، با پیاده‌سازی‌های کارآمد عملیات اصلی و پشتیبانی از شتاب سخت‌افزاری. این فریمورک از CUDA و cuDNN برای شتاب GPU و XLA برای بهینه‌سازی محاسبات استفاده می‌کند.
* **پشتیبانی از جامعه**: TensorFlow یک جامعه بزرگ و فعال از توسعه‌دهندگان و پژوهشگران دارد که به توسعه آن کمک می‌کنند، دانش و بهترین روش‌ها را به اشتراک می‌گذارند و از طریق انجمن‌ها، مستندات و آموزش‌ها پشتیبانی می‌کنند.

معایب:

* **پیچیدگی**: TensorFlow می‌تواند پیچیده و چالش‌برانگیز باشد، به خصوص برای مبتدیان. مستندات گسترده و منحنی یادگیری شیب‌دار آن ممکن است نیاز به زمان و تلاش اضافی برای تسلط بر استفاده از این فریمورک به طور موثر داشته باشد.
* **سینتکس طولانی**: API سطح پایین تنسورفلو می‌تواند منجر به کد طولانی و قالبی شود، به خصوص برای تعریف معماری شبکه عصبی پیچیده و حلقه‌های آموزش. این می‌تواند کد را سخت‌تر برای خواندن و نگهداری کند.
* **اشکال‌زدایی و تصویرسازی**: اشکال‌زدایی کد تنسورفلو و تصویرسازی رفتار مدل می‌تواند به دلیل طبیعت گراف محاسباتی ثابت آن چالش‌برانگیز باشد. این ممکن است نیاز به ابزارها و تکنیک‌های اضافی برای اشکال‌زدایی و تصویرسازی موثر داشته باشد.
* **تنظیم کارایی**: در حالی که تنسورفلو بهینه‌سازی‌های کارایی ارائه می‌دهد، دستیابی به کارایی بهینه ممکن است نیاز به تخصص در پیکربندی سیستم، بهینه‌سازی مدل و انتخاب سخت‌افزار داشته باشد. تنظیم هایپرپارامترها و بهینه‌سازی معماری مدل نیز می‌تواند وقت‌گیر باشد.
* **رقابت و جایگزین‌ها**: تنسورفلو با رقابت از سایر فریمورک‌های یادگیری عمیق مانند PyTorch روبرو است، که ممکن است تعادل متفاوتی در زمینه سهولت استفاده، انعطاف‌پذیری و کارایی ارائه دهند. انتخاب فریمورک مناسب بستگی به نیازها و محدودیت‌های خاص پروژه دارد.

اجزای تنسورفلو:

* **MAP (Mean Average Precision)**: MAP یک معیار متداول برای ارزیابی مدل‌های تشخیص اشیاء است. این معیار دقت میانگین را در کلاس‌های مختلف اندازه‌گیری می‌کند و آن‌ها را میانگین می‌گیرد تا یک امتیاز عملکرد تکی به دست آورد.
* **TensorFlow Serving**: TensorFlow Serving یک سیستم سرویس دهی فراهم کننده، با کارایی بالا برای استقرار مدل‌های یادگیری ماشین در
* TensorBoard: TensorBoard یک ابزار نمایش برای TensorFlow است که به کاربران امکان می‌دهد تا بخش‌های مختلف مدل‌های یادگیری عمیق خود را، از جمله معیارهای آموزش و ارزیابی، نمودارهای مدل و تعبیه‌ها را ببینند و مورد بررسی قرار دهند.
* TensorFlow Lite: TensorFlow Lite نسخه سبک TensorFlow است که برای دستگاه‌های تلفن همراه و تعبیه شده طراحی شده است. این امکان استنتاج مدل‌های TensorFlow را بر روی دستگاه‌های لبه با منابع محاسباتی محدود، مانند گوشی‌های هوشمند، دستگاه‌های IoT و میکروکنترلرها را فراهم می‌کند.
* TensorFlow Extended (TFX): TensorFlow Extended یک پلتفرم از ابتدا تا انتها برای استقرار خطوط لوله یادگیری ماشین آماده تولید است. این ابزارها و کتابخانه‌ها را برای اعتبارسنجی داده، پیش‌پردازش، آموزش، خدمت، و نظارت بر مدل‌های یادگیری ماشین در مقیاس فراهم می‌کند.

در کل، TensorFlow یک پلتفرم قدرتمند و چندمنظوره برای ساخت، آموزش و استقرار مدل‌های یادگیری عمیق ارائه می‌دهد، اما همچنین دارای مجموعه خود از پیچیدگی‌ها و چالش‌ها است که کاربران باید از آنها آگاه باشند و در مواجهه با آنها به طور مناسب عمل کنند.

TensorFlow یک فریمورک محبوب یادگیری عمیق است که توسط Google توسعه یافته است. برای استقرار مدل‌های مبتنی بر TensorFlow خود، این مراحل را دنبال کنید:

1. **بهینه‌سازی مدل**: قبل از استقرار، مدل‌های TensorFlow خود را برای استنتاج با کوانتیزه کردن، هرس کردن یا تبدیل آنها به فرمت TensorFlow Lite برای اجرای کارآمد بر روی دستگاه‌های تولید بهینه کنید.
2. **TensorFlow Serving**: از TensorFlow Serving استفاده کنید، یک سیستم سرویس دهی فراهم کننده، با کارایی بالا برای مدل‌های یادگیری ماشین، برای استقرار مدل‌های TensorFlow خود به صورت مقیاس‌پذیر و آماده تولید. سرور را برای رسیدگی به درخواست‌ها به طور کارآمد پیکربندی کنید و عملکرد آن را نظارت کنید.


# پایتورچ

مزایا و معایب استفاده از فریمورک یادگیری عمیق PyTorch، از جمله اجزای آن مانند MAP (Mean Average Precision) و دیگران، به شرح زیر است:

مزایای PyTorch:

* **سادگی استفاده**: PyTorch به خاطر سادگی و آسانی استفاده‌اش، به ویژه برای پژوهشگران و مبتدیان در یادگیری عمیق، شناخته شده است. گراف محاسباتی پویای آن امکان ساخت مدل به صورت بصری و اشکال‌زدایی را فراهم می‌کند، با سینتکس مشابه پایتون و سبک برنامه‌نویسی فرمانی.
* **انعطاف‌پذیری و قابلیت بیان**: PyTorch انعطاف‌پذیری و قابلیت بیان در طراحی مدل و آزمایش را ارائه می‌دهد. این فریمورک یک API سطح بالا (مانند torch.nn) برای ساخت معماری‌های شبکه عصبی پیچیده و یک API سطح پایین (مانند torch.autograd) برای کنترل دقیق بر روی گرادیان‌ها و محاسبات ارائه می‌دهد.
* **گراف محاسباتی پویا**: گراف محاسباتی پویای PyTorch امکان ساخت گراف پویا در زمان اجرا را فراهم می‌کند، امکان بیشتری برای انعطاف‌پذیری در معماری‌های مدل و استفاده کارآمد از حافظه را فراهم می‌کند. این امر تسهیل در اشکال‌زدایی و تغییر مدل‌ها در حین اجرا را فراهم می‌کند.
* **پشتیبانی قوی از جامعه**: PyTorch یک جامعه قوی و در حال رشد از توسعه‌دهندگان، پژوهشگران و عملگران دارد که به توسعه آن کمک می‌کنند، دانش را به اشتراک می‌گذارند و از طریق انجمن‌ها، مستندات و آموزش‌ها پشتیبانی می‌کنند. مدل توسعه محور جامعه نوآوری و همکاری را ترویج می‌کند.
* **یکپارچگی با اکوسیستم پایتون**: PyTorch به طور بی‌درنگ با اکوسیستم پایتون یکپارچه می‌شود، که امکان استفاده آسان از کتابخانه‌ها و ابزارهای موجود برای پردازش داده، تصویرسازی و استقرار را فراهم می‌کند. همچنین از تعامل با آرایه‌های NumPy پشتیبانی می‌کند، که امکان مدیریت داده‌ها را آسان می‌کند.

معایب PyTorch:

* **پیچیدگی استقرار**: استقرار مدل‌های PyTorch در محیط‌های تولید می‌تواند پیچیده‌تر از فریمورک‌های دیگر مانند TensorFlow باشد. در حالی که PyTorch ابزارهایی مانند TorchScript و TorchServe را برای استقرار مدل ارائه می‌دهد، راه‌اندازی خطوط لوله تولید ممکن است نیاز به تلاش و تخصص اضافی داشته باشد.
* **بهینه‌سازی کارایی**: دستیابی به کارایی بهینه با مدل‌های PyTorch ممکن است نیاز به بهینه‌سازی دستی و تنظیم هایپرپارامترها، معماری مدل و پیکربندی‌های سخت‌افزاری داشته باشد. این می‌تواند وقت‌گیر و چالش‌برانگیز باشد، به خصوص برای برنامه‌های مقیاس بزرگ.
* **پذیرش محدود در صنعت**: با وجود محبوبیت رو به افزایش PyTorch، این فریمورک در برخی از صنایع و حوزه‌ها نسبت به فریمورک‌های دیگر مانند TensorFlow، پذیرش محدودتری داشته است. این ممکن است منجر به کمبود منابع، کتابخانه‌ها و پشتیبانی جامعه متناسب با موارد استفاده خاص شود.
* **پشتیبانی از گراف استاتیک**: در حالی که PyTorch عمدتاً از گراف‌های محاسباتی پویا استفاده می‌کند، این فریمورک نیز از گراف‌های محاسباتی استاتیک از طریق ماژول TorchScript پشتیبانی می‌کند. با این حال، پشتیبانی از گراف استاتیک ممکن است در برخی از برنامه‌ها به اندازه فریمورک‌های دیگر بالغ یا کارآمد نباشد.
* **منحنی یادگیری برای کاربران سنتی ML**: کاربران سنتی یادگیری ماشین که به گراف‌های محاسباتی استاتیک عادت کرده‌اند، ممکن است با رویکرد پویای PyTorch غیرآشنا باشند، که منجر به منحنی یادگیری هنگام انتقال به این فریمورک می‌شود.

در کل، PyTorch یک پلتفرم قدرتمند و انعطاف‌پذیر برای تحقیق و توسعه یادگیری عمیق ارائه می‌دهد، با قوت در سادگی استفاده، انعطاف‌پذیری و یکپارچگی با اکوسیستم پایتون. در حالی که ممکن است برخی محدودیت‌ها و چالش‌ها داشته باشد، PyTorch همچنان در حال تکامل است و در جامعه یادگیری عمیق ادامه می‌یابد.


# انویدیا تاو

NVIDIA TAO (Toolkit for Adaptive Optimization) بخشی از مجموعه ابزارهای یادگیری انتقالی (Transfer Learning Toolkit) است که ابزارها و جریان‌های کاری را برای بهینه‌سازی مدل‌های از پیش آموزش‌دیده شده بر روی داده‌های سفارشی فراهم می‌کند. برای استقرار مدل‌هایی که با TAO آموزش داده شده‌اند، مراحل زیر را دنبال کنید:

1. **آموزش مدل**: مدل‌های یادگیری عمیق خود را با استفاده از TAO بر روی GPUهای NVIDIA آموزش دهید. از مدل‌های از پیش آموزش‌دیده شده و تکنیک‌های یادگیری انتقالی برای انجام وظایفی مانند تشخیص اشیاء، تقسیم‌بندی یا طبقه‌بندی استفاده کنید.
2. **بهینه‌سازی استنتاج**: مدل‌های آموزش‌دیده خود را برای استقرار بر روی سخت‌افزار NVIDIA با استفاده از TensorRT، کتابخانه استنتاج یادگیری عمیق با عملکرد بالا از NVIDIA، بهینه‌سازی کنید. مدل‌های خود را به فرمت TensorRT تبدیل کنید و از بهینه‌سازی‌هایی مانند کم‌دقتی INT8 و ترکیب لایه‌ها برای استنتاج سریع‌تر استفاده کنید.


# تنسورفلو لایت

TensorFlow Lite (TFLite) یک راه‌حل سبک برای استقرار مدل‌های یادگیری ماشین بر روی دستگاه‌های موبایل و تعبیه‌شده است. برای استقرار مدل‌های TensorFlow Lite مراحل زیر را دنبال کنید:

1. **تبدیل مدل**: مدل‌های TensorFlow خود را با استفاده از ابزارهای ارائه‌شده توسط TensorFlow به فرمت TensorFlow Lite تبدیل کنید. سازگاری با پلتفرم هدف خود را بررسی کنید و مدل را برای سرعت استنتاج و کاهش حجم حافظه بهینه کنید.
2. **ادغام با اپلیکیشن‌های موبایل**: مدل TensorFlow Lite را در اپلیکیشن موبایل یا تعبیه‌شده خود ادغام کنید. از APIهای مفسر TensorFlow Lite استفاده کنید تا استنتاج را روی دستگاه انجام دهید و پیش‌بینی‌های بلادرنگ بدون وابستگی به اتصال شبکه فراهم کنید.


# مدل


# یولو

YOLO، که مخفف "You Only Look Once" است، یک الگوریتم محبوب برای تشخیص اشیاء در زمان واقعی است که اشیاء خاص را در تصاویر یا ویدئوها شناسایی می‌کند. برخلاف الگوریتم‌های سنتی تشخیص اشیاء که به مراحل متعدد یا نواحی علاقه‌مند تکیه دارند، YOLO یک شبکه عصبی واحد را به کل تصویر در یک مرحله اعمال می‌کند. این ویژگی به YOLO امکان می‌دهد تا به سرعت استنتاج در زمان واقعی دست یابد و آن را برای کاربردهایی مانند نظارت، وسایل نقلیه خودران و تحلیل ویدئو مناسب می‌کند.

ویژگی‌های کلیدی YOLO شامل موارد زیر است:

1. **تشخیص در یک مرحله**: YOLO تصویر ورودی را به یک شبکه تقسیم کرده و جعبه‌های محصور و احتمال‌های کلاس را مستقیماً از سلول‌های شبکه پیش‌بینی می‌کند. این ویژگی به YOLO امکان می‌دهد تا چندین شیء را در یک مرحله از طریق شبکه عصبی شناسایی کند، که منجر به سرعت استنتاج سریع می‌شود.
2. **چارچوب یکپارچه**: YOLO یک چارچوب یکپارچه است که همزمان هم مکان‌یابی شیء و هم طبقه‌بندی را انجام می‌دهد. به جای جدا کردن این وظایف به مراحل مختلف، YOLO جعبه‌های محصور و احتمال‌های کلاس را مستقیماً از تصویر ورودی پیش‌بینی می‌کند، که منجر به تشخیص اشیاء کارآمد و دقیق می‌شود.
3. **جعبه‌های لنگر**: YOLO از جعبه‌های لنگر برای بهبود دقت مکان‌یابی شیء استفاده می‌کند. جعبه‌های لنگر شکل‌های از پیش تعریف شده‌ای هستند که نسبت‌های مختلف و مقیاس‌های اشیاء را نشان می‌دهند. با پیش‌بینی انحراف‌ها نسبت به این جعبه‌های لنگر، YOLO می‌تواند به طور دقیق اشیاء با اندازه‌ها و شکل‌های مختلف را مکان‌یابی کند.
4. **هرم ویژگی‌ها**: YOLO از شبکه هرم ویژگی‌ها برای گرفتن ویژگی‌های چند مقیاسی از تصویر ورودی استفاده می‌کند. این ویژگی به YOLO امکان می‌دهد تا اشیاء را در مقیاس‌ها و رزولوشن‌های مختلف شناسایی کند، و عملکرد آن را بر روی اشیاء با اندازه‌های مختلف بهبود می‌بخشد.
5. **چندکاربردی**: YOLO یک الگوریتم چندکاربردی است که می‌تواند برای وظایف مختلفی مانند تشخیص عمومی اشیاء، تشخیص عابر پیاده، تشخیص وسایل نقلیه و بیشتر استفاده شود. قابلیت‌های زمان واقعی آن باعث می‌شود که برای کاربردهای مختلف در بینایی کامپیوتر مناسب باشد.

در کل، YOLO یک الگوریتم قوی و کارآمد برای تشخیص اشیاء است که عملکرد زمان واقعی و دقت بالایی ارائه می‌دهد، که آن را برای تحقیقات و صنعت در زمینه‌های مختلف بینایی کامپیوتر به طور گسترده‌ای استفاده می‌کند.


# سنترنت

CenterNet یک معماری تشخیص اشیاء است که بر شناسایی مراکز اشیاء و به طور همزمان تخمین جعبه‌های محصور و دسته‌بندی اشیاء تمرکز دارد. برخلاف روش‌های سنتی تشخیص اشیاء که از رویکردهای مبتنی بر لنگر یا بدون لنگر استفاده می‌کنند، CenterNet به طور مستقیم مراکز اشیاء را پیش‌بینی کرده و جعبه‌های محصور مربوطه را بازمی‌گرداند.

اجزای کلیدی CenterNet شامل موارد زیر است:

1. **تخمین مرکز شیء**: CenterNet مرکز هر شیء در تصویر را پیش‌بینی می‌کند. این کار با بازگرداندن مختصات مرکز شیء مستقیماً از خروجی شبکه انجام می‌شود.
2. **بازگرداندن جعبه محصور**: پس از شناسایی مراکز اشیاء، CenterNet جعبه‌های محصور اطراف این مراکز را بازمی‌گرداند. این شبکه عرض، ارتفاع و جهت (در صورت وجود) هر جعبه محصور را نسبت به مراکز شناسایی شده پیش‌بینی می‌کند.
3. **طبقه‌بندی دسته‌بندی شیء**: علاوه بر پیش‌بینی مراکز اشیاء و جعبه‌های محصور، CenterNet نیز طبقه‌بندی دسته‌بندی اشیاء را انجام می‌دهد. این شبکه به هر شیء شناسایی شده یک امتیاز احتمالی اختصاص می‌دهد که نشان‌دهنده احتمال تعلق آن به یک دسته خاص است.
4. **شبکه پشتیبانی**: CenterNet معمولاً از یک شبکه عصبی پیچشی (CNN) به عنوان شبکه پشتیبانی برای استخراج ویژگی‌ها استفاده می‌کند. انتخاب‌های معمول برای شبکه پشتیبانی شامل ResNet، Hourglass یا MobileNet هستند.
5. **تابع از دست دادن**: CenterNet از ترکیبی از توابع از دست دادن بازگردانی و طبقه‌بندی برای آموزش شبکه استفاده می‌کند. تابع از دست دادن بازگردانی اختلافات بین جعبه‌های محصور پیش‌بینی شده و واقعی را جریمه می‌کند، در حالی که تابع از دست دادن طبقه‌بندی خطاهای طبقه‌بندی دسته‌بندی اشیاء را جریمه می‌کند.

CenterNet مزایای متعددی از جمله سادگی، کارایی و عملکرد قوی در وظایف تشخیص اشیاء را ارائه می‌دهد. با پیش‌بینی مستقیم مراکز اشیاء، نیاز به تولید لنگر یا مراحل پس‌پردازشی مانند سرکوب غیرحداکثری (NMS) را از بین می‌برد که منجر به سرعت‌های استنتاج سریع‌تر و دقت بهبود یافته می‌شود. CenterNet به طور موفقیت‌آمیزی در کاربردهای مختلفی از جمله تشخیص عابر پیاده، تشخیص وسایل نقلیه و تشخیص عمومی اشیاء در تصاویر و ویدئوها مورد استفاده قرار گرفته است.

تصویر بارگذاری شود

#### شبکه Hourglass:

شبکه Hourglass یک معماری شبکه عصبی پیچشی (CNN) است که برای به کارگیری ویژگی‌های چند مقیاسی به‌طور کارآمد طراحی شده است. این شبکه از مراحل تکراری رمزگذاری و رمزگشایی تشکیل شده است، که در آن شبکه به‌تدریج وضوح فضایی را کاهش داده و سپس آن را به اندازه اصلی بازنمونه‌برداری می‌کند. این ویژگی به شبکه امکان می‌دهد تا جزئیات دقیق را حفظ کرده و در عین حال اطلاعات فضایی را نیز نگه دارد.

با ترکیب CenterNet با یک شبکه Hourglass، مدل TensorFlow CenterNet با Hourglass می‌تواند به طور موثر ویژگی‌های چند مقیاسی را به دست آورد و اشیاء را به‌دقت در تصاویر محلی‌سازی کند. شبکه Hourglass قابلیت شبکه را در گرفتن الگوها و جزئیات پیچیده بهبود می‌بخشد و به بهبود عملکرد در وظایف تشخیص اشیاء منجر می‌شود.

این مدل به‌ویژه برای کاربردهایی که دقت بالا مورد نیاز است، مناسب است، مانند تشخیص دقیق اشیاء، تحلیل تصاویر پزشکی، و تحلیل تصاویر ماهواره‌ای. ترکیب CenterNet با شبکه Hourglass تعادل خوبی بین دقت و کارایی ارائه می‌دهد، که آن را برای طیف گسترده‌ای از وظایف بینایی کامپیوتر مناسب می‌کند.

#### شبکه ResNet101:

ResNet101 یک معماری شبکه عصبی پیچشی (CNN) عمیق است که به خانواده ResNet تعلق دارد. این شبکه از 101 لایه تشکیل شده و به دلیل اثربخشی در آموزش شبکه‌های عصبی بسیار عمیق معروف است. ResNet101 شامل اتصالات باقیمانده یا اتصالات پرشی است که به شبکه امکان می‌دهد تا نگاشت‌های باقیمانده را بیاموزد و آموزش شبکه‌های عمیق‌تر را بدون ناپدید شدن گرادیان‌ها یا کاهش عملکرد آسان‌تر می‌کند.

با استفاده از ResNet101 به عنوان شبکه پشتیبانی برای استخراج ویژگی‌ها در مدل TensorFlow CenterNet، مدل می‌تواند از ویژگی‌های غنی و بیانی که توسط ResNet101 آموخته شده‌اند، بهره‌برداری کند تا دقت تشخیص اشیاء را بهبود بخشد. ResNet101 قادر به گرفتن الگوها و جزئیات پیچیده در تصاویر ورودی است که می‌تواند برای تشخیص اشیاء با مقیاس‌ها، جهت‌گیری‌ها و ظاهرهای مختلف مفید باشد.

ترکیب CenterNet با شبکه پشتیبانی ResNet101 به‌ویژه برای وظایف پرتقاضای تشخیص اشیاء که دقت بالا نیاز دارند، مناسب است. این ترکیب تعادل خوبی بین دقت و کارایی محاسباتی فراهم می‌کند و آن را برای استفاده در برنامه‌های دنیای واقعی مانند رانندگی خودران، نظارت و رباتیک مناسب می‌کند.


# افیشنت نت

EfficientNet یک خانواده از معماری‌های شبکه عصبی پیچشی (CNN) است که برای دستیابی به عملکرد پیشرفته با پارامترها و محاسبات به‌مراتب کمتر نسبت به مدل‌های قبلی طراحی شده‌اند. مدل‌های EfficientNet بر اساس روشی به نام مقیاس‌بندی ترکیبی توسعه یافته‌اند که به‌طور یکنواخت عمق، عرض و وضوح شبکه را مقیاس‌بندی می‌کند تا تعادل بهینه‌ای بین اندازه مدل و دقت پیدا کند.

ویژگی‌های کلیدی EfficientNet شامل موارد زیر است:

1. **مقیاس‌بندی ترکیبی**: EfficientNet از یک روش مقیاس‌بندی ترکیبی استفاده می‌کند تا عمق، عرض و وضوح شبکه را به‌طور همزمان مقیاس‌بندی کند. این روش به مدل امکان می‌دهد تا با استفاده بهینه از منابع محاسباتی، عملکرد بهتری داشته باشد.
2. **بلوک‌های ساختاری کارآمد**: EfficientNet از بلوک‌های ساختاری کارآمد مانند پیچش‌های جداشونده عمقی، بلوک‌های باقیمانده وارونه و بلوک‌های فشرده‌سازی و تحریک استفاده می‌کند تا پیچیدگی محاسباتی را کاهش دهد و در عین حال دقت بالایی را حفظ کند.
3. **توازن بین اندازه مدل و عملکرد**: EfficientNet طیفی از مدل‌ها را ارائه می‌دهد که از نسخه‌های کوچکتر و کارآمدتر (مانند EfficientNet-B0) تا نسخه‌های بزرگتر و قوی‌تر (مانند EfficientNet-B7) متغیر است. کاربران می‌توانند بر اساس نیازهای خاص خود به دقت و منابع محاسباتی، مدل مناسب را انتخاب کنند.
4. **یادگیری انتقالی**: مدل‌های EfficientNet بر روی مجموعه داده‌های بزرگ مانند ImageNet پیش‌آموزش دیده‌اند، که این امکان را فراهم می‌کند تا برای وظایف پایین‌دستی با مقدار محدودی از داده‌های برچسب‌خورده، یادگیری انتقالی مؤثری انجام شود.
5. **انعطاف‌پذیری کاربرد**: EfficientNet می‌تواند برای طیف وسیعی از وظایف بینایی کامپیوتر، از جمله طبقه‌بندی تصویر، تشخیص اشیاء، تقسیم‌بندی و موارد دیگر، به‌کار گرفته شود. کارایی و انعطاف‌پذیری آن، این مدل را برای هر دو کاربرد تحقیقاتی و عملی مناسب می‌سازد.

در مجموع، EfficientNet به دلیل عملکرد چشمگیر، کارایی و مقیاس‌پذیری خود به یک انتخاب محبوب برای وظایف مختلف بینایی کامپیوتر تبدیل شده است. این مدل در حالی که به پارامترها و محاسبات کمتری نیاز دارد، نتایج پیشرفته‌ای بر روی مجموعه داده‌های معیار به دست آورده است.

تصویر بارگذاری شود

EfficientNet-B0 تا B7 یک خانواده از مدل‌های شبکه عصبی پیچشی هستند که هر کدام برای توازن بهینه بین اندازه مدل، کارایی محاسباتی، و دقت طراحی شده‌اند. این مدل‌ها با استفاده از روش مقیاس‌بندی ترکیبی به‌طور یکنواخت عمق، عرض، و وضوح شبکه را تنظیم می‌کنند تا بهترین عملکرد را با منابع محاسباتی موجود ارائه دهند.

#### توضیحات هر نسخه از EfficientNet:

* **EfficientNet-B0**: کوچکترین و کارآمدترین نسخه از خانواده EfficientNet است. این مدل پارامترها و محاسبات کمتری نسبت به مدل‌های بزرگتر دارد ولی همچنان عملکرد رقابتی ارائه می‌دهد. EfficientNet-B0 برای سناریوهایی مناسب است که منابع محاسباتی محدود هستند.
* **EfficientNet-B1 تا B6**: این مدل‌ها به تدریج در اندازه و پیچیدگی افزایش می‌یابند، با پارامترها و محاسبات بیشتر نسبت به EfficientNet-B0. با افزایش شاخص مدل از B1 به B6، عمق، عرض و وضوح شبکه بر اساس روش مقیاس‌بندی ترکیبی افزایش می‌یابد که منجر به بهبود عملکرد می‌شود.
* **EfficientNet-B7**: بزرگترین و قدرتمندترین نسخه از خانواده EfficientNet است. این مدل بیشترین تعداد پارامترها و محاسبات را دارد و برای کاربردهایی مناسب است که دقت بالا مورد نیاز است و منابع محاسباتی کمتر محدود هستند. EfficientNet-B7 عملکرد پیشرفته‌ای را بر روی مجموعه داده‌های معیار ارائه می‌دهد.

#### کاربرد و مزایا:

* **پیش‌آموزش روی مجموعه داده‌های بزرگ**: مدل‌های EfficientNet بر روی مجموعه داده‌های بزرگ مانند ImageNet پیش‌آموزش دیده‌اند و می‌توانند برای وظایف پایین‌دستی مانند طبقه‌بندی تصویر، تشخیص اشیاء، تقسیم‌بندی معنایی و بیشتر، تنظیم مجدد یا به‌عنوان استخراج‌کننده ویژگی استفاده شوند.
* **تعادل بین اندازه مدل، کارایی و دقت**: EfficientNet‌ها تعادل خوبی بین اندازه مدل، کارایی محاسباتی و دقت ارائه می‌دهند، که آنها را برای تحقیقات و صنعت در طیف وسیعی از کاربردهای بینایی کامپیوتر مناسب می‌سازد.

#### انتخاب مدل مناسب:

کاربران می‌توانند بر اساس نیازهای خاص خود به دقت، منابع محاسباتی و حوزه کاربرد، نسخه مناسب EfficientNet را انتخاب کنند:

* **EfficientNet-B0**: برای سناریوهایی با منابع محدود.
* **EfficientNet-B1 تا B6**: برای مواردی که به تعادل بین دقت و کارایی نیاز دارند.
* **EfficientNet-B7**: برای کاربردهایی که دقت بالا و منابع محاسباتی کافی موجود است.

به این ترتیب، خانواده EfficientNet گزینه‌ای انعطاف‌پذیر و کارآمد برای طیف گسترده‌ای از وظایف بینایی کامپیوتر فراهم می‌کند.


# R-CNN سریعتر

Faster R-CNN یک الگوریتم تشخیص اشیاء است که بر اساس شبکه پیشنهاد ناحیه (RPN) و چارچوب شبکه عصبی پیچشی (CNN) ساخته شده است. این الگوریتم به دلیل دقت و کارایی در تشخیص اشیاء در تصاویر به خوبی شناخته شده است.

#### شرح جزئیات Faster R-CNN:

1. **شبکه پیشنهاد ناحیه (RPN)**:
   * Faster R-CNN یک RPN معرفی می‌کند که یک شبکه کاملاً پیچشی است و ناحیه‌های پیشنهادی (bounding boxes) کاندیدا برای اشیاء (ناحیه‌های مورد علاقه یا RoIs) در یک تصویر را پیشنهاد می‌دهد.
   * RPN روی نقشه‌های ویژگی استخراج شده از تصویر ورودی با استفاده از یک شبکه پشتیبان (مانند ResNet) عمل می‌کند و مختصات جعبه‌های محصور و نمرات شیء را برای مکان‌های بالقوه اشیاء پیش‌بینی می‌کند.
2. **استخراج ویژگی با استفاده از شبکه پشتیبان**:
   * Faster R-CNN معمولاً از یک CNN پیش‌آموزش دیده (مانند ResNet یا VGG) به عنوان شبکه پشتیبان برای استخراج ویژگی‌ها استفاده می‌کند.
   * این شبکه پشتیبان تصویر ورودی را پردازش کرده و نمایش‌های ویژگی سطح بالا را استخراج می‌کند که توسط هر دو RPN و شبکه تشخیص شیء بعدی استفاده می‌شود.
3. **Pooling ناحیه مورد علاقه (RoI)**:
   * پس از اینکه جعبه‌های محصور کاندیدا توسط RPN پیشنهاد می‌شوند، Faster R-CNN عملیات pooling ناحیه مورد علاقه (RoI) یا تنظیم RoI را انجام می‌دهد تا نقشه‌های ویژگی با اندازه ثابت را برای هر RoI از نقشه‌های ویژگی پشتیبان استخراج کند.
   * این ویژگی‌های RoI سپس به یک لایه کاملاً متصل برای طبقه‌بندی و بازگردانی جعبه‌های محصور بعدی تغذیه می‌شوند.
4. **سرهای طبقه‌بندی و بازگردانی**:
   * Faster R-CNN از سرهای جداگانه برای طبقه‌بندی اشیاء و بازگردانی جعبه‌های محصور استفاده می‌کند.
   * سر طبقه‌بندی احتمال هر RoI برای تعلق به یک کلاس خاص را پیش‌بینی می‌کند، در حالی که سر بازگردانی مختصات جعبه‌های محصور هر RoI را اصلاح می‌کند.
5. **تابع از دست دادن**:
   * Faster R-CNN با استفاده از یک تابع از دست دادن چند وظیفه‌ای آموزش داده می‌شود که شامل از دست دادن طبقه‌بندی (مثلاً از دست دادن آنتروپی متقاطع) و از دست دادن بازگردانی (مثلاً از دست دادن L1 نرم) است.
   * مدل به صورت انتها به انتها با استفاده از پس‌انتشار آموزش داده می‌شود تا هر دو وظیفه را به‌طور مشترک بهینه‌سازی کند.

Faster R-CNN در وظایف تشخیص اشیاء به عملکرد پیشرفته‌ای دست می‌یابد و تعادلی مؤثر بین دقت و سرعت برقرار می‌کند. این الگوریتم در کاربردهای مختلفی مانند رانندگی خودران، نظارت و تحلیل تصویر، جایی که مکان‌یابی دقیق و طبقه‌بندی اشیاء ضروری است، به طور گسترده پذیرفته شده است.

تصویر بارگذاری شود

#### Inception Backbone:

شبکه‌های Inception خانواده‌ای از معماری‌های شبکه عصبی پیچشی (CNN) هستند که به دلیل کارایی و اثربخشی در وظایف تشخیص تصویر شناخته شده‌اند. شبکه Inception مورد استفاده در TensorFlow Faster R-CNN معمولاً به انواع مختلف معماری Inception (مثلاً Inception-v2، Inception-v3) اشاره دارد که بر روی مجموعه داده‌های بزرگ مانند ImageNet پیش‌آموزش دیده‌اند.

**ویژگی‌ها و مزایای Inception:**

1. **استخراج ویژگی کارآمد**: معماری Inception با استفاده از ترکیب‌های چندمقیاسی از فیلترها در هر لایه، ویژگی‌های غنی و متنوعی را استخراج می‌کند. این ویژگی‌ها برای تشخیص اشیاء با دقت بالا بسیار مفید هستند.
2. **بهینه‌سازی محاسباتی**: با استفاده از عملیات‌هایی مانند convolution‌های با اندازه‌های مختلف در یک لایه، شبکه Inception به کارایی محاسباتی بالایی دست می‌یابد و همزمان ویژگی‌های پیچیده‌ای را استخراج می‌کند.
3. **تعادل بین دقت و کارایی**: ترکیب معماری Faster R-CNN با شبکه Inception، مدل TensorFlow Faster R-CNN با Inception را به تعادلی بین دقت و کارایی می‌رساند. این ترکیب به‌ویژه برای کاربردهایی مانند رانندگی خودران، نظارت و تحلیل تصویر مناسب است.

#### ResNet101 Backbone:

شبکه ResNet101 یک معماری عمیق شبکه عصبی پیچشی است که به دلیل ساختارهای باقیمانده (residual) خود که از محو شدن گرادیان‌ها جلوگیری می‌کند، معروف است. این شبکه شامل 101 لایه است و به خوبی می‌تواند ویژگی‌های پیچیده و غنی را از تصاویر استخراج کند.

**ویژگی‌ها و مزایای ResNet101:**

1. **ویژگی‌های غنی و بیانی**: شبکه ResNet101 به دلیل عمق زیاد و استفاده از اتصالات باقیمانده، قادر به یادگیری و استخراج ویژگی‌های غنی و پیچیده از تصاویر است.
2. **پایداری در آموزش**: اتصالات باقیمانده در ResNet101 به پایداری آموزش کمک می‌کنند و امکان آموزش شبکه‌های بسیار عمیق‌تر را بدون مشکلاتی مانند محو شدن گرادیان‌ها فراهم می‌کنند.
3. **عملکرد پیشرفته**: ترکیب معماری Faster R-CNN با شبکه ResNet101، مدل TensorFlow Faster R-CNN با ResNet101 را به عملکرد پیشرفته‌ای در وظایف تشخیص اشیاء می‌رساند. این مدل می‌تواند اشیاء را به دقت تشخیص داده و طبقه‌بندی کند، که این ویژگی برای کاربردهایی مانند رانندگی خودران، نظارت و تحلیل تصویر بسیار مناسب است.

#### کاربردهای مشترک:

هر دو مدل TensorFlow Faster R-CNN با Inception و ResNet101 به دلیل کارایی و دقت بالا در کاربردهای مختلفی مانند رانندگی خودران، نظارت و تحلیل تصویر به کار می‌روند. انتخاب بین این دو بستگی به نیازهای خاص پروژه دارد:

* **Inception Backbone**: برای کاربردهایی که به تعادل بین دقت و کارایی محاسباتی نیاز دارند.
* **ResNet101 Backbone**: برای کاربردهایی که دقت بالا و استخراج ویژگی‌های پیچیده اهمیت بیشتری دارند.


# SSD

#### Single Shot Multibox Detector (SSD)

**Single Shot Multibox Detector (SSD)** یک الگوریتم تشخیص اشیاء است که در حوزه بینایی کامپیوتر به‌طور گسترده مورد استفاده قرار می‌گیرد. این الگوریتم به دلیل سادگی، کارایی و اثربخشی در وظایف تشخیص اشیاء به صورت بلادرنگ شناخته شده است.

#### ویژگی‌های کلیدی SSD:

1. **پیش‌بینی در یک مرحله (Single Pass Prediction)**:
   * SSD عملیات تشخیص اشیاء را در یک مرحله از طریق شبکه انجام می‌دهد. این ویژگی باعث می‌شود که این الگوریتم بسیار کارآمد باشد و برای کاربردهای بلادرنگ مناسب باشد.
2. **ترکیب ویژگی‌های چندمقیاسی (Multi-scale Feature Fusion)**:
   * SSD از نقشه‌های ویژگی از چندین لایه شبکه عصبی برای تشخیص اشیاء در مقیاس‌های مختلف استفاده می‌کند. این ویژگی به الگوریتم اجازه می‌دهد تا اشیاء با اندازه‌ها و نسبت‌های مختلف را به‌طور مؤثر شناسایی کند.
3. **جعبه‌های لنگر (Anchor Boxes)**:
   * SSD با استفاده از جعبه‌های لنگر با اندازه‌ها و نسبت‌های مختلف در هر مکان نقشه ویژگی، جعبه‌های محصور (bounding boxes) را پیش‌بینی می‌کند. این ویژگی به الگوریتم اجازه می‌دهد تا اشیاء با اشکال و اندازه‌های مختلف را به دقت مکان‌یابی کند.
4. **چارچوب یکپارچه (Unified Framework)**:
   * SSD همزمان وظایف مکان‌یابی اشیاء و طبقه‌بندی را انجام می‌دهد و نیاز به مراحل جداگانه تشخیص و طبقه‌بندی را از بین می‌برد.

#### مزایا و کاربردها:

* **کاربردهای گسترده**: SSD به دلیل سادگی و کارایی در کاربردهای مختلفی مانند رانندگی خودران، نظارت و رباتیک به‌طور گسترده پذیرفته شده است.
* **تشخیص اشیاء بلادرنگ**: به دلیل کارایی بالا و توانایی اجرای در یک مرحله، SSD انتخاب محبوبی برای وظایف تشخیص اشیاء به صورت بلادرنگ است.

#### عملکرد SSD:

SSD با استفاده از مجموعه‌ای از فیلترهای پیچشی، اشیاء را در سطوح مختلف دانه‌بندی تشخیص می‌دهد. این فرآیند باعث می‌شود که SSD بتواند اشیاء را در یک گذر از شبکه تشخیص دهد، که به بهره‌وری بالا و قابلیت استفاده در زمان واقعی منجر می‌شود. همچنین، بهره‌گیری از ویژگی‌های چندمقیاسی و جعبه‌های لنگر کمک می‌کند تا SSD بتواند اشیاء با اندازه‌ها و نسبت‌های مختلف را با دقت بالا مکان‌یابی کند.

SSD به عنوان یک الگوریتم تشخیص اشیاء، با ارائه چارچوبی یکپارچه که عملیات مکان‌یابی و طبقه‌بندی را همزمان انجام می‌دهد، توانسته است تعادل خوبی بین دقت و کارایی ایجاد کند و این ویژگی‌ها آن را برای کاربردهای بلادرنگ و موثر در حوزه بینایی کامپیوتر مناسب ساخته است.

تصویر بارگذاری شود

#### MobileNet Backbone

**MobileNet** یک معماری شبکه عصبی پیچشی سبک است که برای برنامه‌های بینایی موبایل و تعبیه شده طراحی شده است. MobileNet از convolutions‌های جداشدنی عمقی (depthwise separable convolutions) استفاده می‌کند تا پیچیدگی محاسباتی را کاهش دهد و در عین حال دقت بالایی را حفظ کند. این شبکه به دلیل کارایی بالا، در وظایف مختلف بینایی کامپیوتر از جمله تشخیص اشیاء به‌طور گسترده پذیرفته شده است.

#### ویژگی‌ها و مزایای MobileNet:

1. **کارایی بالا**: استفاده از convolutions‌های جداشدنی عمقی باعث کاهش پیچیدگی محاسباتی و افزایش سرعت اجرا می‌شود.
2. **حجم کم مدل**: MobileNet حجم کمی دارد و برای دستگاه‌هایی با منابع محدود مانند تلفن‌های همراه، پهپادها و سیستم‌های تعبیه شده مناسب است.
3. **تعادل بین سرعت و دقت**: ترکیب SSD با MobileNet به مدل TensorFlow SSD با MobileNet تعادل بین سرعت و دقت را می‌دهد، که برای تشخیص اشیاء به صورت بلادرنگ در دستگاه‌های محدود به منابع مناسب است.

#### کاربردها:

این مدل به ویژه در سناریوهایی که نیاز به پردازش بلادرنگ دارند، مانند نظارت، وسایل نقلیه خودران و برنامه‌های واقعیت افزوده مفید است. کارایی آن باعث می‌شود که برای استقرار در دستگاه‌های لبه‌ای با منابع محاسباتی محدود مناسب باشد.

#### ResNet152 Backbone

**ResNet152** یک معماری شبکه عصبی پیچشی عمیق است که به خانواده ResNet تعلق دارد. این شبکه دارای 152 لایه است و از اتصالات باقیمانده برای تسهیل آموزش شبکه‌های بسیار عمیق استفاده می‌کند. ResNet152 عملکرد چشمگیری در وظایف مختلف بینایی کامپیوتر از جمله طبقه‌بندی تصویر، تشخیص اشیاء و تقسیم‌بندی معنایی نشان داده است.

#### ویژگی‌ها و مزایای ResNet152:

1. **عمق زیاد**: ResNet152 به دلیل تعداد لایه‌های زیاد و اتصالات باقیمانده، قادر به یادگیری ویژگی‌های پیچیده و غنی از تصاویر است.
2. **عملکرد بالا**: این شبکه قادر است الگوها و جزئیات دقیق را در تصاویر ورودی شناسایی کند که برای تشخیص اشیاء با مقیاس‌ها، جهت‌ها و ظاهرهای مختلف مفید است.
3. **دقت بالا**: ترکیب SSD با ResNet152 به مدل TensorFlow SSD با ResNet152 عملکرد بسیار دقیقی در وظایف تشخیص اشیاء می‌دهد که برای تشخیص اشیاء با دقت بالا مناسب است.

#### کاربردها:

این ترکیب برای وظایف تشخیص اشیاء با دقت بالا، مانند شناسایی جزئیات دقیق، تحلیل تصاویر پزشکی و تحلیل تصاویر ماهواره‌ای مناسب است. با این حال، استفاده از یک شبکه پشتیبان عمیق‌تر مانند ResNet152 ممکن است پیچیدگی محاسباتی و نیازهای حافظه مدل را افزایش دهد و به طور بالقوه سرعت استنتاج و قابلیت استقرار را تحت تاثیر قرار دهد.

#### MobileNet و شبکه هرم ویژگی (Feature Pyramid Network - FPN)

**شبکه هرم ویژگی (FPN)** یک معماری استخراج ویژگی است که برای به‌دست آوردن ویژگی‌های چندمقیاسی از تصاویر ورودی طراحی شده است. FPN این کار را با ساخت یک هرم ویژگی با سطوح مختلف وضوح و اطلاعات معنایی انجام می‌دهد. این شبکه قابلیت شبکه پشتیبان را برای شناسایی اشیاء در مقیاس‌های مختلف افزایش می‌دهد و عملکرد کلی مدل تشخیص اشیاء را بهبود می‌بخشد.

#### ویژگی‌ها و مزایای ترکیب MobileNet و FPN:

1. **نمایندگی چندمقیاسی**: FPN ویژگی‌های چندمقیاسی را فراهم می‌کند که به مدل اجازه می‌دهد اشیاء را در مقیاس‌های مختلف تشخیص دهد.
2. **کارایی و دقت**: ترکیب SSD با MobileNet و FPN به مدل TensorFlow SSD با MobileNetFPN تعادل بین سرعت، کارایی و دقت می‌دهد.

#### کاربردها:

این مدل به ویژه برای وظایف تشخیص اشیاء به صورت بلادرنگ در دستگاه‌های محدود به منابع مناسب است. این مدل تعادلی خوب بین اندازه مدل، سرعت استنتاج و دقت تشخیص ارائه می‌دهد، که آن را برای طیف وسیعی از برنامه‌های بینایی کامپیوتر مناسب می‌سازد.


# DETR


# DETECTRON2 FASTER RCNN


# تست سلامت دیتاست

برای انجام یک "بررسی سلامت داده‌ها" به منظور اطمینان از کیفیت و مناسب بودن داده‌ها برای آموزش مدل‌های یادگیری ماشین، می‌توان از مراحلی مشابه آنچه در بالا توضیح داده شد استفاده کرد. در ادامه، یک راهنمای مرحله به مرحله به زبان فارسی برای تولید نقشه حرارتی از همپوشانی حاشیه‌نویسی‌ها ارائه شده است:

#### راهنمای مرحله به مرحله برای تولید نقشه حرارتی همپوشانی حاشیه‌نویسی‌ها

**1. آماده‌سازی داده‌ها**

تمام حاشیه‌نویسی‌های مجموعه داده را جمع‌آوری کنید. این شامل جعبه‌های محدودکننده، چندضلعی‌ها یا ماسک‌های قطعه‌بندی به همراه متاداده‌های مرتبط مانند نام فایل‌های تصویر یا شناسه‌های حاشیه‌نویسی است.

```python
import pandas as pd

# مثال: بارگذاری حاشیه‌نویسی‌ها در یک DataFrame
annotations = pd.read_csv('annotations.csv')
```

**2. محاسبه مناطق همپوشانی**

برای هر تصویر، مناطق همپوشانی بین حاشیه‌نویسی‌ها را محاسبه کنید. اگر از جعبه‌های محدودکننده استفاده می‌کنید، این شامل بررسی تقاطع بین جعبه‌ها می‌شود.

```python
import numpy as np

def compute_iou(box1, box2):
    # محاسبه تقاطع-به-اتحاد برای دو جعبه محدودکننده
    x1, y1, w1, h1 = box1
    x2, y2, w2, h2 = box2

    xi1 = max(x1, x2)
    yi1 = max(y1, y2)
    xi2 = min(x1 + w1, x2 + w2)
    yi2 = min(y1 + h1, y2 + h2)
    inter_area = max(0, xi2 - xi1) * max(0, yi2 - yi1)

    box1_area = w1 * h1
    box2_area = w2 * h2
    union_area = box1_area + box2_area - inter_area

    iou = inter_area / union_area
    return iou

# مثال: محاسبه IOU برای همه حاشیه‌نویسی‌های یک تصویر
image_annotations = annotations[annotations['image_id'] == 'image_1']
overlaps = np.zeros((len(image_annotations), len(image_annotations)))

for i in range(len(image_annotations)):
    for j in range(i + 1, len(image_annotations)):
        box1 = image_annotations.iloc[i][['x', 'y', 'width', 'height']].values
        box2 = image_annotations.iloc[j][['x', 'y', 'width', 'height']].values
        overlaps[i, j] = compute_iou(box1, box2)
        overlaps[j, i] = overlaps[i, j]
```

**3. جمع‌آوری همپوشانی‌ها**

مناطق همپوشانی را جمع‌آوری کنید تا آمارهایی مانند تعداد همپوشانی‌ها را محاسبه کنید.

```python
# خلاصه‌سازی تعداد همپوشانی‌ها
overlap_counts = np.sum(overlaps > 0.5, axis=0)  # مثال: آستانه 0.5 برای همپوشانی
```

**4. تولید نقشه حرارتی**

یک نقشه حرارتی تولید کنید تا همپوشانی‌های جمع‌آوری شده را نشان دهید.

```python
import matplotlib.pyplot as plt
import seaborn as sns

# مثال: تولید نقشه حرارتی
plt.figure(figsize=(10, 8))
sns.heatmap(overlaps, annot=True, cmap='coolwarm', cbar=True)
plt.title('نقشه حرارتی همپوشانی حاشیه‌نویسی‌ها')
plt.xlabel('شاخص حاشیه‌نویسی')
plt.ylabel('شاخص حاشیه‌نویسی')
plt.show()
```

**5. مصورسازی**

نقشه حرارتی را مصورسازی کنید تا الگوهای همپوشانی یا توافق در سراسر مجموعه داده‌ها شناسایی شود.

**6. تفسیر و تحلیل**

نقشه حرارتی را تفسیر کنید تا کیفیت و ثبات حاشیه‌نویسی‌ها را ارزیابی کنید. به دنبال مناطق با همپوشانی بالا یا پایین باشید و در صورت لزوم بررسی‌های بیشتری انجام دهید.

#### مثال از اسکریپت بررسی سلامت داده‌ها

در اینجا یک مثال از اسکریپتی که مراحل بالا را یکپارچه می‌کند ارائه شده است:

```python
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
import seaborn as sns

def compute_iou(box1, box2):
    x1, y1, w1, h1 = box1
    x2, y2, w2, h2 = box2

    xi1 = max(x1, x2)
    yi1 = max(y1, y2)
    xi2 = min(x1 + w1, x2 + w2)
    yi2 = min(y1 + h1, y2 + h2)
    inter_area = max(0, xi2 - xi1) * max(0, yi2 - yi1)

    box1_area = w1 * h1
    box2_area = w2 * h2
    union_area = box1_area + box2_area - inter_area

    iou = inter_area / union_area
    return iou

# بارگذاری حاشیه‌نویسی‌ها
annotations = pd.read_csv('annotations.csv')

# مقداردهی اولیه ماتریس همپوشانی
num_annotations = len(annotations)
overlaps = np.zeros((num_annotations, num_annotations))

# محاسبه همپوشانی‌ها
for i in range(num_annotations):
    for j in range(i + 1, num_annotations):
        box1 = annotations.iloc[i][['x', 'y', 'width', 'height']].values
        box2 = annotations.iloc[j][['x', 'y', 'width', 'height']].values
        overlaps[i, j] = compute_iou(box1, box2)
        overlaps[j, i] = overlaps[i, j]

# تولید نقشه حرارتی
plt.figure(figsize=(10, 8))
sns.heatmap(overlaps, annot=False, cmap='coolwarm', cbar=True)
plt.title('نقشه حرارتی همپوشانی حاشیه‌نویسی‌ها')
plt.xlabel('شاخص حاشیه‌نویسی')
plt.ylabel('شاخص حاشیه‌نویسی')
plt.show()

# جمع‌آوری آمار همپوشانی
overlap_counts = np.sum(overlaps > 0.5, axis=0)  # تنظیم آستانه بر حسب نیاز
print('تعداد همپوشانی‌ها:', overlap_counts)
```

#### نتیجه‌گیری

این اسکریپت یک چارچوب پایه برای انجام بررسی سلامت مجموعه داده‌ها از طریق مصورسازی همپوشانی حاشیه‌نویسی‌ها فراهم می‌کند. آستانه همپوشانی را تنظیم کرده و محاسبه همپوشانی را بر اساس ویژگی‌های خاص حاشیه‌نویسی‌ها و نیازهای کاربردی خود اصلاح کنید.

&#x20;گیف بارگذاری شود


# توزیع اندازه نسبی

#### دستورالعمل برای تحلیل و مصورسازی توزیع اندازه‌های حاشیه‌نویسی نسبت به تصویر

برای ایجاد نموداری که توزیع حاشیه‌نویسی‌ها را بر اساس اندازه نسبی آن‌ها نسبت به تصویر نشان دهد، و همچنین اطلاعات اضافی درباره اندازه متوسط تصاویر حاوی حاشیه‌نویسی‌ها در هر دسته اندازه در مقایسه با اندازه متوسط تصویر مجموعه داده‌ها ارائه دهد، می‌توانید مراحل زیر را دنبال کنید:

**1. محاسبه اندازه حاشیه‌نویسی**

اندازه هر حاشیه‌نویسی را نسبت به تصویر مربوطه محاسبه کنید. این کار را می‌توان با محاسبه نسبت مساحت یا ابعاد جعبه محدودکننده انجام داد.

**2. گروه‌بندی حاشیه‌نویسی‌ها بر اساس دسته‌بندی اندازه**

حاشیه‌نویسی‌ها را بر اساس اندازه نسبی‌شان به تصویر در دسته‌های اندازه مختلف گروه‌بندی کنید. به عنوان مثال، می‌توانید حاشیه‌نویسی‌ها را به صورت کوچک، متوسط و بزرگ بر اساس آستانه‌های تعریف شده دسته‌بندی کنید.

**3. محاسبه اندازه متوسط تصویر**

اندازه متوسط تصاویر حاوی حاشیه‌نویسی‌ها را برای هر دسته اندازه محاسبه کنید. این کار را می‌توان با میانگین‌گیری ابعاد (مثلاً عرض و ارتفاع) تصاویر با حاشیه‌نویسی‌ها در هر دسته اندازه انجام داد.

**4. مصورسازی توزیع**

یک نمودار (مثلاً نمودار ستونی) برای مصورسازی توزیع حاشیه‌نویسی‌ها در دسته‌های اندازه ایجاد کنید. هر ستون نماینده یک دسته اندازه است و ارتفاع ستون درصد حاشیه‌نویسی‌ها در آن دسته نسبت به کل تعداد حاشیه‌نویسی‌ها را نشان می‌دهد.

**5. افزودن اطلاعات اضافی**

اطلاعات اضافی را به نمودار اضافه کنید. به عنوان مثال، می‌توانید ستون‌های آبی را برای نشان دادن اندازه متوسط تصاویر حاوی حاشیه‌نویسی‌ها در هر دسته اندازه نسبت به اندازه متوسط تصویر مجموعه داده‌ها اضافه کنید. همچنین می‌توانید ستون‌های سیان را برای نشان دادن درصد تصاویر حاوی حاشیه‌نویسی‌ها در هر دسته اندازه اضافه کنید.

#### کد پایتون برای اجرای مراحل فوق

در اینجا یک نمونه کد پایتون برای انجام این تحلیل و مصورسازی ارائه شده است:

```python
import pandas as pd
import numpy as np
import matplotlib.pyplot as plt

# بارگذاری حاشیه‌نویسی‌ها و تصاویر
annotations = pd.read_csv('annotations.csv')  # فرض بر این است که حاوی ستون‌های 'image_id', 'x', 'y', 'width', 'height' است
images = pd.read_csv('images.csv')  # فرض بر این است که حاوی ستون‌های 'image_id', 'width', 'height' است

# محاسبه اندازه نسبی حاشیه‌نویسی‌ها
annotations = annotations.merge(images, on='image_id')
annotations['relative_area'] = (annotations['width_x'] * annotations['height_x']) / (annotations['width_y'] * annotations['height_y'])

# تعریف آستانه‌ها برای دسته‌بندی اندازه‌ها
small_threshold = 0.01
large_threshold = 0.1

annotations['size_category'] = pd.cut(annotations['relative_area'],
                                      bins=[0, small_threshold, large_threshold, np.inf],
                                      labels=['Small', 'Medium', 'Large'])

# محاسبه توزیع حاشیه‌نویسی‌ها در دسته‌های اندازه
size_distribution = annotations['size_category'].value_counts(normalize=True) * 100

# محاسبه اندازه متوسط تصاویر در هر دسته اندازه
average_image_size_by_category = annotations.groupby('size_category').apply(lambda x: (x['width_y'] * x['height_y']).mean())

# اندازه متوسط تصویر مجموعه داده‌ها
average_dataset_image_size = (images['width'] * images['height']).mean()

# مصورسازی توزیع حاشیه‌نویسی‌ها
fig, ax1 = plt.subplots(figsize=(10, 6))

color = 'tab:blue'
ax1.set_xlabel('Size Category')
ax1.set_ylabel('Percentage of Annotations', color=color)
ax1.bar(size_distribution.index, size_distribution.values, color=color, alpha=0.6)
ax1.tick_params(axis='y', labelcolor=color)

# اضافه کردن اندازه متوسط تصاویر به نمودار
ax2 = ax1.twinx()  
color = 'tab:red'
ax2.set_ylabel('Average Image Size', color=color)  
ax2.bar(average_image_size_by_category.index, average_image_size_by_category.values, color=color, alpha=0.4)
ax2.axhline(y=average_dataset_image_size, color='cyan', linestyle='--', label='Average Dataset Image Size')
ax2.tick_params(axis='y', labelcolor=color)

fig.tight_layout()  
plt.title('Distribution of Annotations by Size Category and Average Image Sizes')
plt.legend(loc='upper right')
plt.show()
```

#### توضیحات کد

* **بارگذاری داده‌ها:** حاشیه‌نویسی‌ها و تصاویر از فایل‌های CSV بارگذاری می‌شوند.
* **محاسبه اندازه نسبی:** اندازه نسبی هر حاشیه‌نویسی نسبت به تصویر مربوطه محاسبه می‌شود.
* **دسته‌بندی اندازه‌ها:** حاشیه‌نویسی‌ها بر اساس آستانه‌های تعریف شده به دسته‌های کوچک، متوسط و بزرگ تقسیم می‌شوند.
* **محاسبه توزیع و اندازه متوسط:** توزیع حاشیه‌نویسی‌ها در دسته‌های مختلف محاسبه شده و اندازه متوسط تصاویر در هر دسته به دست می‌آید.
* **مصورسازی:** توزیع حاشیه‌نویسی‌ها و اندازه متوسط تصاویر در هر دسته به صورت نمودار ستونی نمایش داده می‌شود.

این کد به شما کمک می‌کند تا تحلیل دقیقی از توزیع اندازه‌های حاشیه‌نویسی‌ها و ارتباط آن‌ها با اندازه تصاویر داشته باشید.

گیف بارگذاری شود


# رسم نمودار توزیع

#### ایجاد نمودار ساده برای نمایش توزیع حاشیه‌نویسی‌ها بر اساس اندازه نسبی به تصویر

برای ایجاد یک نمودار ساده که توزیع حاشیه‌نویسی‌ها را بر اساس اندازه نسبی آن‌ها نسبت به تصویر نشان دهد، می‌توانید از یک هیستوگرام یا نمودار ستونی استفاده کنید. در اینجا مراحل انجام این کار آمده است:

**1. محاسبه اندازه حاشیه‌نویسی‌ها**

اندازه هر حاشیه‌نویسی را نسبت به تصویر مربوطه محاسبه کنید. این اندازه می‌تواند بر اساس مساحت، ابعاد جعبه محدودکننده یا هر معیار مرتبط دیگری محاسبه شود.

**2. رسم هیستوگرام یا نمودار ستونی**

یک هیستوگرام یا نمودار ستونی ایجاد کنید تا توزیع اندازه‌های حاشیه‌نویسی‌ها را نمایش دهید. هر ستون نماینده یک محدوده اندازه حاشیه‌نویسی است و ارتفاع ستون نشان‌دهنده تعداد حاشیه‌نویسی‌ها در آن محدوده اندازه است.

**3. افزودن برچسب‌ها و عنوان‌ها**

محورهای نمودار را برچسب‌گذاری کنید و یک عنوان برای نمودار ارائه دهید تا مشخص شود نمودار چه چیزی را نمایش می‌دهد.

#### کد پایتون برای ایجاد نمودار توزیع

در اینجا یک نمونه کد پایتون برای ایجاد نمودار توزیع آورده شده است:

```python
import matplotlib.pyplot as plt

# فرض کنید شما داده‌های مربوط به اندازه حاشیه‌نویسی‌ها را دارید
annotation_sizes = [0.1, 0.2, 0.05, 0.3, 0.15, 0.25, 0.4, 0.05, 0.35, 0.2]

# رسم هیستوگرام
plt.hist(annotation_sizes, bins=10, edgecolor='black')
plt.xlabel('اندازه نسبی حاشیه‌نویسی‌ها به تصویر')
plt.ylabel('تعداد حاشیه‌نویسی‌ها')
plt.title('توزیع اندازه حاشیه‌نویسی‌ها نسبت به تصویر')
plt.show()
```

این کد یک هیستوگرام از اندازه‌های حاشیه‌نویسی‌ها نسبت به تصویر رسم می‌کند، که نشان‌دهنده توزیع این اندازه‌ها در داده‌های شماست. شما می‌توانید تعداد بازه‌ها (bins) را بر اساس نیاز خود تنظیم کنید.

گیف بارگذاری شود


# تنسوربرد

TensorBoard ابزارها و قابلیت‌های لازم برای تجسم و پیگیری آزمایش‌های یادگیری ماشین را فراهم می‌کند:

* پیگیری و تجسم معیارهایی مانند از دست دادن (loss) و دقت (accuracy)
* تجسم نمودار مدل (عملیات و لایه‌ها)
* مشاهده هیستوگرام‌های وزن‌ها، بایاس‌ها یا دیگر تنسورها در طول زمان
* نمایش تعبیه‌ها (embeddings) در فضای با ابعاد پایین‌تر
* نمایش داده‌های تصویری، متنی و صوتی
* پروفایل‌سازی برنامه‌های TensorFlow
* و بسیاری قابلیت‌های دیگر

گیف بارگذاری شود<br>


# ابرمقادیر

دسته ها

در آموزش شبکه های عصبی، اصطلاح "دسته ها" به تعداد نمونه های داده ای اشاره دارد که به طور همزمان در شبکه عصبی قرار می گیرند و در یک مرحله از فرآیند آموزش پردازش می شوند. اندازه دسته یک پارامتر مهم در آموزش شبکه عصبی است و می تواند به طور مستقیم بر کیفیت و سرعت آموزش تأثیر بگذارد. برخی از اثرات اندازه دسته عبارتند از: آموزش سریع تر: استفاده از اندازه دسته بزرگتر می تواند منجر به آموزش سریع تر شود زیرا شبکه در هر مرحله آموزش اطلاعات بیشتری دریافت می کند و بر اساس آن به روزرسانی وزن انجام می دهد. استفاده بهینه از منابع محاسباتی: استفاده از اندازه دسته بزرگتر می تواند منجر به استفاده بهینه تر از منابع محاسباتی مانند پردازنده های GPU و حافظه شود. از آنجا که شبکه با داده های بیشتری در هر مرحله آموزش کار می کند، می تواند از منابع محاسباتی استفاده بهینه تری کند. پایداری آموزش: استفاده از اندازه دسته بزرگتر می تواند به پایداری آموزش کمک کند. با افزایش تنوع داده های ورودی که توسط شبکه در هر مرحله مشاهده می شود، احتمال بیش برازش کاهش می یابد. به طور کلی، انتخاب اندازه دسته باید بر اساس نیازهای خاص مسئله، منابع محاسباتی موجود، و اهداف آموزش انجام شود.

دوره

یک "دوره" در آموزش شبکه های عصبی به یک بررسی کامل از کل مجموعه داده های آموزش اشاره دارد. در هر دوره، الگوریتم آموزش بر روی کل مجموعه داده تکرار می کند، داده ها را به شبکه عصبی در دسته ها می دهد، پیشرو و عقبگرد را انجام می دهد و پارامترهای مدل (وزن ها و سوگیری ها) را بر اساس گرادیان های محاسبه شده به روز می کند. تعداد دوره ها یک فراپارامتر مهم در آموزش شبکه های عصبی است و تعیین می کند که چند بار الگوریتم آموزش بر روی کل مجموعه داده تکرار خواهد شد. افزایش تعداد عصور به مدل اجازه می دهد تا داده های آموزش را چندین بار ببیند، که می تواند منجر به همگرایی بهتر و عملکرد بهبود یافته شود. با این حال، استفاده از تعداد زیادی دوره همچنین می تواند خطر بیش برازش را افزایش دهد، جایی که مدل داده های آموزش را به جای یادگیری الگوهای قابل تعمیم حفظ می کند. انتخاب تعداد عصور بستگی به عوامل مختلفی دارد، از جمله پیچیدگی مجموعه داده، اندازه مجموعه داده، معماری شبکه عصبی، و سطح عملکرد مدل مورد نظر. روش رایج این است که عملکرد مدل را در طول آموزش بر روی یک مجموعه داده اعتبارسنجی جداگانه نظارت کنید و زمانی که عملکرد بهبود نمی یابد یا شروع به تخریب می کند، آموزش را متوقف کنید، یک تکنیک به نام توقف زودهنگام. این کمک می کند تا از بیش برازش جلوگیری کند و اطمینان حاصل کند که مدل به خوبی به داده های دیده نشده تعمیم می یابد.


# ابرمقادیر پیشرفته

انتخاب بین بهینه سازهای Adam و SGD (Stochastic Gradient Descent) بستگی به عوامل مختلفی مانند ماهیت مسئله، مجموعه داده، و معماری شبکه عصبی دارد. در زیر مقایسه ای بین این دو بهینه ساز آورده شده است:&#x20;

Adam (Adaptive Moment Estimation): Adam یک الگوریتم بهینه سازی نرخ یادگیری تطبیقی است که مزایای هر دو AdaGrad و RMSProp را ترکیب می کند. این نرخ یادگیری جداگانه برای هر پارامتر را حفظ می کند و نرخ یادگیری را بر اساس لحظات اول و دوم گرادیان ها تطبیق می دهد. Adam برای محدوده گسترده ای از وظایف یادگیری عمیق مناسب است و برای همگرایی سریع و مقاومت در برابر گرادیان های نویزی شناخته شده است. این نیاز به تنظیم دستی دقیق تر هایپرپارامترها نسبت به SGD را کاهش می دهد، که باعث می شود برای بسیاری از وظایف آسان تر استفاده شود.

&#x20;SGD (Stochastic Gradient Descent): SGD

&#x20;یک الگوریتم بهینه سازی کلاسیک است که پارامترهای مدل را بر اساس گرادیان های تابع خطا نسبت به پارامترها به روز می کند. این برای تمام پارامترها از یک نرخ یادگیری ثابت استفاده می کند و نرخ یادگیری را در طول آموزش تطبیق نمی دهد. SGD می تواند حساس به انتخاب نرخ یادگیری باشد و ممکن است نیاز به تنظیم دستی برای دستیابی به عملکرد خوب داشته باشد. این از نظر محاسباتی کارآمد و حافظه کارآمد است، به خصوص برای مجموعه داده های بزرگ مقیاس، و گاهی اوقات می تواند بهتر از Adam عمومیت یابد.

به طور خلاصه، Adam اغلب گزینه پیش فرض برای وظایف یادگیری عمیق به دلیل مقاومت و سهولت استفاده اش است. با این حال، SGD همچنان می تواند موثر باشد، به خصوص وقتی با دقت تنظیم شده است، و ممکن است در برخی از سناریوها که کارایی محاسباتی یا تعمیم اولویت دارد، ترجیح داده شود. در نهایت، بهترین بهینه ساز بستگی به نیازها و محدودیت های خاص وظیفه در دست دارد، و توصیه می شود که با هر دو بهینه ساز آزمایش کنید تا مشخص شود کدام یک برای مشکل خاصی بهتر کار می کند.


# YAML (یامل)

یک فایل هایپرپارامتر در قالب YAML یک فایل پیکربندی است که حاوی هایپرپارامترها و تنظیمات مورد استفاده برای آموزش یک مدل شبکه عصبی است. YAML (که مخفف "YAML Ain't Markup Language" است) یک زبان سریال سازی داده خوانا برای انسان است که به دلیل سادگی و خوانایی آن، معمولاً برای فایل های پیکربندی استفاده می شود. در زیر نمونه ای از آنچه یک فایل هایپرپارامتر در قالب YAML ممکن است به نظر برسد، آورده شده است:

```yaml
model:
  type: "resnet"
  num_layers: 18
  num_classes: 10

optimizer:
  type: "adam"
  learning_rate: 0.001
  weight_decay: 0.0001

training:
  batch_size: 32
  num_epochs: 100
  early_stopping:
    patience: 5
    min_delta: 0.001

data:
  train_data_path: "/path/to/train_data"
  val_data_path: "/path/to/val_data"
  
```

در این مثال:

* در بخش مدل، هایپرپارامترهای مرتبط با معماری شبکه عصبی مشخص شده اند، مانند نوع مدل (مثلاً ResNet)، تعداد لایه ها، و تعداد کلاس های خروجی.
* در بخش بهینه ساز، هایپرپارامترهای مرتبط با بهینه ساز مورد استفاده برای آموزش مشخص شده اند، مانند نوع بهینه ساز (مثلاً Adam)، نرخ یادگیری، و تخفیف وزن.
* در بخش آموزش، هایپرپارامترهای مرتبط با فرآیند آموزش مشخص شده اند، مانند اندازه دسته، تعداد عصور، و معیارهای توقف زودهنگام.
* در بخش داده، مسیرهای مربوط به مجموعه داده های آموزش و اعتبارسنجی مشخص شده اند. استفاده از یک فایل YAML برای ذخیره هایپرپارامترها اجازه می دهد تا با تغییرات آسان و آزمایش با تنظیمات مختلف بدون نیاز به تغییر کد منبع اسکریپت آموزش، انجام شود. علاوه بر این، روشی روشن و سازمان یافته برای اسناد هایپرپارامترهای مورد استفاده برای آموزش یک مدل را فراهم می کند.


# اندازه تصویر

اندازه حداکثری برای تصاویر ورودی در طول آموزش بستگی به چندین عامل دارد از جمله معماری شبکه عصبی، منابع محاسباتی موجود، و خصوصیات مجموعه داده. اندازه حداکثری ثابتی وجود ندارد که به طور عمومی برای تمام سناریوها اعمال شود، بلکه این تصمیم باید بر اساس نیازها و محدودیت های خاص پروژه شما اتخاذ شود. در زیر برخی از ملاحظاتی آورده شده است که به شما کمک می کند تا اندازه حداکثری برای تصاویر ورودی آموزش را تعیین کنید:

* معماری شبکه عصبی: معماری های مختلف ممکن است محدودیت های متفاوتی در اندازه تصویر ورودی داشته باشند. برخی از معماری ها، مانند شبکه های کاملاً کانولوشنی، ممکن است در اندازه های ورودی انعطاف پذیرتر باشند، در حالی که دیگران، مانند کسانی که بر اساس مدل های پیش آموخته شده هستند، ممکن است نیازهای ثابتی در اندازه ورودی داشته باشند.
* منابع محاسباتی: تصاویر ورودی بزرگتر نیاز به حافظه و قدرت پردازش بیشتری دارند، بنابراین اندازه حداکثری ممکن است توسط منابع محاسباتی موجود، مانند حافظه GPU، محدود شود.
* خصوصیات مجموعه داده: خصوصیات مجموعه داده، مانند تنوع در اندازه اشیاء و نسبت های جنبه، ممکن است بر انتخاب اندازه تصویر ورودی تأثیر بگذارد. مهم است که اندازه ای را انتخاب کنید که جزئیات کافی برای اشیاء مورد علاقه در مجموعه داده را ضبط کند.
* اهداف آموزش: اهداف آموزش و نیازهای عملکرد همچنین ممکن است بر انتخاب اندازه تصویر ورودی تأثیر بگذارد. به عنوان مثال، اگر جزئیات با وضوح بالا برای تشخیص دقیق یا برش مهم است، ممکن است نیاز به اندازه ورودی بزرگتر باشد.
* افزایش داده: تکنیک های افزایش داده مانند برش تصادفی و تغییر اندازه می تواند کمک کند تا اثرات استفاده از اندازه های ورودی کوچکتر در طول آموزش را کاهش دهد. با این حال، مهم است که اطمینان حاصل کنید که افزایش داده تحریف یا آثار غیر واقعی را معرفی نمی کند. در عمل، رایج است که در طول آموزش با اندازه های ورودی مختلف آزمایش کنید تا تعادل بهینه بین عملکرد مدل و کارایی محاسباتی را پیدا کنید. شروع با اندازه متوسط و افزایش تدریجی آن در حالی که پیشرفت و عملکرد آموزش را بر روی یک مجموعه اعتبارسنجی نظارت می کنید، روش خوبی برای تعیین اندازه حداکثری برای تصاویر ورودی آموزش است.


# اعتبار سنجی تصاویر ورودی

اندازه تصاویر ورودی اعتبارسنجی باید در حالت ایده آل با اندازه ورودی مورد استفاده در طول آموزش مطابقت داشته باشد تا در فرآیند ارزیابی، سازگاری و قابلیت مقایسه را تضمین کند. این به این معنی است که تصاویر اعتبارسنجی باید قبل از ورود به مدل برای ارزیابی، به ابعاد مشابه تصاویر آموزش تغییر اندازه یا برش داده شوند. حفظ سازگاری در اندازه تصاویر ورودی بین آموزش و اعتبارسنجی مهم است زیرا:

* سازگاری مدل: مدل های شبکه عصبی معمولاً طراحی شده اند تا تصاویر ورودی با اندازه خاصی را قبول کنند. استفاده از اندازه های مختلف در طول آموزش و اعتبارسنجی ممکن است منجر به ابعاد ورودی ناسازگار شود، که منجر به خطاها یا رفتار غیرمنتظره می شود.
* سازگاری ارزیابی: ارزیابی عملکرد مدل بر روی داده های اعتبارسنجی که اندازه آنها با داده های آموزش متفاوت است، ممکن است نمایانگر دقیق عملکرد واقعی آن نباشد. اندازه های ورودی سازگار اطمینان می دهد که مدل تحت شرایط مشابهی با آموزش ارزیابی می شود.
* مقایسه عادلانه: اندازه های ورودی سازگار امکان مقایسه های عادلانه بین مدل های مختلف یا پیکربندی ها را فراهم می کند. اگر مدل های مختلف با اندازه های ورودی مختلف آموخته شوند، عملکرد آنها نمی تواند بدون در نظر گرفتن این تفاوت، مستقیماً مقایسه شود. برای اطمینان از سازگاری، توصیه می شود تا تصاویر اعتبارسنجی را برای مطابقت با اندازه ورودی مورد استفاده در آموزش پیش پردازش کنید. این ممکن است شامل تغییر اندازه، برش یا پد کردن تصاویر به میزان لازم باشد. علاوه بر این، مهم است که مراحل پیش پردازش و اندازه های ورودی مورد استفاده در هر دو آموزش و اعتبارسنجی را برای اطمینان از شفافیت و قابلیت تکرار در فرآیند ارزیابی، ثبت کنید.


# انتظار

اصطلاح "انتظار" در زمینه یادگیری ماشین معمولاً به تعداد دوره ها اشاره دارد که باید منتظر بمانیم قبل از اینکه آموزش را در صورت عدم بهبود در معیار اعتبارسنجی متوقف کنیم. این در ارتباط با تکنیک هایی مانند توقف زودهنگام استفاده می شود تا از بیش برازش جلوگیری کند و تعمیم مدل را بهبود بخشد. مقدار "انتظار" یک فراپارامتر است که حداکثر تعداد عصور را برای ادامه آموزش بدون بهبود در معیار اعتبارسنجی مشخص می کند. مقادیر حداقل و حداکثر ارائه شده (به ترتیب 0 و 100000) محدوده ای را نشان می دهند که در آن می توان فراپارامتر "انتظار" را مشخص کرد. در اینجا معنی آن را می بینید: مقدار "انتظار" برابر با 0 به این معنی است که آموزش فوراً متوقف خواهد شد اگر پس از اولین دوره هیچ بهبودی مشاهده نشود. مقدار "انتظار" برابر با 100000 به این معنی است که آموزش حداکثر برای 100000 دوره ادامه خواهد یافت حتی اگر هیچ بهبودی مشاهده نشود. در عمل، مقدار "انتظار" معمولاً بر اساس آزمایش و عملکرد اعتبارسنجی انتخاب می شود. باید تعادلی بین اجازه دادن به مدل برای یادگیری الگوهای معنی دار در داده ها و جلوگیری از بیش برازش با توقف آموزش زمانی که عملکرد در مجموعه اعتبارسنجی شروع به تخریب می شود، برقرار کند. روش رایج این است که با یک مقدار نسبتاً کوچک برای "انتظار" شروع کنید و در صورت لزوم آن را تدریجاً افزایش دهید. مقادیر بین 5 تا 20 اغلب به عنوان نقطه شروع استفاده می شوند، اما مقدار بهینه ممکن است بسته به مجموعه داده، معماری مدل، و اهداف آموزش متفاوت باشد.


# آموزش مستطیلی

"آموزش مستطیلی" به استراتژی آموزشی اشاره دارد که در آن تصاویر ورودی قبل از ورود به شبکه عصبی برای آموزش، تغییر اندازه یا برش داده می شوند تا نسبت ثابتی داشته باشند. در آموزش مستطیلی، نسبت تصاویر ورودی معمولاً متفاوت از نسبت تصاویر اصلی در مجموعه داده است. اینجا چگونگی کار آموزش مستطیلی است: تغییر اندازه یا برش: در آموزش مستطیلی، تصاویر ورودی تغییر اندازه یا برش داده می شوند تا نسبت ثابتی داشته باشند، که اغلب بر اساس ملاحظات عملی یا محدودیت های معماری شبکه عصبی انتخاب می شوند. این ممکن است شامل پد کردن یا برش دادن تصاویر ورودی برای جا به جایی در نسبت مورد نظر باشد. نرمال سازی: پس از تغییر اندازه یا برش، تصاویر ورودی معمولاً نرمال سازی می شوند تا اطمینان حاصل کنند که ارزش های پیکسل در تصاویر مختلف یکنواخت است. این مرحله نرمال سازی کمک می کند تا پایداری و همگرایی فرآیند آموزش را بهبود بخشد. آموزش: سپس تصاویر تغییر اندازه یا برش داده شده به شبکه عصبی برای آموزش داده می شوند. در طول آموزش، شبکه یاد می گیرد تا ویژگی ها را استخراج کند و بر اساس تصاویر ورودی مستطیلی پیش بینی کند. آموزش مستطیلی می تواند چندین مزیت ارائه دهد، از جمله: بهبود تعمیم: با آموزش مدل بر روی تصاویر ورودی با نسبت ثابت، آموزش مستطیلی می تواند به بهبود عملکرد تعمیم مدل کمک کند، به خصوص وقتی که نسبت تصاویر اصلی در مجموعه داده به طور گسترده ای متفاوت است. پیاده سازی ساده شده: آموزش مستطیلی می تواند پیاده سازی مدل شبکه عصبی را با اطمینان از اینکه تمام تصاویر ورودی دارای نسبت ثابتی هستند، ساده کند. این می تواند طراحی و آموزش معماری مدل را آسان تر کند. استفاده کارآمد از حافظه: تغییر اندازه یا برش دادن تصاویر ورودی به نسبت ثابت می تواند به بهینه سازی استفاده از حافظه در طول آموزش کمک کند، به خصوص وقتی که با منابع محاسباتی محدود مانند حافظه GPU کار می کنید. در کل، آموزش مستطیلی یک تکنیک مفید برای آموزش مدل های شبکه عصبی بر روی مجموعه داده ها با نسبت های متغیر است، و می تواند به بهبود عملکرد و کارایی فرآیند آموزش کمک کند.


# معرفی بینااکسپرتز

به بینااکسپرتز خوش آمدید، همراه و همیار شما در پیمودن هر مرحله از چرخه حیات بینایی کامپیوتری (CV).

[بینااکسپرتز](https://binaexperts.com/fa) یک پلتفرم جامع و یکپارچه در حوزه بینایی ماشین است که تمامی نیازهای شما را به‌صورت کامل و کارآمد پوشش می‌دهد. این پلتفرم به گونه‌ای طراحی شده است که تمامی مراحل ایجاد و توسعه یک پروژه بینایی ماشین را از ابتدا تا انتها مدیریت کند و به شما امکان دهد بدون نیاز به دانش کدنویسی یا مهارت‌های فنی پیچیده، به نتایج مطلوب دست یابید.

## امکانات و قابلیت‌ها:&#x20;

مدیریت کامل پروژه‌های بینایی ماشین:

پلتفرم [بینااکسپرتز ](https://binaexperts.com/fa)تمامی مراحل ساخت یک مدل بینایی ماشین را به‌صورت یکپارچه پوشش می‌دهد. این مراحل شامل جمع‌آوری و پیش‌پردازش داده‌ها، برچسب‌گذاری (Labeling)، افزایش داده‌ها (Data Augmentation)، آموزش مدل و خروجی گرفتن است. شما می‌توانید داده‌های خود را به‌سادگی بارگذاری کنید، آن‌ها را پیش‌پردازش و برچسب‌گذاری کنید و در نهایت مدل‌های خود را آموزش داده و خروجی‌های نهایی را دریافت کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2Fn2Oakxmv0C8nuLrrFZ1L%2Fimage.png?alt=media&amp;token=65af2083-d321-414f-a255-bd6281a70485" alt=""><figcaption><p>امکانات موجود در پلتفرم بینایی ماشین <a href="https://binaexperts.com/fa">بینااکسپرتز</a></p></figcaption></figure>

تطبیق و سازگاری با فریم‌ورک‌ها و کتابخانه‌های معروف:

[بینااکسپرتز](https://binaexperts.com/fa) با پشتیبانی از فریم‌ورک‌ها و کتابخانه‌های پرکاربردی مانند TensorFlow، PyTorchو  OpenCV، انعطاف‌پذیری بالایی را برای تیم شما فراهم می‌کند. این قابلیت به شما امکان می‌دهد پروژه‌های خود را با هر ابزار و تکنولوژی‌ که مدنظر دارید، توسعه دهید و از مزایای سازگاری بالای آن بهره‌مند شوید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FrQbjW78kOQtLjS6GmuSr%2Fimage.png?alt=media&amp;token=74cb537d-d373-4ca0-b4f1-c4d678acd37b" alt=""><figcaption><p>پشتیبانی از فریم ورک های مختلف در پلتفرم بینااکسپرتز</p></figcaption></figure>

بدون نیاز به دانش کدنویسی:

یکی از ویژگی‌های برجسته [بینااکسپرتز](https://binaexperts.com/fa) این است که شما برای استفاده از این پلتفرم به هیچ‌گونه دانش کدنویسی یا مهارت‌های نرم‌افزاری نیاز ندارید. تمامی فرآیندها به‌صورت گرافیکی و کاربرپسند طراحی شده‌اند و شما می‌توانید تنها با بارگذاری داده‌های خود و دنبال کردن مراحل ساده، به مدل بینایی ماشین مطلوب خود دست یابید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FVaFUijsn952aBSgJ038Z%2Fimage.png?alt=media&amp;token=ef0ff20f-b2db-4ecb-bfc8-ce5e55367178" alt=""><figcaption><p>در پلتفرم بینااکسپرتز تمامی فرآیندها به‌صورت گرافیکی طراحی شده‌ و کاربر می‌تواند تنها با بارگذاری داده‌های خود و دنبال کردن مراحل ساده، به مدل بینایی ماشین مطلوب خود دست یابد.</p></figcaption></figure>

## چرا بینااکسپرتز ؟

پلتفرم [بینااکسپرتز](https://binaexperts.com/fa) به‌طور یکپارچه با چارچوب‌ها و کتابخانه‌های شناخته‌شده و معتبر بینایی کامپیوتری ادغام می‌شود، به تیم شما اجازه می‌دهد تا از تخصص و تجربه‌های موجود خود به بهترین نحو استفاده کرده و هم‌زمان به امکانات و ویژگی‌های پیشرفته‌ای که ما ارائه می‌دهیم، دسترسی داشته باشند. با بهره‌گیری از بینااکسپرتز، شما می‌توانید همکاری‌ها را در تیم خود بهبود بخشید، فرآیند تکرار و اصلاح مدل‌ها را سرعت بخشیده و نوآوری‌های بیشتری را در پروژه‌های خود به ارمغان آورید. این امر تضمین می‌کند که پروژه‌های بینایی کامپیوتری شما نتایج مؤثر و قابل‌توجهی داشته باشند.

در دنیای پرشتاب و پیوسته در حال تحول امروز، انتخاب بینااکسپرتز به شما این امکان را می‌دهد که همیشه یک قدم جلوتر از رقبا باشید. ویژگی‌های منحصربه‌فرد پلتفرم ما را کشف کنید و از تفاوت‌هایی که یک پلتفرم اختصاصی و متعهد می‌تواند ایجاد کند، بهره‌مند شوید. این پلتفرم نه تنها نیازهای شما را برآورده می‌کند، بلکه فراتر از انتظارات شما خواهد رفت. با همکاری یکدیگر، می‌توانیم پروژه‌های بینایی کامپیوتری شما را به موفقیت‌هایی بی‌سابقه و تحولی عظیم تبدیل کنیم.


# آغاز به کار پلتفرم بینااکسپرتز

آموزش سریع بینااکسپرتز

بینااکسپرتز همه چیزهایی که برای برچسب‌گذاری، آموزش و پیاده‌سازی راه‌حل‌های بینایی کامپیوتری نیاز دارید، فراهم می‌کند. از اطلاعات این راهنما استفاده کنید تا یک مدل بینایی کامپیوتری برای کاربرد خاص خود ایجاد کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FmshDOKPDdzN8l1cEt9HW%2Fimage.png?alt=media&amp;token=675718ea-ca75-49ab-8286-5cfd37ec539b" alt=""><figcaption><p>چرخه ایجاد و استقرار مدل هوشمند بینایی کامپیوتر با پلتفرم بینااکسپرتز</p></figcaption></figure>

## شروع به کار با پلتفرم بینااکسپرتز

آموزش سریع (۶ دقیقه‌ای)

&#x20;

1\.      **اضافه کردن داده‌ها**

پس از مرور و پذیرش شرایط خدمات، از شما خواسته می‌شود بین یکی از سه پلن انتخاب کنید: پلن عمومی، پلن ابتدایی و پلن سفارشی.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FQAHK4tIVv08kTz0Ph1Do%2Fimage.png?alt=media&amp;token=00468d1b-59cd-45c7-9bd1-cdcae73843b9" alt=""><figcaption><p>قیمت گذاری پلتفرم بینایی ماشین بینااکسپرتز</p></figcaption></figure>

&#x20;

2\.     **اضافه کردن هم تیمی**

سپس از شما خواسته می‌شود همکاران را به فضای کاری خود دعوت کنید. این همکاران می‌توانند به شما در حاشیه‌نویسی تصاویر یا مدیریت پروژه‌های بینایی در فضای کاری‌تان کمک کنند. بعد از دعوت افراد به فضای کاری (در صورت تمایل)، می‌توانید یک پروژه ایجاد کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FuVTUu6KmMsCktvTRFNzC%2Fimage.png?alt=media&amp;token=fc4cc47c-e159-4527-9c87-2602ecf07114" alt=""><figcaption><p>اضافه کردن هم تیمی به سازمان در بینااکسپرتز</p></figcaption></figure>

&#x20;

3\.   **انتخاب نوع پروژه‌های بینایی کامپیوتر**

برای این مثال، ما از یک دیتاست استفاده خواهیم کرد. این مدل می‌تواند برای تضمین کیفیت در یک کارخانه تولیدی مورد استفاده قرار گیرد. البته، شما می‌توانید از هر تصویری که می‌خواهید برای آموزش مدل استفاده کنید.

نوع پروژه را به حالت پیش‌فرض "تشخیص اشیا" بگذارید چون مدل ما به شناسایی اشیای خاص می‌پردازد و می‌خواهیم موقعیت آن‌ها را در تصویر بدانیم.

روی "ایجاد پروژه" کلیک کنید تا ادامه دهید.

برای این راهنما، از دیتاست کلاه ایمنی ارائه شده توسط بینااکسپرتز استفاده خواهیم کرد. دیتاست "helmet" را دانلود کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F8MwmvD5QM7mnrixd2w9D%2Fimage.png?alt=media&amp;token=06ad04fe-fcf1-4ebf-aabd-62db75598303" alt=""><figcaption><p>انتخاب نوع پروژه بینایی کامپیوتر در بینااکسپرتز</p></figcaption></figure>

&#x20;

## بارگذاری دیتاست

پس از دانلود دیتاست، فایل را از حالت فشرده خارج کنید. پوشه “helmet”را از سیستم خود به ناحیه بارگذاری مشخص شده بکشید. این دیتاست در قالب COCO JSON ساختاربندی شده، که یکی از بیش از ۵ قالب بینایی کامپیوتری پشتیبانی شده توسط بینااکسپرتز است.

برای شروع، توصیه می‌کنیم از ۵ تا ۱۰ تصویر استفاده کنید که کلاس‌های موردنظر شما برای شناسایی را به تعادل برساند. به عنوان مثال، اگر نیاز به شناسایی کلاه ایمنی دارید، اطمینان حاصل کنید که حداقل ۵ تا ۱۰ تصویر شامل این شی باشد.

هنگامی که پوشه دیتاست "helmet" را آپلود می‌کنید، بینااکسپرتز تصاویر و برچسب‌گذاری‌ها را پردازش می‌کند تا آن‌ها را با برچسب‌ها نمایش دهد.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FIkafLJKGbQUWTG182Uno%2Fimage.png?alt=media&amp;token=9b449086-62b4-4154-84a8-467c7847290d" alt=""><figcaption><p>بارگذاری دیتاست تشخیص کلاه ایمنی با بینااکسپرتز</p></figcaption></figure>

&#x20;

## بررسی و تصحیح برچسب‌گذاری‌ها

بینااکسپرتز به شما درباره هرگونه خطای برچسب‌گذاری هشدار خواهد داد. به عنوان مثال، اگر یک برچسب‌گذاری به‌طور نادرست از چارچوب تصویر خارج شود، بینااکسپرتز هوشمندانه برچسب‌گذاری را به لبه تصویر کوتاه می‌کند و برچسب‌های اشتباه خارج از چارچوب را حذف می‌کند.

در این مرحله، تصاویر شما هنوز بارگذاری نشده‌اند. اطمینان حاصل کنید که همه تصاویر صحیح هستند و برچسب‌گذاری‌ها به‌درستی پردازش شده‌اند. می‌توانید با قرار دادن ماوس بر روی هر تصویر و انتخاب آیکون سطل زباله، هر تصویری را حذف کنید.

اگر هر تصویری با علامت "بدون برچسب‌گذاری" مشخص شده باشد، می‌توانید در بخش بعدی آن را برچسب‌گذاری کنید. برای آپلود داده‌های خود، روی "ذخیره و ادامه" کلیک کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FQZvjnW8DptXa3dFthVKV%2Fimage.png?alt=media&amp;token=030fe81e-1a26-48a5-b137-898addd00ffc" alt=""><figcaption><p>برچسب گذاری در پلتفرم بینایی ماشین بینااکسپرتز</p></figcaption></figure>

&#x20;

## انتخاب تقسیم‌بندی دیتاست

تصمیم بگیرید که چگونه تصاویر خود را بین مجموعه‌های آموزش، اعتبارسنجی و آزمایش تقسیم کنید.

&#x20;

**مجموعه آموزش:** برای آموزش مدل شما استفاده می‌شود.

**مجموعه اعتبارسنجی:** برای ارزیابی عملکرد مدل در طول آموزش استفاده می‌شود.

**مجموعه آزمایش:** برای آزمون دستی عملکرد مدل استفاده می‌شود.

گزینه **"استفاده از مقادیر موجود"** را برای استفاده از دیتاست از پیش تقسیم‌شده توسط بینااکسپرتز انتخاب کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FbXvm1q5KJfaidWsoACJq%2Fimage.png?alt=media&amp;token=f521c0b6-bead-40b0-9765-b2d63c8f260b" alt=""><figcaption><p>تقسیم دیتاست به داده های آموزش، اعتبارسنجی و تست</p></figcaption></figure>

&#x20;

## آپلود ویدئوها

علاوه بر تصاویر، می‌توانید ویدئوها را نیز بارگذاری کنید. به برگه "بارگذاری" بروید، یک ویدئو را بکشید یا یک URL  یوتیوب را بچسبانید. از شما پرسیده می‌شود که چند فریم در هر ثانیه باید گرفته شود. به عنوان مثال، انتخاب "۱ فریم/ثانیه" یک تصویر را در هر ثانیه از ویدئو ضبط می‌کند.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FJFvvM8ydZXv6dHo5L6Z6%2F-11.gif?alt=media&amp;token=a65f2626-78d5-482e-b830-b5b906cb101c" alt=""><figcaption><p>بارگذاری ویدئو  و انتخاب تعداد فریم در ثانیه</p></figcaption></figure>

&#x20;

## برچسب‌گذاری تصاویر

از ابزار "Annotate" بینااکسپرتز برای اضافه کردن برچسب‌ها، مانند جعبه‌های مرزی، به اطراف اشیا بدون برچسب استفاده کنید. این برچسب‌ها به عنوان کلید پاسخ برای آموزش مدل شما عمل می‌کنند. می‌توانید تصاویر بیشتری را برچسب‌گذاری کنید تا بهبود یادگیری مدل را تسریع کنید. برای رسم یک جعبه، از نشانگر خود برای انتخاب ناحیه روی تصویر استفاده کنید و سپس یک برچسب به آن اختصاص دهید.

&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FtaRX6VgQ0vXJtFTgDBij%2F-12.gif?alt=media&amp;token=59b15bf8-2bd2-4efd-a888-a136bf0088a2" alt=""><figcaption><p>برچسب گذاری تصاویر در بینااکسپرتز</p></figcaption></figure>

{% hint style="info" %}
نکته حرفه‌ای: از AutoLabel بینااکسپرتز استفاده کنید تا از نسخه‌های قبلی مدل برای برچسب‌گذاری مجموعه داده‌های آینده استفاده کنید. AutoLabel از یک مدل موجود برای ایجاد برچسب‌ها به‌صورت خودکار بهره می‌برد و این فرآیند را تسریع می‌کند.
{% endhint %}

بینااکسپرتز همچنین از برچسب‌گذاری چندضلعی پشتیبانی می‌کند که برای پروژه‌هایی که نیاز به موقعیت‌یابی دقیق اشیا دارند، ضروری است. برای استفاده از "چندضلعی" روی آیکون پایین در نوار کناری سمت چپ کلیک کنید.

&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FQZn0HgNHK7cBrP5rfwAf%2F-13.png?alt=media&amp;token=d5c78ad8-79d9-4927-99ae-5e89d31e1105" alt=""><figcaption><p>استفاده از برچسب گذاری چند ضلعی در بینااکسپرتز </p></figcaption></figure>

## افزودن تصاویر به دیتاست

برای افزودن تصاویر یا داده‌ها به دیتاست، روی گزینه "افزودن داده جدید" کلیک کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F8xkkdQiwxKRJoD6EUjKv%2F-14.webp?alt=media&amp;token=7f72c04e-0986-4faf-a8a1-3aeb3a2c92da" alt=""><figcaption><p>اضافه کردن تصاویر به دیتاست در بینااکسپرتز</p></figcaption></figure>

&#x20;

## پیش‌پردازش و افزایش تصاویر

پس از تکمیل برچسب‌گذاری‌ها، یک نسخه جدید از دیتاست ایجاد کنید. این نسخه شامل تصاویر پردازش‌شده به روشی خاص است، مشابه کنترل نسخه برای داده‌ها.

&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FtS2ICDc4wKSwQ6JFAanE%2F-15.webp?alt=media&amp;token=817e1c58-10c3-467c-8291-73a9560e40d5" alt=""><figcaption><p>پیش پردازش و افزایش تصاویر</p></figcaption></figure>

می‌توانید پیش‌پردازش‌ها و افزایش‌هایی مانند تغییر اندازه، خاکستری‌سازی، چرخش‌های تصادفی، تنظیم روشنایی، محوکردن، شیب‌دهی، برش و موارد دیگر را اعمال کنید. با یکی یا دو افزایش شروع کنید و بر اساس نیاز تنظیمات را تغییر دهید. به‌طور کلی، از افزایش ها در اولین کار آموزش برای ارزیابی عملکرد مدل اجتناب کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2Fcukp5zdKYINU4BeItpby%2F-16.webp?alt=media&amp;token=709f9205-a31d-4088-901e-714d138b1d1a" alt=""><figcaption><p>انواع افزایش در بینااکسپرتز</p></figcaption></figure>

&#x20;

## آموزش مدل خود

برای آموزش مدل در پلتفرم بینااکسپرتز:

1\.        روی دکمه "آموزش" کلیک کنید.

2\.      تنظیمات کار آموزش مدل خود را پیکربندی کنید.

3\.     نوع مدل را انتخاب کنید. برای این راهنما " سریع " را انتخاب کنید.

4\.      نقطه بازبینی را برای آموزش انتخاب کنید.

5\.     پیشرفت آموزش را از طریق نمودارهای لحظه‌ای نظارت کنید.

&#x20;

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FgaZBXmBSjbSzSqDLqfYO%2Fimage.png?alt=media&amp;token=1976c283-d48b-49c7-97b5-bab3f7700743" alt=""><figcaption><p>تنظیمات آموزش مدل در پلتفرم بینااکسپرتز</p></figcaption></figure>

&#x20;

پس از اتمام آموزش، ایمیلی با نتایج آموزش دریافت خواهید کرد.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FJRxgcOzTwXDQH0T4dCLQ%2Fimage.png?alt=media&amp;token=9eccf095-937a-42d8-bb60-7e920e6fa653" alt=""><figcaption><p>مشاهده نتایج آموزش مدل در بینااکسپرتز</p></figcaption></figure>

&#x20;

## پیاده‌سازی یک مدل بینایی کامپیوتری

مدل آموزش‌دیده شما بهینه شده و آماده پیاده‌سازی است. بینااکسپرتز از گزینه‌های مختلف پیاده‌سازی، مانند یکپارچه‌سازی API یا پیاده‌سازی در دستگاه‌های Edge پشتیبانی می‌کند.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F3KOtvIYVM7siQn1uZAtQ%2Fimage.png?alt=media&amp;token=45f28964-7f69-41e2-bb1e-5c89d61d3893" alt=""><figcaption><p>استقرار مدل آموزش دیده توسط بینااکسپرتز</p></figcaption></figure>

&#x20;

با استفاده از API میزبان بینااکسپرتز (سرور از راه دور)، مدل در ابر اجرا می‌شود و نیازی به نگرانی در مورد قابلیت‌های سخت‌افزاری دستگاه وجود ندارد.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FLBrb4JOWqST9dj2qZjPu%2F-20.webp?alt=media&amp;token=c9914e7a-7192-4361-a588-171130ba620e" alt=""><figcaption><p>آماده سازی مدل برای استقرار</p></figcaption></figure>

همچنین می‌توانید مدل‌ها را با استفاده از گزینه‌های دیگر مناسب برای برنامه‌های تولیدی خود پیاده‌سازی کنید. برای جزئیات بیشتر، به راهنمای پیاده‌سازی ما مراجعه کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FiB8NdrXpBxkWKwLaeiYs%2F-21.png?alt=media&amp;token=49e1e914-a7cf-405e-82d2-cc109d092120" alt=""><figcaption><p>مشاهده نتایج آموزش مدل و آماده سازی استقرار</p></figcaption></figure>


# ایجاد سازمان

برای مدیریت پروژه‌ها به‌صورت گروهی، می‌توانید یک سازمان جدید ایجاد کنید.

تمامی پروژه‌های بینایی ماشین در [BinaExperts](https://binaexperts.com/fa) در یک محیط کاری (Workspace) قرار می‌گیرند. هنگامی که شما در [BinaExperts](https://binaexperts.com/fa) ثبت‌نام می‌کنید، به‌طور خودکار یک محیط کاری برای شما ایجاد می‌شود.

&#x20;

محیط‌های کاری به شما اجازه می‌دهند تا مدیریت کنید که چه کسانی به چه پروژه‌هایی دسترسی دارند و همچنین چه ویژگی‌هایی برای پروژه‌های داخل محیط کاری فعال باشد.

**ایجاد سازمان جدید**

پس از ورود به حساب کاربری خود، برای ایجاد یک سازمان جدید، روی **ADD NEW  ITEM** کلیک کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FnB8HVkgqTB6lm7ruclzN%2Fimage.png?alt=media&amp;token=094bbe9a-e809-4ea9-b406-c9aeba842c7a" alt=""><figcaption><p>ایجاد یک سازمان جدید</p></figcaption></figure>

در سازمان خود، می‌توانید به جستجو در پروژه‌هایتان بپردازید، آن‌ها را وارد کنید و با هم ادغام نمایید و همچنین سطح دسترسی اعضای مورد نظر را تعریف کنید.

&#x20;

علاوه بر این، در نوار کناری می‌توانید به موارد زیر دسترسی داشته باشید:

&#x20;

1\.        لیست اعضا

2\.      مصرف منابع برای آموزش مدل‌ها

3\.     پروفایل‌ها

4\.      لاگ‌های سازمانی مربوط به آموزش مدل‌ها

&#x20;


# اضافه کردن عضو

افزودن اعضای تیم به سازمان در  BinaExperts

با دعوت اعضای تیم خود به سازمان [BinaExperts](https://binaexperts.com/fa)، به‌راحتی بر روی پروژه‌های خود به صورت مشترک کار کنید. در اینجا نحوه‌ی افزودن اعضا به تیم توضیح داده شده است:

**دسترسی به تنظیمات فضای کاری:** به تنظیمات فضای کاری مورد نظر که می‌خواهید اعضای تیم را به آن اضافه کنید، بروید.

**دعوت از اعضا:** در بخش "اعضای سازمان"، آدرس ایمیل عضو مورد نظر را وارد کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FyDwcA1SIF5bITKdGbMWM%2F1.png?alt=media&amp;token=d1e75480-9917-4708-b4e6-610a476ea4d4" alt=""><figcaption><p>دعوت از اعضا</p></figcaption></figure>

**ارسال دعوت‌نامه:** پس از وارد کردن آدرس ایمیل، دعوت‌نامه را مستقیماً از طریق پلتفرم ارسال کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F90PIORuU7laHfAMYabGd%2F2.png?alt=media&amp;token=1ddd5a00-db07-4066-a2be-8ed80ba0517f" alt=""><figcaption><p>ارسال دعوت نامه از طریق ایمیل</p></figcaption></figure>

**تکمیل ثبت‌نام:** عضو دعوت‌شده ایمیلی حاوی لینک ثبت‌نام دریافت خواهد کرد. او می‌تواند با دنبال کردن دستورالعمل‌های موجود در ایمیل، فرآیند ثبت‌نام را کامل کند.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F6nKN7MJLxYEouUgSPldp%2F3.png?alt=media&amp;token=83519660-15ff-4b55-9a3d-93853f0b8276" alt=""><figcaption><p>تکمیل ثبت نام</p></figcaption></figure>

با انجام این مراحل، می‌توانید تیم خود را به‌راحتی گسترش داده و همکاری درون سازمان [BinaExperts](https://binaexperts.com/fa) را بهبود بخشید.


# کنترل دسترسی مبتنی بر نقش

کنترل دسترسی مبتنی بر نقش در بینا اکسپرتز

با استفاده از کنترل دسترسی مبتنی بر نقش (RBAC)، می‌توانید سطح دسترسی اعضا را در سازمان خود به‌طور مؤثر مدیریت کنید. با کلیک بر روی "افزودن گروه جدید"، می‌توانید گروه‌هایی ایجاد کرده و سطح دسترسی هر عضو را در موارد مختلف به‌طور دقیق تعریف کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F0B9dLoKQ2YPlHfDJRwD3%2F4.gif?alt=media&amp;token=e3569d13-46b9-4133-9a04-f03445810bb2" alt=""><figcaption><p>کنترل دسترسی مبتنی بر نقش در <a href="https://binaexperts.com/fa">بینا اکسپرتز</a></p></figcaption></figure>

&#x20;

برای هر کاربر، می‌توانید هر یک از دسترسی‌های زیر را اختصاص دهید:

·         دسترسی به استنتاج انبوه

·         دسترسی به لغو آموزش

·         دسترسی به ایجاد مجموعه داده

·         دسترسی به ایجاد نسخه مجموعه داده

·         دسترسی به ایجاد استقرار

·         دسترسی به ایجاد گروه

·         دسترسی به ایجاد استنتاج

·         دسترسی به ایجاد سازمان

·         دسترسی به ایجاد وظیفه

·         دسترسی به ایجاد آموزش

·         دسترسی به حذف مجموعه داده

·         دسترسی به حذف نسخه مجموعه داده

·         دسترسی به حذف استقرار

·         دسترسی به حذف گروه

·         دسترسی به حذف استنتاج

·         دسترسی به حذف سازمان

·         دسترسی به حذف وظیفه

·         دسترسی به حذف آموزش

·         مدیر استقرار: دسترسی به ایجاد استقرار

·         مدیر استقرار: دسترسی به دانلود

·         مدیر استقرار: دسترسی به استنتاج

·         مدیر استقرار: دسترسی به بارگیری، تخلیه، بارگذاری مجدد استقرار

·         دسترسی به دانلود پیکربندی

·         دسترسی به دانلود مدل

·         دسترسی به دانلود تصاویر تست

·         دسترسی به دانلود تصاویر اعتبارسنجی

·         دسترسی به صادرات مجموعه داده

·         دسترسی به لیست تصاویر سازمان

·         کاربر سازمان: دسترسی به تغییر وضعیت فعالیت

·         دسترسی به TensorBoard آموزش

·         دسترسی به به‌روزرسانی مجموعه داده

·         دسترسی به به‌روزرسانی نسخه مجموعه داده

·         دسترسی به به‌روزرسانی استقرار

·         دسترسی به به‌روزرسانی گروه

·         دسترسی به به‌روزرسانی استنتاج

·         دسترسی به به‌روزرسانی سازمان

·         دسترسی به به‌روزرسانی وظیفه

·         دسترسی به به‌روزرسانی آموزش

همچنین در [بینا اکسپرتز](https://binaexperts.com/fa) می‌توانید همه این دسترسی‌ها را به یک کاربر اختصاص دهید.


# ایجاد یک پروژه

ایجاد یک پروژه در بینا اکسپرتز

پروژه به عنوان مخزن مرکزی تصاویر و حاشیه‌نویسی‌های شما در یک فضای کاری عمل می‌کند. پس از حاشیه‌نویسی تصاویر، می‌توانید یک نسخه ایجاد کنید(یک عکس فوری از تصاویر و حاشیه‌نویسی‌های شما در همان لحظه) که بر اساس پیکربندی انتخابی شما تقویت و پردازش شده است.

یک پروژه شامل موارد زیر است:

·        **نام:** عنوان پروژه شما.

·        **نوع:** ماهیت پروژه (به عنوان مثال، تشخیص اشیا).

·        **گروه حاشیه‌نویسی:** گروه مسئول حاشیه‌نویسی تصاویر.

مراحل ایجاد یک پروژه

1\.        **دسترسی به داشبورد BinaExperts:** ابتدا با ورود به داشبورد [BinaExperts](https://binaexperts.com/fa) شروع کنید.

2\.      **ایجاد پروژه جدید:** روی «ایجاد پروژه جدید» کلیک کنید. از شما خواسته می‌شود که جزئیات زیر را وارد کنید:

·         **نوع داده:** نوع پروژه را انتخاب کنید. در اینجا خلاصه‌ای از هر نوع آورده شده است:

**o**       ***تشخیص اشیا:*** شناسایی و تعیین موقعیت اشیا در یک تصویر.

**o      &#x20;*****طبقه‌بندی چند‌برچسبی:*** اختصاص چندین برچسب مرتبط به یک تصویر از مجموعه‌ای از دسته‌بندی‌های از پیش تعریف شده.

**o**       ***تقسیم‌بندی نمونه:*** تعیین موقعیت اشیا در تصویر به صورت پیکسلی.

·         **نام پروژه:** یک نام معنادار برای پروژه خود وارد کنید.

·         **برچسب‌ها و توضیحات پروژه:** برای سازماندهی بهتر و درک هدف پروژه، برچسب‌ها و توضیحات مربوطه را ارائه دهید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FAi4cY9wEZObp0jnwloct%2Fimage.png?alt=media&amp;token=753e686f-ce4c-4a51-bd73-020f3b07587d" alt=""><figcaption><p><strong>برچسب‌ها و توضیحات پروژه</strong></p></figcaption></figure>

3\.     **ارسال فرم:** پس از وارد کردن جزئیات لازم، فرم را ارسال کنید تا پروژه شما ایجاد شود.

4\.      **پیشنهاد انواع جدید پروژه:** اگر مایلید که انواع پروژه‌های بیشتری پشتیبانی شود، می‌توانید با انتخاب گزینه مناسب از منوی کشویی نوع پروژه، علاقه خود را اعلام کنید.


# بارگذاری داده‌ها

بارگذاری داده‌ها در بینا اکسپرتز

**استفاده از رابط وب (مناسب برای ≤1000 تصویر)**

**بارگذاری داده‌ها از طریق رابط وب**

برای بارگذاری داده‌ها، ابتدا باید یک پروژه ایجاد کنید. اگر هنوز پروژه‌ای ندارید، با ایجاد یک پروژه جدید شروع کنید. در طول فرآیند ایجاد پروژه، از شما خواسته می‌شود تا تصاویر خود را بارگذاری کنید.

اگر از قبل پروژه‌ای دارید، کافی است روی "بارگذاری" در نوار کناری پروژه کلیک کنید تا تصاویر بیشتری اضافه کنید.

**انواع داده‌های پشتیبانی شده**

[BinaExperts](https://binaexperts.com/fa) از فرمت‌های داده‌ی زیر پشتیبانی می‌کند:

***تصاویر:*** JPG، PNG، WEBP و BMP

**ویدئوها:** MOV و MP4

***داده‌هایی که به هر فرمت پشتیبانی شده برای طبقه‌بندی، تشخیص اشیا، تقسیم‌بندی و تشخیص نقاط کلیدی فرمت‌بندی شده‌اند.***

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F0xVFSFEQbjbZg35MeYom%2Fimage.png?alt=media&amp;token=8f19e45f-2dd1-4d49-b762-686f54828e45" alt=""><figcaption><p>انواع داده های پشتیبانی شده در <a href="https://binaexperts.com/fa">بینااکسپرتز</a></p></figcaption></figure>

**دسترسی به مجموعه داده‌های عمومی**

[BinaExperts Hub](https://binaexperts.com/fa/hub) یک مخزن شامل بیش از 10,000 مجموعه داده است که وظایفی مانند تشخیص اشیا، طبقه‌بندی و تقسیم‌بندی را پوشش می‌دهد. شما می‌توانید از این مخزن برای یافتن مجموعه داده‌ها جهت آموزش نسخه اولیه مدل یا برای تنظیم دقیق یک مدل موجود استفاده کنید.


# بارگذاری ویدیو

بارگذاری ویدیو در بینااکسپرتز.

بیشترین نرخ فریمی که می‌توانید انتخاب کنید، 60 فریم در ثانیه است که برای هر ثانیه از ویدیوی بارگذاری شده، 60 تصویر تولید می‌کند. کمترین نرخ فریم نیز 1 فریم در هر 60 ثانیه است.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FvISc1Fr9oXaaBXzd5YAJ%2F6.gif?alt=media&amp;token=90301985-ad79-4c47-bab6-ea47e5a8bc3b" alt=""><figcaption><p>انتخاب نرخ فریم برای هر ثانیه از ویدیوی بارگذاری شده در <a href="https://binaexperts.com/fa">بینااکسپرتز</a></p></figcaption></figure>

پس از نمونه‌برداری از ویدیوی شما، فریم‌های استخراج‌شده به گونه‌ای نمایش داده می‌شوند که انگار از ابتدا تصاویر را به [BinaExperts](https://binaexperts.com/fa) بارگذاری کرده‌اید.

همچنین می‌توانید ویدیویی از YouTube را مستقیماً با وارد کردن لینک آن در صفحه بارگذاری، به روش مشابه، وارد کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FLJif0pa2ytfnsAW7XVXV%2F7.png?alt=media&amp;token=98328447-1cb1-42e4-85ad-b51d04b618a0" alt=""><figcaption><p>وارد کردن لینک آدرس برای بارگذاری ویدیو در <a href="https://binaexperts.com/fa">بینااکسپرتز</a></p></figcaption></figure>

**فرمت‌های ویدیویی پشتیبانی‌شده**

[ BinaExperts](https://binaexperts.com/fa) از پشتیبانی داخلی مرورگر شما برای فایل‌های ویدیویی استفاده می‌کند تا آنها را به فریم‌های تصویری تبدیل کند که می‌توانید از آنها برای آموزش مدل‌های خود استفاده کنید. این بدان معناست که شما می‌توانید از انواع فرمت‌های ویدیویی، از جمله فایل‌های MOV و  MP4، بسته به مرورگری که استفاده می‌کنید، بهره ببرید.

&#x20;

لطفاً توجه داشته باشید که برخی از فرمت‌ها، مانند فایل‌های MP4 با کدگذاری HEVC/H.265، تنها توسط مرورگر Safari پشتیبانی می‌شوند. اگر از دستگاه‌هایی مانند GoPro یا iPhone که با H.265 ضبط می‌کنند، وارد می‌کنید، تنظیمات را به H.264 تغییر دهید تا سازگاری بیشتری داشته باشید.

&#x20;

اگر در بارگذاری فایل ویدیویی خود به [BinaExperts](https://binaexperts.com/fa) با مشکل مواجه شدید، می‌توانید با پشتیبانی از طریق ایمیل <help@BinaExperts.ir> تماس بگیرید.


# مدیریت دسته ها

## دسته‌ها در بینااکسپرتز

هنگامی که داده‌های خود را در [بینااکسپرتز](https://binaexperts.com/fa) بارگذاری می‌کنید، آن داده‌ها به یک دسته تبدیل می‌شوند. دسته‌ها گروهی از تصاویر هستند که می‌توانید به‌راحتی آن‌ها را در طول فرآیند دیتاست در بینااکسپرتز پیگیری کنید. شما می‌توانید این فرآیند را در صفحه "حاشیه‌نویسی" (Annotate) مشاهده کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FQjW49qLQVg0NYhou1Lut%2F40.JPG?alt=media&amp;token=17506f61-f756-4358-b52f-381125ff6d1d" alt=""><figcaption><p>مدیریت دسته ها در <a href="https://binaexperts.com/fa">بینااکسپرتز</a></p></figcaption></figure>

## مدیریت دسته‌ها

·        پس از بارگذاری تصاویر، آن‌ها در ستون "تخصیص‌نیافته" (Unassigned) قرار می‌گیرند.

&#x20;       شما می‌توانید دسته را به شخصی اختصاص دهید تا آن را حاشیه‌نویسی کند، که در این صورت دسته به ستون "در حال حاشیه‌نویسی" (Annotating) منتقل می‌شود.

·        اگر تنها بخشی از دسته را اختصاص دهید، تصاویر باقیمانده به عنوان یک دسته جدید در ستون "تخصیص‌نیافته" قرار می‌گیرند.

·        پس از تکمیل حاشیه‌نویسی، دسته یا به ستون "بررسی" (برای کاربرانی که دسترسی به حالت بررسی دارند) یا به ستون "دیتاست" منتقل می‌شود.

·        در ستون "بررسی"، دسته‌ها یا تأیید می‌شوند یا رد. دسته‌های تأیید شده به ستون "دیتاست" می‌روند و دسته‌های رد شده به ستون "در حال حاشیه‌نویسی" بازگردانده می‌شوند.

&#x20;

## حذف دسته

{% hint style="info" %}
توجه: حذف دسته دائمی و غیرقابل بازگشت است. لطفاً قبل از ادامه، از تصمیم خود مطمئن باشید.
{% endhint %}

&#x20;

برای حذف دسته، می‌توانید کادر کنار نام دسته را علامت زده و روی "حذف دسته" (**Delete Batch**) کلیک کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2Fo71yIPnwEBzC0H6jyQNM%2FScreenshot%20(1018).png?alt=media&amp;token=2251e8e3-3cea-4363-9240-a3949c02f29d" alt=""><figcaption><p>حذف دسته ها در <a href="https://binaexperts.com/fa">بینااکسپرتز</a></p></figcaption></figure>

حذف دسته بسته به اینکه دسته در کدام مرحله از فرآیند حاشیه‌نویسی قرار دارد، به دو صورت عمل می‌کند:

&#x20;

**ستون تخصیص‌نیافته(Unassigned):** اگر دسته در ستون "**تخصیص‌نیافته**" باشد، هم دسته و هم تصاویر داخل آن به‌طور دائمی از پروژه حذف می‌شوند.

**ستون‌های حاشیه‌نویسی، QC، دیتاست:** اگر دسته در یکی از این ستون‌ها باشد، دسته به ستون "تخصیص‌نیافته" بازگردانده می‌شود و تمام حاشیه‌نویسی‌های مرتبط با تصاویر آن حذف می‌شوند.

·        برای حذف کامل دسته‌ای که در این ستون‌ها قرار دارد، باید دو بار روی "**حذف دسته**" کلیک کنید: یک بار برای بازگرداندن آن به ستون "تخصیص‌نیافته" و بار دیگر برای حذف آن از ستون "تخصیص‌نیافته".

·        این روند در صورتی که بخواهید یک دسته را مجدداً برچسب‌گذاری کنید، باید دنبال شود.


# ایجاد یک نسخه از مجموعه داده

ایجاد یک نسخه از مجموعه داده به شما اجازه می‌دهد تا داده‌های خود را برای آموزش یک مدل آماده کنید.

نسخه‌ای از مجموعه داده، یک تصویر لحظه‌ای از مجموعه داده شما در یک نقطه زمانی است. شما با ردیابی دقیق تصاویری که استفاده شده‌اند، مراحل پیش‌پردازش و افزایش داده‌ها در هر تکرار مدل، توانایی بازتولید نتایج را حفظ می‌کنید. این اطمینان می‌دهد که می‌توانید مدل‌ها و فریم‌ورک‌های مختلف را به صورت علمی آزمایش کنید، در حالی که با اطمینان نتایج را به تغییرات مدل نسبت می‌دهید، نه به باگ‌ها یا تغییرات در مراحل ایجاد مغز هوش مصنوعی.

{% hint style="info" %}
پس از ایجاد یک نسخه، آن نسخه در زمان ثابت می‌شود. این بدان معناست که هر گونه تغییر بعدی در پروژه) مانند افزودن یا حذف تصاویر، حاشیه‌نویسی‌ها یا داده‌های دیگر (بر نسخه‌های قبلی تأثیری نخواهد داشت.
{% endhint %}

## نحوه ایجاد یک نسخه از مجموعه داده

برای ایجاد یک نسخه از مجموعه داده:

1\.       در نوار کناری پروژه [بینااکسپرتز](https://binaexperts.com/fa) خود، روی «**نسخه‌ها**» کلیک کنید.

روی «**ساخت نسخه جدید**» کلیک کنید

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FipnHpz2tSGtMmqbLf80W%2F43.JPG?alt=media&amp;token=69b9474c-5c2b-468c-92e6-83a868861cbe" alt=""><figcaption><p>ایجاد یک نسخه از مجموعه داده در <a href="https://binaexperts.com/fa">بینااکسپرتز</a></p></figcaption></figure>

در این صفحه می‌توانید:

·        تقسیم‌بندی **آموزش/آزمایش/اعتبارسنجی** را تنظیم کنید.

·        مراحل پیش‌پردازش را مشخص کنید.

·        افزایش داده‌ها را برای نسخه جدید مجموعه داده تعریف کنید.

پس از مشخص کردن مراحل پیش‌پردازش و افزایش داده‌هایی که می‌خواهید اعمال کنید، روی «**ساخت نسخه آماده آموزش**» کلیک کنید. این کار یک نسخه جدید از مجموعه داده ایجاد می‌کند. سپس می‌توانید از این نسخه برای آموزش یک مدل در [بینااکسپرتز](https://binaexperts.com/fa) استفاده کنید یا آن را برای آموزش دستی مدل صادر کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FH2ViGbVZ1u6eE6uua7lV%2F44.JPG?alt=media&amp;token=39c443d0-7200-4aa2-9014-1260191f6aea" alt=""><figcaption><p>تقسیم‌بندی <strong>آموزش/آزمایش/اعتبارسنجی در</strong> <a href="https://binaexperts.com/fa">بینااکسپرتز</a></p></figcaption></figure>

## تنظیم مجدد تقسیم‌بندی آموزش/اعتبارسنجی/آزمایش

در طول فرآیند ایجاد نسخه، می‌توانید تعادل مجموعه‌های آموزش، اعتبارسنجی و آزمایش را مجدداً تنظیم کنید. برای انجام این کار:

·        به «**مرحله ۴: تقسیم‌بندی آموزش/آزمایش**» بروید.

·        روی گزینه تنظیم تنظیمات تقسیم‌بندی کلیک کنید.


# پیش‌پردازش تصاویر

مراحل پیش‌پردازش تصاویر برای آماده‌سازی داده‌ها جهت مدل‌ها ضروری است.

پیش‌پردازش اطمینان می‌دهد که مجموعه داده شما به‌صورت استاندارد تنظیم شده است، به‌عنوان مثال، همه تصاویر دارای ابعاد یکسان هستند. این مرحله برای اطمینان از یکپارچگی مجموعه داده قبل از آموزش مدل ضروری است.

پیش‌پردازش روی تمام تصاویر در مجموعه‌های آموزشی، اعتبارسنجی و آزمون اعمال می‌شود (برخلاف افزونه‌ها که فقط روی مجموعه آموزشی اعمال می‌شوند).

## پلتفرم [بینااکسپرتز](https://binaexperts.com/fa) گزینه‌های پیش‌پردازش زیر را ارائه می‌دهد:

**·        چرخش خودکار**

**·        تغییر اندازه**

**·        سیاه و سفید کردن**

**·        تنظیم خودکار کنتراست**

**·        جداسازی اشیا**

**·        برش استاتیک**

**·        تقسیم‌بندی (Tile)**

**·        تغییر کلاس‌ها**

**·        فیلتر داده‌های نامعتبر**

**·        فیلتر بر اساس برچسب**

هر گزینه به تفصیل در زیر توضیح داده شده است.

## چرخش خودکار

گزینه چرخش خودکار، داده‌های EXIF را از تصاویر شما حذف می‌کند تا تصاویر همان‌طور که روی دیسک ذخیره شده‌اند، نمایش داده شوند.

داده‌های EXIF جهت نمایش تصویر را تعیین می‌کند. برخی برنامه‌ها (مانند Preview در مک) از این داده‌ها برای نمایش تصویر در یک جهت خاص استفاده می‌کنند، حتی اگر جهت ذخیره‌سازی تصویر در دیسک متفاوت باشد. این اختلاف می‌تواند باعث مشکلاتی در مدل‌های تشخیص اشیا شود. برای جزئیات بیشتر، به بحث‌های Hacker News در این زمینه مراجعه کنید.

[بینااکسپرتز](https://binaexperts.com/fa) توصیه می‌کند این گزینه را فعال نگه دارید و بررسی کنید که تصاویر شما در مرحله استنباط چگونه به مدل تغذیه می‌شوند.

برای اطلاعات بیشتر در مورد اینکه آیا باید تصاویر خود را به‌صورت خودکار چرخش دهید یا خیر، به [وبلاگ](https://blog.binaexperts.com/) ما مراجعه کنید.

## تغییر اندازه

گزینه تغییر اندازه، ابعاد تصاویر شما را تغییر می‌دهد و به صورت انتخابی آن‌ها را به یک اندازه مشخص مقیاس می‌کند. نشانه‌گذاری‌ها به تناسب تنظیم می‌شوند، به استثنای حالت **"پر کردن"** که در ادامه توضیح داده شده است.

در حال حاضر، تنها کاهش اندازه تصاویر پشتیبانی می‌شود. در زیر روش‌های موجود برای تغییر اندازه آورده شده است:

**کشش به اندازه مشخص:** تصاویر شما به ابعاد پیکسل به پیکسل دلخواه کشیده می‌شوند و نشانه‌گذاری‌ها به‌صورت تناسبی مقیاس می‌شوند. تصویر مربع خواهد بود اما تغییر شکل می‌دهد و هیچ داده‌ای از تصویر اصلی حذف نمی‌شود.

**پر کردن (با برش مرکزی):** تصویر خروجی بخشی مرکزی از تصویر اصلی است که به ابعاد خروجی مورد نظر بریده می‌شود. نسبت ابعاد حفظ می‌شود، اما داده‌های تصویر اصلی از بین می‌روند.

**تناسب درون ابعاد مشخص:** تصویر به گونه‌ای مقیاس می‌شود که در ابعاد خروجی مورد نظر جا بگیرد، در حالی که نسبت ابعاد اصلی حفظ می‌شود. داده‌های اصلی تصویر حفظ می‌شوند، اما ممکن است تصویر مربع نباشد.

**تناسب (با انعکاس لبه‌ها):** تصویر به ابعاد خروجی مقیاس می‌شود، در حالی که نسبت ابعاد اصلی حفظ می‌شود و هرگونه فضای خالی با انعکاس تصویر پر می‌شود. نشانه‌گذاری‌ها نیز به صورت پیش‌فرض منعکس می‌شوند.

**تناسب (با لبه‌های سیاه):** مشابه گزینه قبلی است، اما فضای خالی با رنگ سیاه پر می‌شود.

**تناسب (با لبه‌های سفید):** مشابه گزینه قبلی است، اما فضای خالی با رنگ سفید پر می‌شود.

## سیاه و سفید کردن

این گزینه تصویر با کانال‌های **RGB** را به تصویری با یک کانال سیاه و سفید تبدیل می‌کند که می‌تواند به صرفه‌جویی در حافظه کمک کند. مقدار هر پیکسل سیاه و سفید به‌صورت مجموع وزنی پیکسل‌های **قرمز، سبز** و **آبی** محاسبه می‌شود:

Y=0.2125R+0.7154G+0.0721BY = 0.2125R + 0.7154G + 0.0721BY=0.2125R+0.7154G+0.0721B

این ضرایب براساس نحوه‌ی ادراک انسان از رنگ‌های قرمز، سبز و آبی تعیین شده‌اند و معمولاً در تکنولوژی‌های نمایشگر به‌کار می‌روند.

## تنظیم خودکار کنتراست

تنظیم خودکار کنتراست تصاویر با کنتراست پایین را بهبود می‌دهد. [**بینااکسپرتز**](https://binaexperts.com/fa) روش‌های زیر را برای تنظیم کنتراست ارائه می‌دهد:

**کشش کنتراست:** شدت‌های پیکسلی بین صدک دوم و نود و هشتم بازتنظیم می‌شوند.

**همسان‌سازی هیستوگرام:** مقادیر شدت‌های پیکسلی پرتکرار بازتوزیع می‌شوند، به‌طوری‌که تمام رنگ‌های پیکسلی به‌صورت تقریباً یکنواخت نمایان شوند.

**همسان‌سازی تطبیقی:** الگوریتم CLAHE (همسان‌سازی هیستوگرام محدود شده با تطبیق کنتراست) برای افزایش کنتراست محلی استفاده می‌شود. این روش به‌ویژه برای بهبود جزئیات در نواحی تیره یا روشن تصویر مفید است.

## ویژگی‌های پیشرفته پیش‌پردازش

این ویژگی‌ها برای [فضای کاری عمومی و حساب‌های استارتر و سازمانی](https://binaexperts.com/fa/pricing) در دسترس است. کاربران فضای کاری سندباکس که به ویژگی‌های پیشرفته نیاز دارند، می‌توانند با تیم فروش تماس بگیرند.

## جداسازی اشیا

تبدیل جداسازی اشیا هر جعبه‌ی نشانه‌گذاری (bounding box) را برش داده و به یک تصویر مجزا تبدیل می‌کند. این گزینه برای تبدیل مجموعه داده‌های تشخیص اشیا به مجموعه داده‌های طبقه‌بندی مفید است.

در مجموعه داده‌هایی که شامل کلاس‌های مشابه زیادی هستند، معمولاً از دو مدل به‌صورت متوالی استفاده می‌شود: مدل اول (تشخیص اشیا) شی را پیدا می‌کند و مدل دوم (طبقه‌بندی) آن شیء را شناسایی می‌کند. تبدیل جداسازی اشیا برای ایجاد مجموعه داده‌های مورد نیاز برای آموزش مدل دوم مفید است.

## تقسیم‌بندی (Tile)

تقسیم‌بندی می‌تواند در تشخیص اشیای کوچک مفید باشد، به‌ویژه در موقعیت‌هایی مانند تصاویر هوایی یا میکروسکوپی. تنظیم پیش‌فرض تقسیم‌بندی 2x2 است، اما می‌توانید این تنظیم را به‌دلخواه تغییر دهید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FmZhCbBfLiG5tBUYQtrCR%2F19.JPG?alt=media&amp;token=aa331738-770c-407f-af18-ca72843b3413" alt=""><figcaption><p>تقسیم بندی در <a href="https://binaexperts.com/fa">بینااکسپرتز</a></p></figcaption></figure>

## فیلتر بر اساس برچسب

گزینه فیلتر بر اساس برچسب به کاربران اجازه می‌دهد تصاویری که باید در یک نسخه گنجانده شوند یا حذف شوند را بر اساس برچسب‌های اعمال‌شده فیلتر کنند. این گزینه برای آموزش مدل روی زیرمجموعه‌ای از داده‌ها یا حذف تصاویر نامطلوب از مجموعه داده مفید است.


# ایجاد تصاویر افزایش یافته

ایجاد تصاویر افزایش یافته یکی از مراحل مهم برای بهبود عملکرد مدل و افزایش توانایی آن در تعمیم‌دهی به داده‌های جدید است.

افزایش تصاویر شامل اعمال تغییرات بر روی تصاویر موجود در مجموعه داده شما است. این فرآیند می‌تواند به مدل شما کمک کند تا بهتر تعمیم داده شود و عملکرد مؤثرتری بر روی تصاویر جدید و دیده‌نشده داشته باشد.

## افزایش‌های پشتیبانی‌شده در [BinaExperts](https://binaexperts.com/fa):

**·        برگرداندن (Flip)**

**·        چرخش ۹۰ درجه**

**·        چرخش تصادفی**

**·        برش تصادفی**

**·        برش شیب تصادفی**

**·        تار کردن (Blur)**

**·        تنظیم نوردهی (Exposure)**

**·        نویز تصادفی**

**·        برش ناحیه (Cutout) (فقط در پلن‌های پولی)**

**·        موزائیک (Mosaic) (فقط در پلن‌های پولی)**

## توصیه‌هایی برای شروع یک پروژه:

{% hint style="success" %}
پیشنهاد می‌کنیم که پروژه خود را بدون هیچ‌گونه افزایش آغاز کنید. این کار به شما اجازه می‌دهد تا کیفیت مجموعه داده خام خود را ارزیابی کنید. اگر با اضافه کردن افزایش‌ها عملکرد مجموعه داده آن‌طور که انتظار دارید خوب نباشد، شما یک مبنا برای مقایسه‌ نخواهید داشت.

اگر مدل شما بدون افزایش‌ها خوب عمل نمی‌کند، ابتدا باید تعادل کلاس‌ها، نماینده داده‌ها و اندازه مجموعه داده را بررسی کنید. وقتی که مدل شما بدون افزایش‌ها عملکرد خوبی داشت، می‌توانید افزایش‌ها را برای بهبود بیشتر اضافه کنید.
{% endhint %}

## ایجاد تصاویر افزایش یافته پیش از آموزش

*انجام افزایش‌ها به‌صورت آفلاین (پیش از آموزش) چندین مزیت دارد:*

**افزایش بازتولیدپذیری مدل:** [BinaExperts](https://binaexperts.com/fa) رکوردی از نحوه افزایش هر تصویر نگه می‌دارد، که این امکان را می‌دهد تا به تنظیمات افزایش بازگردید. به عنوان مثال، اگر مدل شما روی تصاویر روشن بهتر عمل می‌کند، می‌توانید به این نتیجه برسید که به داده‌های آموزشی با نور کم بیشتری نیاز دارید.

**کاهش زمان آموزش:** افزایش‌ها عملیات‌های وابسته به CPU هستند. زمانی که افزایش‌ها به‌صورت آنی در زمان آموزش انجام می‌شوند، GPU شما معمولاً منتظر است تا CPU داده‌های افزوده‌شده را برای هر دوره آموزشی فراهم کند، که باعث کاهش سرعت می‌شود.

**کاهش هزینه‌های آموزش:** از آنجایی که افزایش‌ها عملیات‌های CPUمحور هستند، انجام آن‌ها به‌صورت آفلاین می‌تواند زمان انتظار برای GPU را کاهش داده و فرآیند آموزش را کارآمدتر و کم‌هزینه‌تر کند.

## افزودن افزایش‌ تصاویر

برای افزودن افزایش‌ تصاویر، به برگه "نسخه‌ها" (Versions) در داشبورد پروژه خود در [BinaExperts](https://binaexperts.com/fa) بروید. سپس روی "افزایش‌ها" (Augmentations) کلیک کنید تا تنظیمات مورد نظر را اعمال کنید.

{% hint style="info" %}
شما می‌توانید تعداد دفعات افزوده شدن هر تصویر را مشخص کنید. به عنوان مثال، انتخاب عدد ۳ به این معناست که هر تصویر شما دو بار بر اساس تنظیمات شما افزایش داده می‌شود، و در نتیجه سه نسخه از هر تصویر اصلی خواهید داشت.
{% endhint %}

## نحوه اعمال افزایش‌ تصاویر

افزایش‌ها به‌صورت زنجیروار با تنظیمات تصادفی بر روی هر تصویر اعمال می‌شوند. تصاویری که به عنوان تکراری ایجاد می‌شوند، از نسخه نهایی فیلتر می‌شوند.

به عنوان مثال، اگر گزینه "برگرداندن افقی" و "نویز نمک و فلفل" را انتخاب کنید، یک تصویر به‌طور تصادفی افقی برگردانده می‌شود و نویز نمک و فلفل به آن افزوده می‌شود.

## گزینه‌های افزایش و سفارشی‌سازی

در زیر افزایش‌های موجود در [BinaExperts](https://binaexperts.com/fa) و پارامترهای قابل تنظیم آن‌ها آورده شده است:

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2FQEGYersX1M17eNEdsc8S%2FRec%200006%20(1).gif?alt=media&amp;token=64b3ce95-1222-4229-b45a-8892bcde1981" alt=""><figcaption><p>افزایش‌های موجود در <a href="https://binaexperts.com/fa">BinaExperts</a> و پارامترهای قابل تنظیم آن‌ها </p></figcaption></figure>

**برگرداندن:** برگرداندن تصادفی تصاویر به‌صورت عمودی یا افقی با حفظ دقیق حاشیه‌نویسی‌ها.

·       **افقی:** تصویر را از چپ به راست برمی‌گرداند.

·        **عمودی:** تصویر را از بالا به پایین برمی‌گرداند.

**چرخش ۹۰ درجه:** چرخش تصاویر به‌صورت ۹۰ یا ۱۸۰ درجه.

·       **در جهت عقربه‌های ساعت:** چرخش ۹۰ درجه در جهت عقربه‌های ساعت.

·        **خلاف جهت عقربه‌های ساعت:** چرخش ۹۰ درجه در خلاف جهت عقربه‌های ساعت.

·        **وارونه:** چرخش ۱۸۰ درجه (وارونه).

**چرخش تصادفی:** چرخش تصادفی تصاویر در جهت یا خلاف جهت عقربه‌های ساعت تا مقدار مشخص‌شده.

**برش شیب تصادفی:** تحریف تصادفی تصاویر در محور افقی یا عمودی.

·       **افقی:** حداکثر میزان شیب در محور x.

·       **عمودی:** حداکثر میزان شیب در محور y.

**تار کردن:** اعمال تاری گوسی بر روی تصویر.

·        **پیکسل‌ها:** شدت تاری (حداکثر ۲۵ پیکسل).

**نویز تصادفی:** افزودن نویز نمک و فلفل به تصویر.

·        **درصد:** درصد پیکسل‌های تحت تاثیر (حداکثر ۲۵ درصد).

**تنظیمات رنگ:**

·        **رنگ، روشنایی، اشباع:** تغییر ظاهر رنگی تصاویر.

·       **کنتراست:** تغییر تفاوت بین نواحی روشن و تاریک.

**افکت‌های آب و هوایی:**

·        **برف:** شبیه‌سازی شرایط برفی.

·       **مه:** افزودن افکت‌های مه‌آلود.

·       **باران:** شبیه‌سازی قطرات باران.

·        **آفتاب:** افزودن افکت‌های نور آفتاب، با تغییر روشنایی و گرما.

این گزینه‌های افزایش به شما امکان می‌دهند تا تنوع بیشتری در مجموعه داده خود ایجاد کنید و استحکام مدل و توانایی تعمیم‌دهی آن به شرایط واقعی را بهبود ببخشید.


# افزودن تگ به تصاویر

سازماندهی مجموعه داده‌های خود را با تگ‌گذاری تصاویر بهبود دهید.

[بینااکسپرتز](https://binaexperts.com/fa) قابلیت تگ‌گذاری تصاویر را فراهم می‌کند. این قابلیت به شما این امکان را می‌دهد که هنگام آپلود تصاویر، تگ‌ها را به آن‌ها اختصاص دهید. می‌توانید از این تگ‌ها برای برچسب‌گذاری گروهی استفاده کنید، که دقت بیشتری را هنگام انتخاب تصاویر برای برچسب‌گذاری فراهم می‌کند. همچنین، تگ‌های تصاویر به عنوان یک فیلتر در جستجوی مجموعه داده‌های [بینااکسپرتز](https://binaexperts.com/fa) عمل می‌کنند و به شما کمک می‌کنند تا تصاویر خاصی را به‌راحتی مدیریت و پیدا کنید.

&#x20;

## فیلتر کردن تصاویر بر اساس تگ

در صفحه تخصیص (Assign) داشبورد [بینااکسپرتز](https://binaexperts.com/fa)، می‌توانید تصاویر را بر اساس تگ‌های اختصاص داده شده به آن‌ها فیلتر کنید.

&#x20;

همچنین می‌توانید با استفاده از مرحله پیش‌پردازش فیلتر بر اساس تگ، نسخه‌هایی از زیرمجموعه‌ای از تصاویر ایجاد کنید. این ویژگی به شما اجازه می‌دهد که تصاویر دارای تگ‌های خاص را از فرآیند آموزش حذف کنید یا آن‌ها را الزاماً در آموزش بگنجانید، که انعطاف‌پذیری بیشتری در سفارشی‌سازی مجموعه داده‌های آموزشی شما فراهم می‌کند.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F8DoMesurbQisdrSN9RY0%2FScreenshot%20(1019).png?alt=media&amp;token=d610ddc7-42c2-4092-b240-5db414041122" alt=""><figcaption><p>در صفحه تخصیص (Assign) داشبورد <a href="https://binaexperts.com/fa">بینااکسپرتز</a>، می‌توانید تصاویر را بر اساس تگ‌های اختصاص داده شده به آن‌ها فیلتر کنید.</p></figcaption></figure>


# مدیریت کلاس‌ها

قفل کردن، تغییر نقشه، یا حذف کلاس‌ها در پروژه

در صفحه کلاس‌ها می‌توانید کلاس‌های حاشیه‌نویسی خود را مشاهده، ویرایش و مدیریت کنید. هر تغییری که ایجاد می‌کنید بر تمام تصاویر پروژه شما تأثیر می‌گذارد، برخلاف برخی از مراحل پیش‌پردازشی که تنها بر یک نسخه خاص اعمال می‌شوند. بنابراین، قبل از ایجاد تغییرات باید مطمئن باشید که این اقدامات بر تمام تصاویر شما تأثیر می‌گذارد.

## دسترسی به صفحه کلاس‌ها

برای دسترسی به صفحه کلاس‌ها، کافیست روی کلاس‌ها در نوار کناری کلیک کنید.

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2Fc56uKLwtWUx4VHnUKEBZ%2FMockUp_1.jpg?alt=media&amp;token=7a5f0dc7-9078-412f-8aee-33585cf701ca" alt=""><figcaption><p>برای دسترسی به صفحه کلاس‌ها، کافیست روی کلاس‌ها در نوار کناری کلیک کنید.</p></figcaption></figure>

## تغییر نقشه کلاس‌ها

با کلیک روی دکمه ویرایش کلاس‌ها، می‌توانید به گزینه‌های تغییر نقشه کلاس‌ها دسترسی پیدا کنید. از این منو می‌توانید:

&#x20;

·        یک کلاس را تغییر نام دهید.

·        یک کلاس را حذف کنید. (با کلیک روی حذف)

{% hint style="info" %}
**هشدار:** این اقدامات غیرقابل بازگشت هستند و ممکن است تأثیرات مهمی بر پروژه شما داشته باشند. قبل از ادامه، از تصمیم خود مطمئن شوید.
{% endhint %}

<figure><img src="https://1703512193-files.gitbook.io/~/files/v0/b/gitbook-x-prod.appspot.com/o/spaces%2FHyQ97PzHJLIjjc4Xnm9y%2Fuploads%2F6lVSNxS5IdahwMRzFYmI%2F47.JPG?alt=media&amp;token=df2bf389-de7e-4980-b069-d9bb1a78b040" alt=""><figcaption><p>با کلیک روی دکمه ویرایش کلاس‌ها، می‌توانید به گزینه‌های تغییر نقشه کلاس‌ها دسترسی پیدا کنید.</p></figcaption></figure>


# Page 3


# Page 4


---

[Next Page](https://docs.binaexperts.com/llms-full.txt/1)